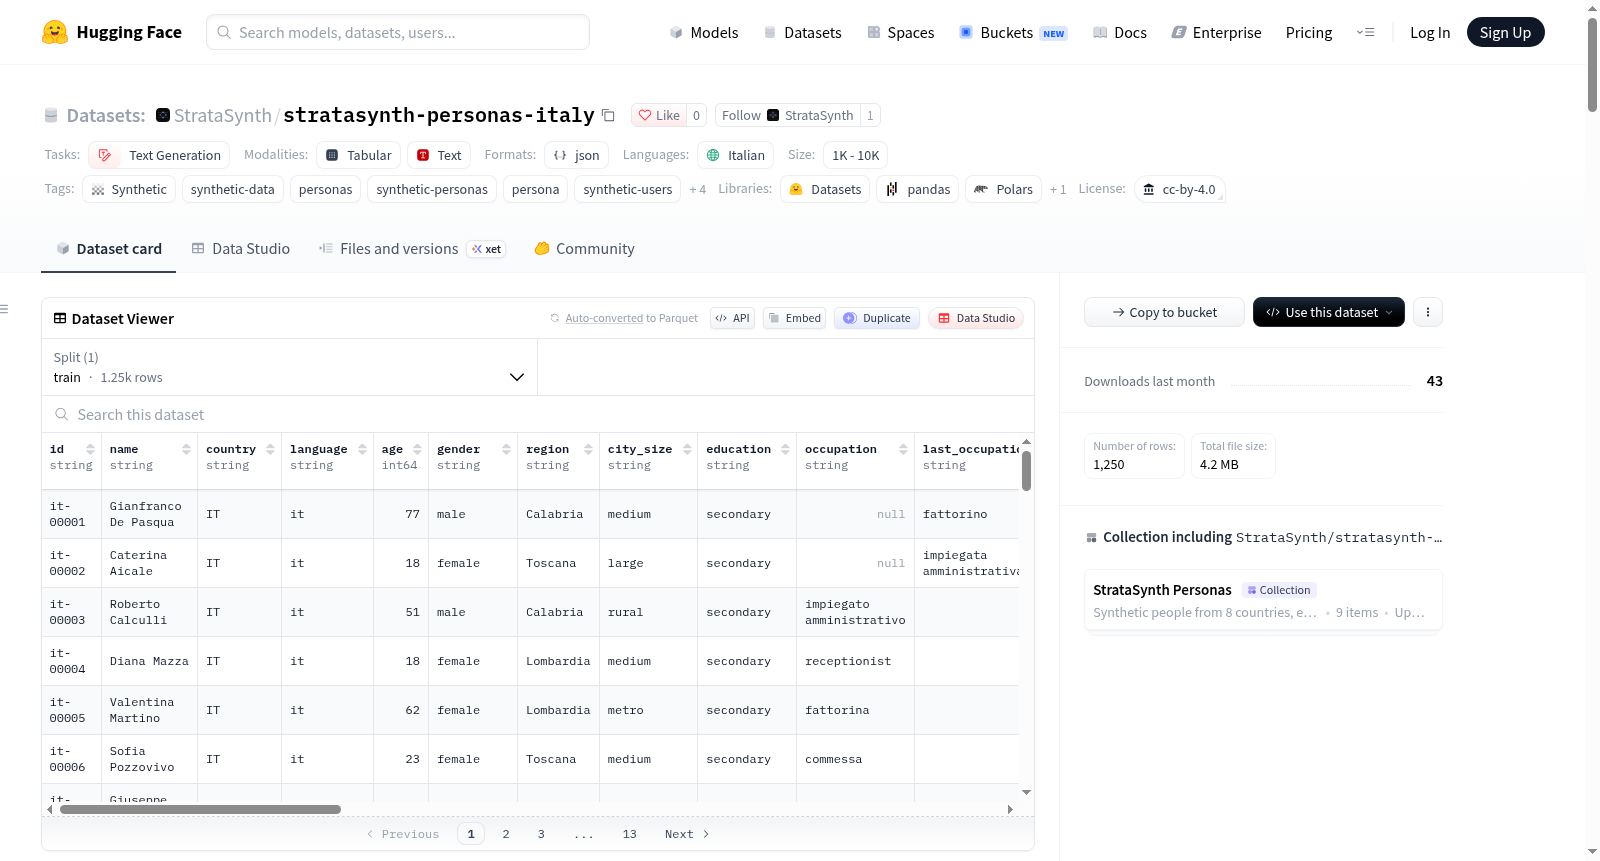
stratasynth-personas-italy
收藏资源简介:
StrataSynth Personas Italy 是一个包含 1,250 个合成意大利人物的数据集,所有文本以意大利语撰写。每个样本包含 27 个字段,涵盖个人基本属性(如年龄、性别、地区、教育水平、职业、收入等级)、家庭结构、日常活动、传记(persona)、说话风格、爱好与兴趣、技能、未来目标、人格特质(大五人格 0-1 评分和成人依恋类型)以及消费者画像(购物风格、价格敏感度、品牌忠诚度、可持续性关注、技术采纳)。数据集的 v2 版本引入了基于各国真实教育水平和年龄的家庭收入分布(低/中/高),以及按性别和年龄调整的就业状态,以更真实地反映意大利成年人口。人物年龄范围为 18-85 岁,中位数 51 岁,覆盖 19 个地区。该数据集旨在为意大利本地化的聊天机器人、智能体提供真实的模拟用户,用于测试、偏见检查、公平性评估,以及生成意大利语合成数据(如“写出这个人会问的问题”)和预测试调查、产品与信息。所有人物均为完全合成,不指向任何真实个体,名称基于真实频率。数据集采用 CC BY 4.0 许可。
StrataSynth Personas Italy is a dataset containing 1,250 synthetic Italian personas, all text written in Italian. Each sample includes 27 fields covering basic personal attributes (such as age, gender, region, education level, occupation, income level), family structure, daily activities, biography (persona), speaking style, hobbies and interests, skills, future goals, personality traits (Big Five personality 0-1 scores and adult attachment styles), and consumer profiles (shopping style, price sensitivity, brand loyalty, sustainability concerns, technology adoption). The v2 version introduces household income distribution (low/medium/high) based on real education levels and ages by country, as well as employment status adjusted by gender and age, to more accurately reflect the Italian adult population. The personas range in age from 18 to 85 years old, with a median of 51, covering 19 regions. The dataset is designed to provide realistic simulated users for Italian-localized chatbots and agents, for testing, bias checking, fairness evaluation, generating Italian synthetic data (such as write the questions this person would ask), and pre-testing surveys, products, and information. All personas are entirely synthetic and do not refer to any real individuals; names are based on real frequencies. The dataset is licensed under CC BY 4.0.
StrataSynth Personas Italy 数据集概述
基本信息
- 数据集地址:https://huggingface.co/datasets/StrataSynth/stratasynth-personas-italy
- 许可证:CC BY 4.0
- 语言:意大利语(it)
- 数据规模:1,250 个合成人物,每人 27 个字段,覆盖意大利 19 个大区
- 数据文件:personas_it.jsonl(train 划分)
- 任务类别:文本生成
- 规模类别:1K<n<10K
数据集简介
该数据集包含 1,250 个来自意大利的合成人物,使用意大利语撰写。每个人物均包含传记、说话方式、爱好、技能、目标以及可量化的人格特征。
本数据集是 StrataSynth Personas 系列的一部分(该系列包含八个国家、共 10,000 人)。完整集合地址:https://huggingface.co/datasets/StrataSynth/stratasynth-personas-8-countries
v2 版本更新
- 真实收入:
income_level遵循各国按教育程度和年龄划分的家庭收入真实分布(low= 后 30%,medium= 中间 40%,high= 前 30%),职业与之保持一致。 - 真实就业:就业与失业人口比例遵循各国按性别和年龄划分的官方比率。
数据集特点
- 真实人口而非刻板印象:年龄、地区、教育、收入、居住安排和家庭结构遵循该国真实成年人口分布。子女年龄与父母年龄匹配,姓名遵循各代际的真实姓名频率。
- 使用意大利语撰写:传记、日常作息、说话风格、爱好、技能和目标均为本地原生撰写,而非翻译。
- 可筛选的人格特征:每个人均包含大五人格(0-1)和成人依恋。更外向的人拥有更多社交类爱好;更开放的人拥有更多文化和学习导向的爱好。
- 可直接用作模拟用户:传记加上说话方式即可满足用户模拟器需求,将其放入提示词即可获得来自意大利的客户、患者或受访者。
人口统计特征
- 年龄:18-85 岁,中位数 51 岁。
- 就业状况:54% 在职,20% 退休,10% 居家,5% 失业,8% 求学。
- 住房:51% 拥有自有住房,32% 租房,16% 住在家庭住房。
- 与父母同住:16% 的成年人。
使用场景
- 在正式上线前,使用真实的本地用户测试为意大利构建的聊天机器人和智能体。
- 跨年龄、性别和地区进行公平性与偏见检查。
- 为意大利语合成数据提供种子:"写出这个人会问的问题"。
- 作为合成受访者,用于预测试调查、产品和信息传达。
字段说明
| 字段 | 类型 | 说明 |
|---|---|---|
id |
string | 国家代码 + 编号,例如 es-00001 |
name |
string | 全名。西班牙、墨西哥和巴西按当地习俗使用双姓 |
country |
string | ES、MX、US、GB、DE、FR、IT、BR |
language |
string | 所有文本字段的语言:es、en、de、fr、it、pt |
age |
int | 18 至 85 |
gender |
string | male、female、non_binary |
region |
string | 国内大区(巴西为宏观区域) |
city_size |
string | rural、small、medium、large、metro |
education |
string | secondary、vocational、university、postgrad |
occupation |
string | null |
last_occupation |
string | null |
income_level |
string | low、medium、high,相对于所在国家 |
household_type |
string | single、couple、family_young、family_teen、empty_nester |
marital_status |
string | single、partnered、married、divorced、widowed |
children |
int | 子女数量 |
children_ages |
list[int] | 子女的年龄 |
housing |
string | owned、rented、family_home |
employment_status |
string | employed、unemployed、student、retired、homemaker、other |
lives_with_parents |
bool | null |
daily_routine |
string | 典型的一天,使用该人物的语言 |
persona |
string | 传记,使用该人物的语言 |
speaking_style |
string | 人物的说话方式:语气、长度、词汇、习惯,使用该人物的语言 |
hobbies_and_interests |
list[string] | 五项爱好与兴趣 |
skills |
list[string] | 三到六项技能 |
goals |
list[string] | 未来一到三个目标 |
consumer |
object | shopping_style、price_sensitivity、brand_loyalty、sustainability_concern、tech_adoption |
personality.big_five |
object | O 开放性、C 尽责性、E 外向性、A 宜人性、N 神经质,0 至 1 |
personality.attachment |
object | 成人依恋 anxiety(焦虑)和 avoidance(回避),0 至 1 |
加载方式
python from datasets import load_dataset people = load_dataset("StrataSynth/stratasynth-personas-italy", split="train")
示例数据
json { "id": "it-00003", "name": "Roberto Calculli", "country": "IT", "language": "it", "age": 51, "gender": "male", "region": "Calabria", "city_size": "rural", "education": "secondary", "occupation": "impiegato amministrativo", "last_occupation": null, "income_level": "high", "household_type": "family_teen", "marital_status": "married", "children": 2, "children_ages": [16, 19], "housing": "owned", "employment_status": "employed", "lives_with_parents": false }
备注
- 每个人物均为完全合成。他们不是真实人物或任何机构的记录,与真实人物的任何相似之处均属巧合。
- 姓名取自真实姓名频率,因此合成人物可能与真实人物同名。
许可
CC BY 4.0。使用时请注明 StrataSynth。