CanadaHonk/ecma262-qa-synth-v1
收藏资源简介:
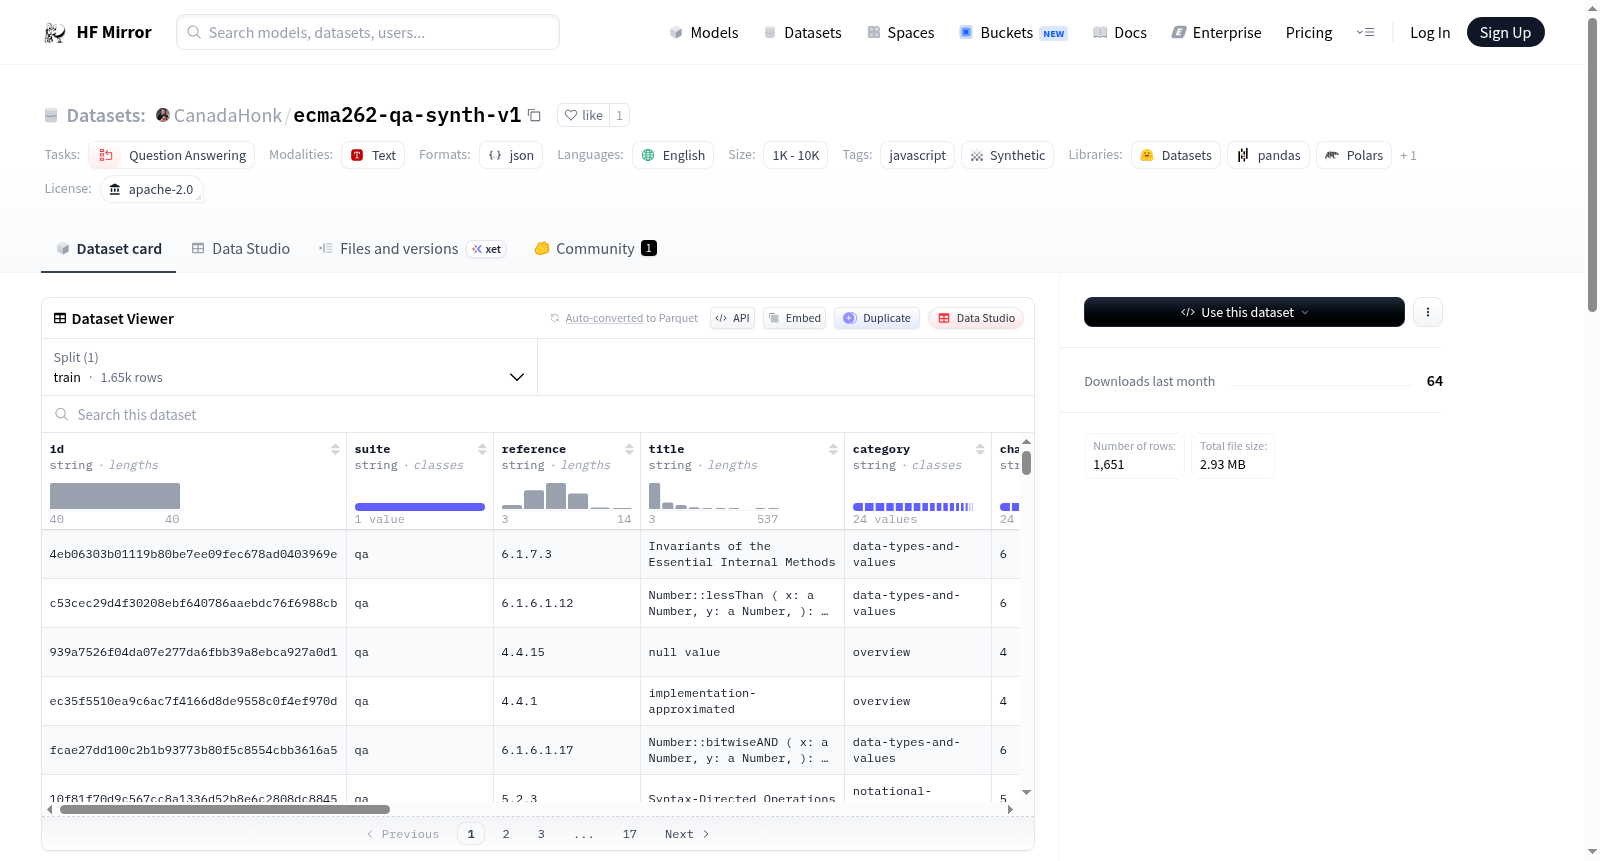
--- pretty_name: 262QA size_categories: - 1K<n<10K task_categories: - question-answering configs: - config_name: default data_files: - split: train path: data/train.jsonl tags: - javascript - synthetic language: - en license: apache-2.0 --- # 262QA (`ecma262-qa-synth-v1`) > [!CAUTION] > This dataset is experimental and not human-validated. It is published as a proof-of-concept to be potentially useful for experiments instead of sitting on a disk. If you are interested in serious use, [let's chat](mailto:honk@goose.icu)! Have fun :) This dataset contains a synthetic full-coverage question-answer corpus of ECMA-262. This was originally generated for an LLM benchmark which may be published in the future. - Rows: 1651 - Split: `train` - Format: JSON Lines (`data/train.jsonl`) - Provenance manifest: `manifest.json` - Spec source: `tc39/ecma262 @ 4895a117eb54edd829f2010092bae8f41c2b174a` --- Each row is a short-answer, source-grounded question tied to one spec clause and includes: - `id` - `suite` - `reference` - `title` - `category` - `chapterReference` - `chapterTitle` - `difficulty` - `questionKind` - `question` - `canonicalAnswer` - `acceptedAnswers` - `canonicalExplanation` - `evidence` - `sourceExcerpt` --- ```python from datasets import load_dataset ds = load_dataset("CanadaHonk/ecma262-qa-synth-v1") print(ds["train"][0]) ```