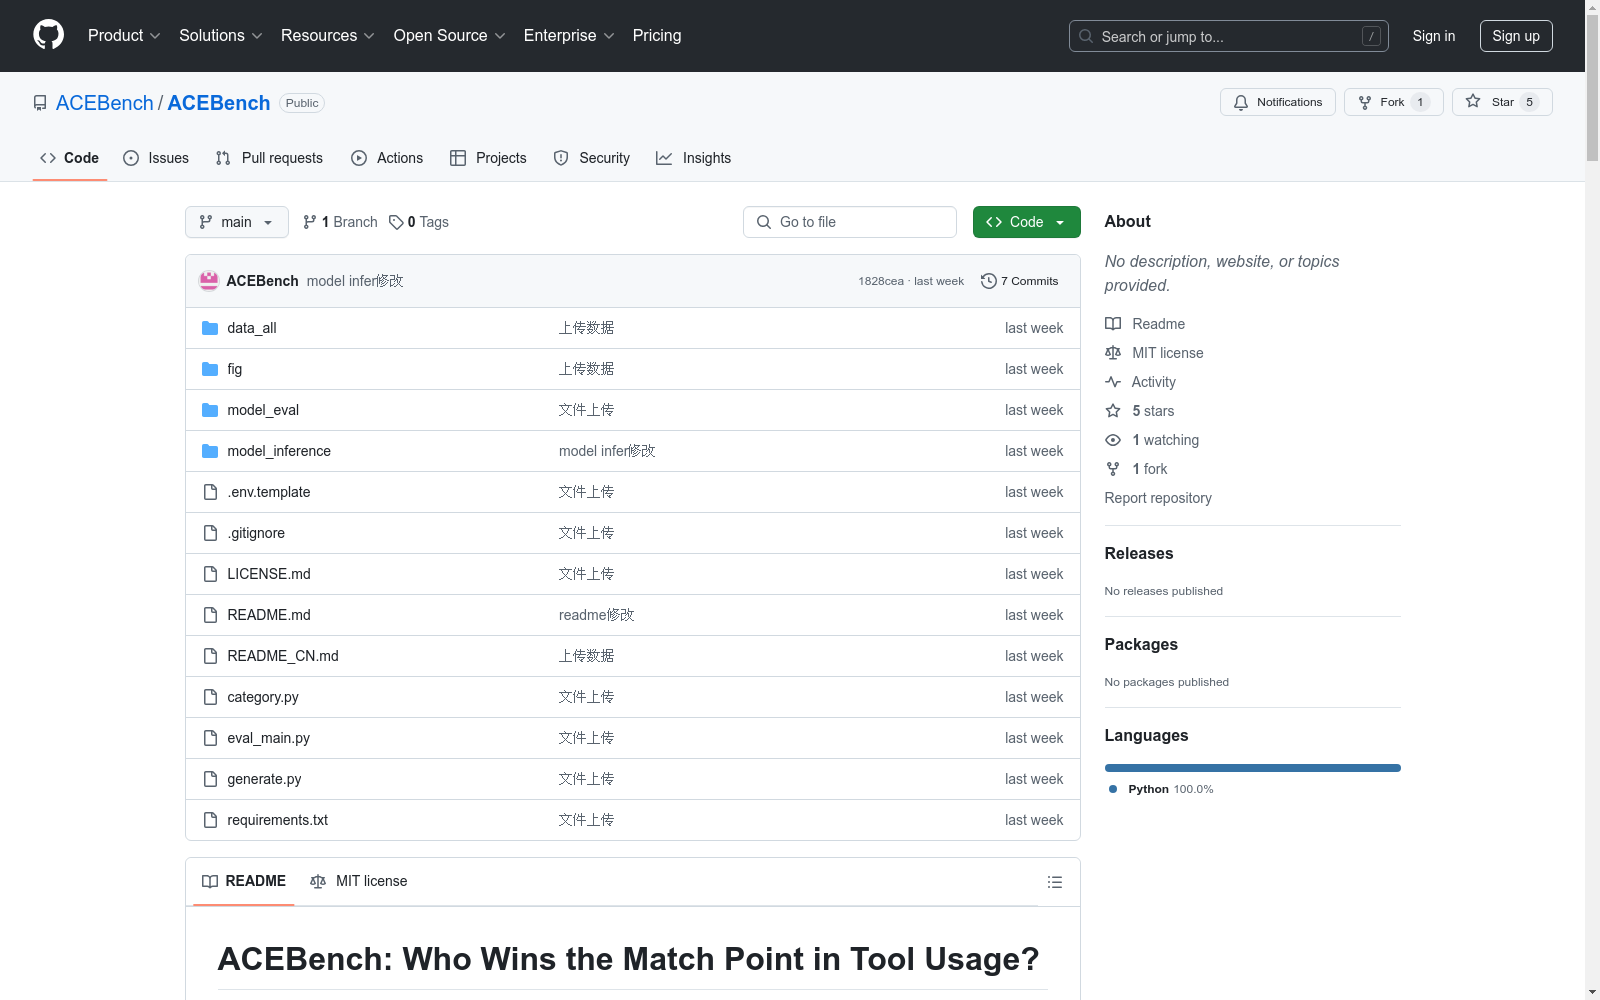
ACEBench
收藏资源简介:
ACEBench是一个全面的基准数据集,用于评估大型语言模型在工具使用方面的性能。它将数据分为三种主要类型:正常、特殊和代理,以不同的评估方法对工具使用进行评估。
ACEBench is a comprehensive benchmark dataset designed to evaluate the performance of Large Language Models (LLMs) in tool use. It divides the dataset into three main categories: normal, special, and agent, and adopts diverse evaluation methods to assess tool use performance.
ACEBench 数据集概述
1. 数据集简介
- 名称: ACEBench
- 目的: 评估大语言模型(LLMs)的工具使用能力
- 特点:
- 解决现有基准测试的局限性
- 提供多维度评估
- 避免依赖真实API执行带来的开销
2. 数据类型
- Normal: 基础工具使用场景
- Special: 处理模糊或不完整指令的场景
- Agent: 多智能体交互模拟真实多轮对话
3. 数据统计
- API覆盖:
- 8个主要领域
- 68个子领域
- 4,538个中英文API
- 领域分布: 技术、金融、娱乐、社会、健康、文化、环境等
4. 数据组成
- 包含三种主要测试样本类型:
- Normal
- Agent
- Special
5. 模型性能排行榜
- 闭源模型:
- 表现最佳: gpt-4o-2024-11-20 (整体得分0.896)
- 其他高分模型: gpt-4-turbo-2024-04-09, qwen-max
- 开源模型:
- 表现最佳: Qwen2.5-Coder-32B-Instruct-local (整体得分0.853)
- 其他高分模型: Qwen2.5-32B-Instruct-local, Qwen2.5-72B-Instruct-local
6. 数据存储结构
data_all/
├── possible_answer_en/
│ ├── data_{normal}.json
│ ├── data_{special}.json
│ ├── data_{agent}.json
├── possible_answer_zh/
│ ├── data_{normal}.json
│ ├── data_{special}.json
│ ├── data_{agent}.json
...
7. 使用方式
- 推理:
- 使用
generate.py脚本 - 支持不同模型、类别和语言
- 使用
- 评估:
- 使用
eval_main.py脚本 - 支持多种评估指标
- 使用
8. 引用
bibtex @article{chen2025acebench, title={ACEBench: Who Wins the Match Point in Tool Learning?}, author={Chen, Chen and Hao, Xinlong and Liu, Weiwen and Huang, Xu and Zeng, Xingshan and Yu, Shuai and Li, Dexun and Wang, Shuai and Gan, Weinan and Huang, Yuefeng and others}, journal={arXiv preprint arXiv:2501.12851}, year={2025} }