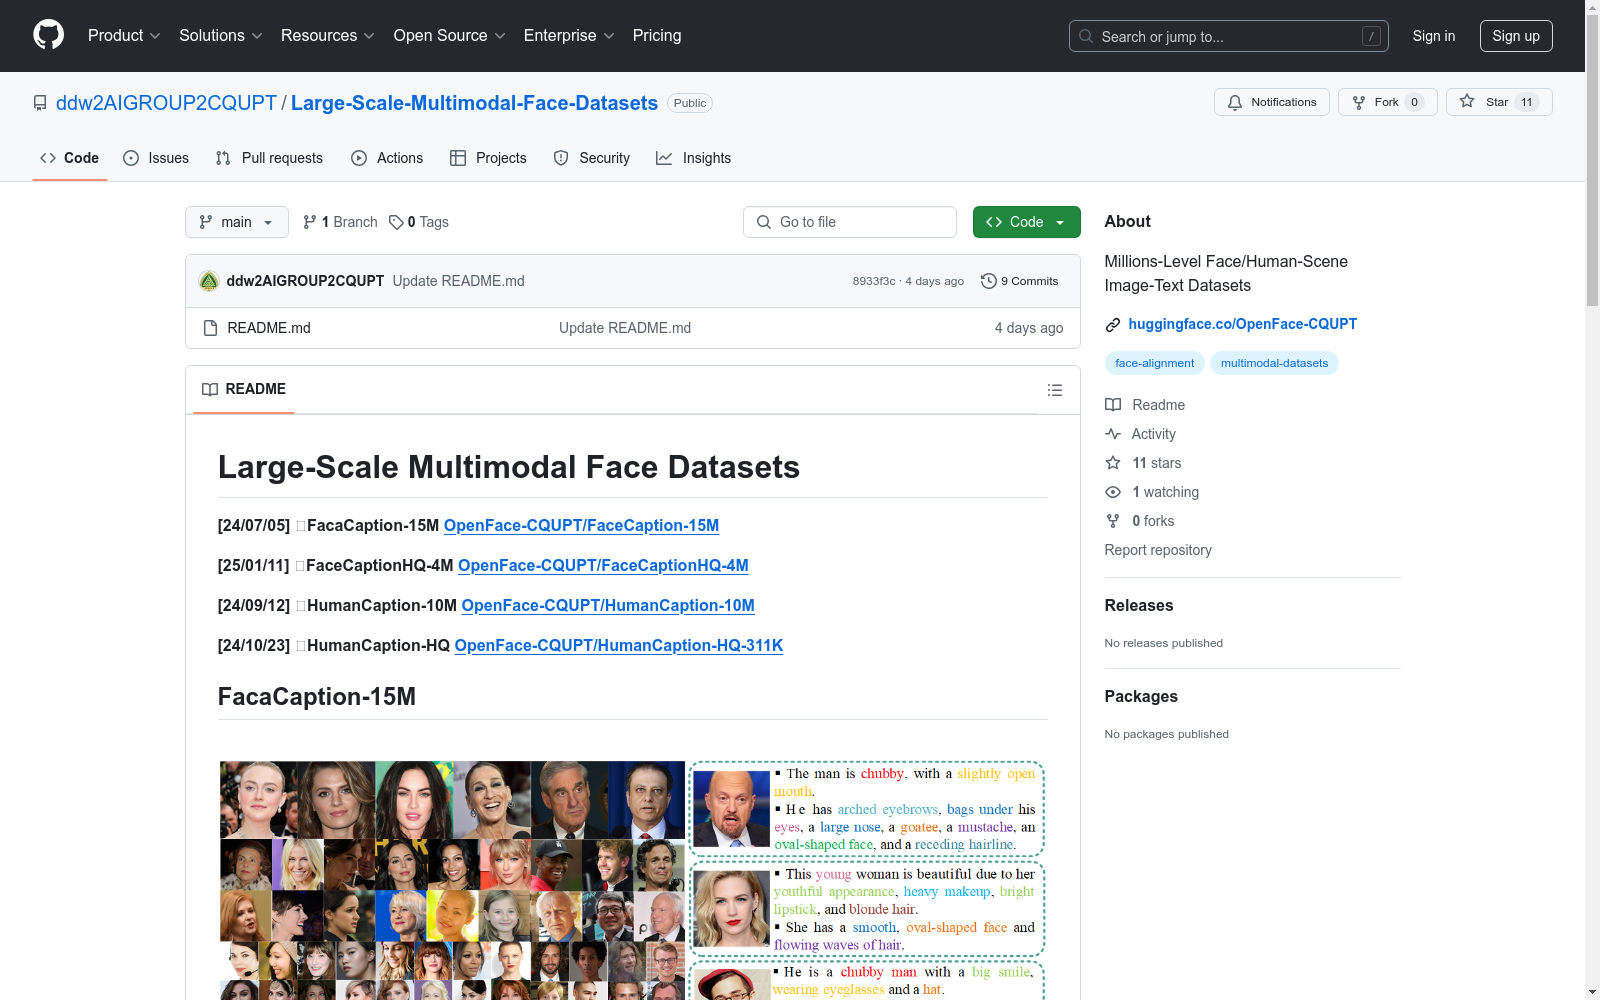
FaceCaption-15M, FaceCaptionHQ-4M, HumanCaption-10M, HumanCaption-HQ
收藏资源简介:
FaceCaption-15M是一个大规模、多样化且高质量的面部图像数据集,附带自然语言描述(面部图像到文本)。该数据集旨在促进面部中心任务的研究。FaceCaption-15M包含超过1500万对的面部图像及其对应的面部特征自然语言描述,是目前最大的面部图像字幕数据集。FaceCaptionHQ-4M包含约400万对从FaceCaption-15M中清理出的面部图像-文本对。HumanCaption-10M是一个大规模、多样化且高质量的人类相关图像数据集,附带自然语言描述(图像到文本)。该数据集旨在促进人类中心任务的研究。HumanCaption-10M包含约1000万张人类相关图像及其对应的面部特征自然语言描述,是FaceCaption-15M的第二代版本。HumanCaption-HQ包含约31.1万张人类相关图像及其对应的自然语言描述。与HumanCaption-10M相比,该数据集不仅包括相关的面部语言描述,还筛选出更高分辨率的图像,并利用GPT-4V的强大视觉理解能力生成更详细和准确的文本描述。
FaceCaption-15M is a large-scale, diverse, and high-quality facial image dataset paired with natural language descriptions for facial image-to-text tasks. It aims to advance research in face-centric tasks. FaceCaption-15M contains over 15 million facial image-text pairs with corresponding natural language descriptions of facial features, making it the largest facial image captioning dataset to date. FaceCaptionHQ-4M includes approximately 4 million curated facial image-text pairs filtered from FaceCaption-15M. HumanCaption-10M is a large-scale, diverse, and high-quality human-centric image dataset paired with natural language descriptions for image-to-text tasks, designed to promote research in human-centric tasks. It contains roughly 10 million human-related images paired with corresponding natural language descriptions of facial features, and is the second-generation iteration of FaceCaption-15M. HumanCaption-HQ includes approximately 311,000 human-related images paired with corresponding natural language descriptions. Compared with HumanCaption-10M, this dataset not only covers relevant facial language descriptions, but also screens out higher-resolution images, and leverages the powerful visual understanding capabilities of GPT-4V to generate more detailed and accurate textual descriptions.
大规模多模态人脸数据集概述
数据集列表
-
FaceCaption-15M
- 描述: 一个大规模、多样化且高质量的人脸图像数据集,包含超过1500万对人脸图像及其对应的自然语言描述(人脸图像到文本)。该数据集旨在促进以人脸为中心的任务研究。
- 特点:
- 包含1500万对人脸图像和文本描述。
- 是目前最大的人脸图像描述数据集。
- 更新:
- 2024年9月1日,发布了FaceCaption-15M的图像嵌入。
-
FaceCaptionHQ-4M
- 描述: 包含约400万对人脸图像-文本对,这些数据是从FaceCaption-15M中清理出来的。
- 特点:
- 数据经过清理,质量更高。
- 包含400万对人脸图像和文本描述。
-
HumanCaption-10M
- 描述: 一个大规模、多样化且高质量的人类相关图像数据集,包含约1000万张人类相关图像及其对应的自然语言描述(图像到文本)。该数据集旨在促进以人类为中心的任务研究。
- 特点:
- 包含1000万张人类相关图像和文本描述。
- 是FaceCaption-15M的第二代版本。
-
HumanCaption-HQ
- 描述: 包含约31.1万张人类相关图像及其对应的自然语言描述。与HumanCaption-10M相比,该数据集不仅包含相关的面部语言描述,还筛选出更高分辨率的图像,并利用GPT-4V的强大视觉理解能力生成更详细和准确的文本描述。
- 特点:
- 包含31.1万张人类相关图像和文本描述。
- 用于第二阶段训练HumanVLM,增强模型在描述生成和视觉理解方面的能力。
数据集链接