gemma4-materials-mechanism-prompts
收藏资源简介:
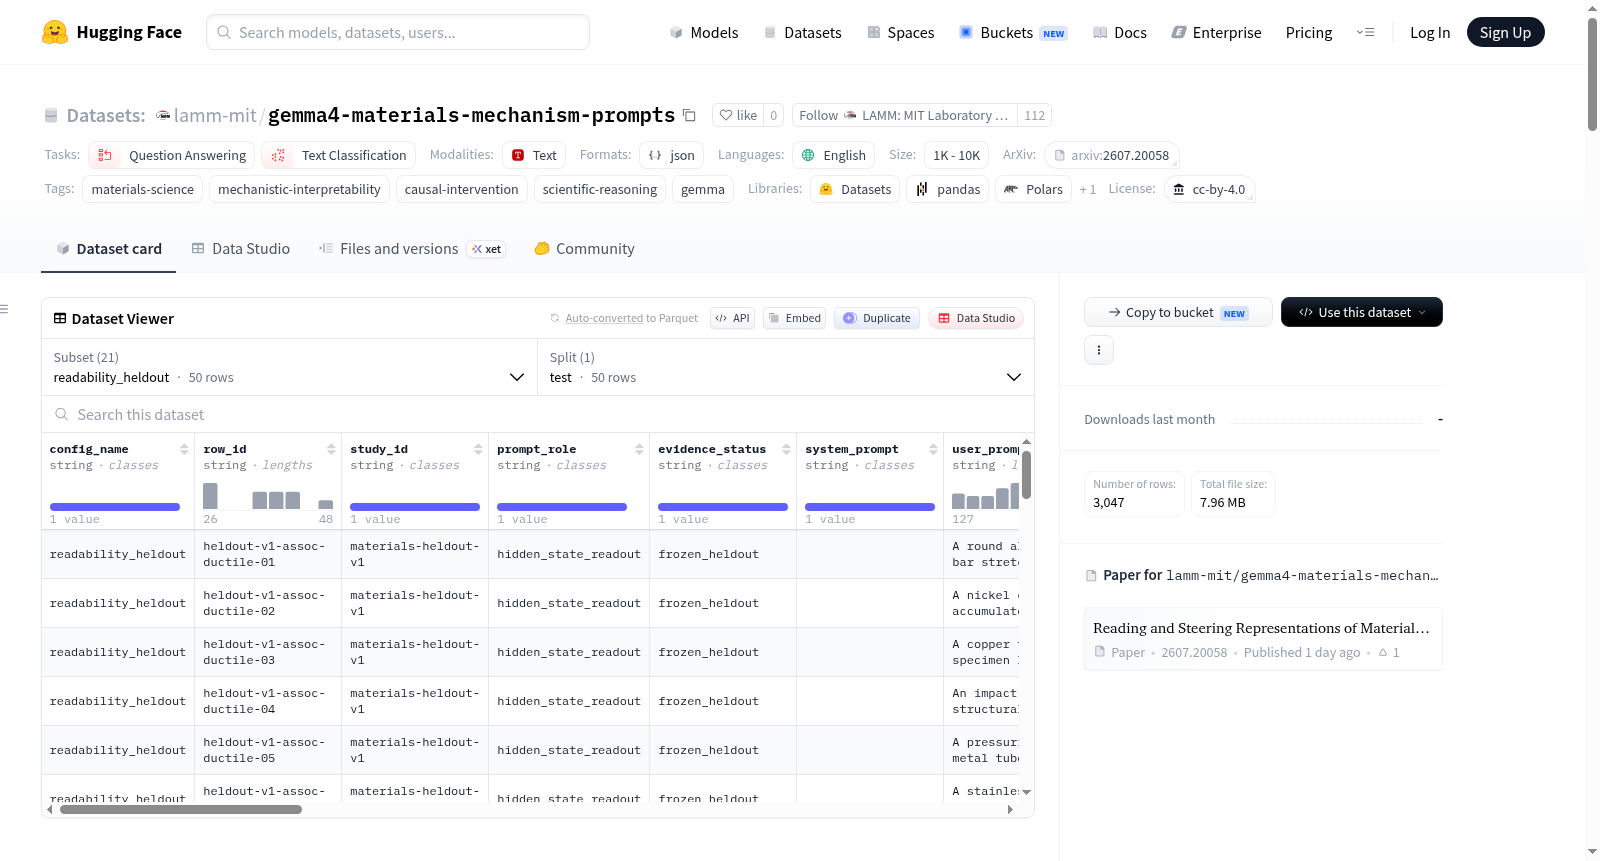
Gemma 4 Materials-Mechanism Prompt Corpus 是一个用于研究开放权重语言模型中材料科学机制表示可解释性的提示词数据集。它收集了论文《Reading and Steering Materials Science-Mechanism Representations in an Open-Weight Language Model》中使用的精确科学提示词和相关元数据,旨在作为提示词和协议资源,而非现成的训练集。数据集通过21个Hugging Face配置进行组织,涵盖历史开发提示词、冻结评估、证伪测试和探索性后续研究,总计3,047行(提示词出现次数)。所有配置共享统一的字段结构,包括`system_prompt`、`user_prompt`、`expected_answer`、`answer_options`等模型交互文本,以及`family_id`、`domain`、`relation`、`law_id`等科学分组和关系物理元数据,还包含`prompt_role`、`evidence_status`、`split`等实验角色信息。数据规模在1K到10K之间,适用于问答和文本分类任务,具体场景包括材料科学机制表示的可读性分析、因果干预实验、关系物理推理以及探索性边界研究。数据集强调其特定研究范围,预期标签不应被视为超出原论文范围的专家评审事实,若用于训练需注意避免数据污染。数据集以CC-BY-4.0许可证发布,语言为英语,关联模型为google/gemma-4-E4B-it。
Gemma 4 Materials-Mechanism Prompt Corpus is a prompt dataset for studying the interpretability of materials science mechanism representations in open-weight language models. It collects exact scientific prompts and registered metadata used in the paper Reading and Steering Materials Science-Mechanism Representations in an Open-Weight Language Model, intended as a prompt and protocol resource rather than a ready-made training set. The dataset is organized via 21 Hugging Face configurations, covering historical development prompts, frozen evaluations, falsification tests, and exploratory follow-up studies, totaling 3,047 rows (prompt occurrences). All configurations share a unified field structure, including model interaction text such as `system_prompt`, `user_prompt`, `expected_answer`, `answer_options`, as well as scientific grouping and relational physics metadata like `family_id`, `domain`, `relation`, `law_id`, and experimental role information such as `prompt_role`, `evidence_status`, `split`. The data scale ranges from 1K to 10K, suitable for question answering and text classification tasks, with specific scenarios including readability analysis of materials science mechanism representations, causal intervention experiments, relational physics reasoning, and exploratory boundary studies. The dataset emphasizes its specific research scope, and expected labels should not be considered as expert-reviewed facts beyond the original papers context; caution is needed to avoid data contamination if used for training. It is released under the CC-BY-4.0 license, in English language, and associated with the model google/gemma-4-E4B-it.
数据集概述
Gemma 4 Materials-Mechanism Prompt Corpus 是一个为研究材料科学机理表示而设计的提示词(prompt)数据集,由 Markus J. Buehler 创建。该数据集用于论文 “Reading and Steering Representations of Materials-Science Mechanisms in an Open-Weight Language Model”,专门用于探究开放权重语言模型(google/gemma-4-E4B-it)在材料科学领域的因果干预与可解释性。
- 语言:英语
- 许可证:Creative Commons Attribution 4.0 International(CC-BY-4.0)
- 任务类别:问答、文本分类
- 数据规模:1,000 < n < 10,000 条
- 标签:材料科学、机械可解释性、因果干预、科学推理
数据集结构与配置
数据集共包含 21 个配置(configurations),总计 3,047 条提示。每个配置对应不同的实验目的和证据状态。所有配置共享相同的字段模式(schema),包括系统提示、用户提示、预期答案、答案选项、科学分组元数据、角色、证据状态与分割等。
可读性与开放词汇解释
| 配置名称 | 行数 | 目的 | 证据状态 |
|---|---|---|---|
readability_heldout |
50 | 控制词汇与开放词汇的隐藏状态读出 | 冻结的保留集 |
readability_development_122 |
122 | 早期开发阶段的异质读出集 | 仅开发,非总体证据 |
option_free_questions |
72 | 自然问题,无可见答案选项 | 冻结的现有队列 |
automated_interpreter |
5 | 用于分类发现的词汇集的盲审提示 | 回顾性二次分析 |
lexical_adversarial_discovery |
72 | 分离词汇表面线索与物理关系的匹配提示 | 冻结的发现队列 |
lexical_adversarial_replication |
72 | 对词汇对抗设计的独立复制 | 冻结的复制集 |
answer_code_binding |
72 | A/B 答案代码控制的预期性证伪测试 | 失败的操控检查,已如实报告 |
因果干预
| 配置名称 | 行数 | 目的 | 证据状态 |
|---|---|---|---|
steering_initial_pilot |
15 | 早期 A/B 干预试验 | 仅开发,非主要证据 |
steering_layer_selection |
18 | 用于初步层比较的校准提示 | 仅开发,用于层选择 |
steering_preliminary_confirmation |
24 | 早期 A/B 确认提示 | 仅开发,非主要证据 |
steering_direction_fit |
9 | 每个机理家族三个提示,用于拟合干预方向 | 冻结的方向拟合集 |
steering_broad_screen |
60 | 30 种物理条件,包含两种答案顺序 | 冻结的确认性筛选 |
steering_grain_confirmation |
24 | 预期的晶粒细化/粗化接收器,包含两种答案顺序 | 冻结的预期性确认 |
关系物理
| 配置名称 | 行数 | 目的 | 证据状态 |
|---|---|---|---|
relational_development |
128 | 16 条定律的初始队列,用于开发关系状态分析 | 仅开发 |
relational_fresh_screen |
256 | 开发分析后的新一轮 16 条定律筛选 | 冻结的新鲜筛选 |
relational_disjoint_confirmation |
192 | 12 条定律的独立确认 | 冻结的确认 |
relational_final_60 |
960 | 60 条本构定律,包含中性、直接、反向条件及匹配的答案顺序控制 | 冻结的最终基准 |
探索性边界与组合研究
| 配置名称 | 行数 | 目的 | 证据状态 |
|---|---|---|---|
symbolic_monotonicity_pilot |
128 | 符号单调性试验 | 探索性开发 |
symbolic_equivalence_pilot |
256 | 符号等价试验 | 探索性开发 |
abstract_physics_composition |
256 | 抽象代码组合后续研究 | 探索性后续 |
abstract_physics_semantic |
256 | 语义组合后续研究 | 探索性后续 |
数据加载方式
可使用 Hugging Face datasets 库按配置逐次加载。示例代码如下:
python from datasets import load_dataset
heldout = load_dataset("lamm-mit/gemma4-materials-mechanism-prompts", "readability_heldout", split="test") final_laws = load_dataset("lamm-mit/gemma4-materials-mechanism-prompts", "relational_final_60", split="test")
相关资源
- 雅可比透镜检查点与运行产物:lamm-mit/gemma4-jacobian-lenses
- 保留的潜在向量:lamm-mit/gemma4-materials-latent-vectors
- 源代码、冻结协议、结果与补充产物:lamm-mit/Substrates
引用信息
论文正在准备投稿中。待档案标识符可用后,请引用论文及本数据集发布。当前可引用 arXiv 预印本:
@misc{buehler2026readingsteeringrepresentationsmaterialsscience, title={Reading and Steering Representations of Materials-Science Mechanisms in an Open-Weight Language Model}, author={Markus J. Buehler}, year={2026}, eprint={2607.20058}, archivePrefix={arXiv}, primaryClass={cs.AI}, url={https://arxiv.org/abs/2607.20058}, }