UEval
收藏资源简介:
UEval是由普林斯顿大学团队构建的多模态生成评估基准,包含1000个专家精选的跨8类现实任务的问题,要求模型同时生成图像和文本回答。数据集涵盖科学图解、学术图表、生活指南等多样场景,每个问题配有人工验证的评分标准(共10417条),支持细粒度自动评估。其创新性在于采用基于量规的评估框架,通过前沿多模态大模型生成初始标准后经专家修订,解决了开放域多模态生成难以量化评估的难题,为统一模型的复杂推理和跨模态协调能力提供了标准化测试平台。
UEval is a multimodal generation evaluation benchmark developed by a team from Princeton University. It comprises 1,000 expert-selected questions spanning 8 categories of real-world tasks, requiring models to generate both image and text responses. The dataset covers diverse scenarios including scientific illustrations, academic charts, and daily life guides. Each question is paired with manually verified scoring criteria (totaling 10,417 entries), enabling fine-grained automatic evaluation. Its core innovation lies in the adoption of a rubric-based evaluation framework: initial criteria are generated by state-of-the-art multimodal large language models and then revised by domain experts, addressing the long-standing challenge of quantifiable evaluation for open-domain multimodal generation. This benchmark provides a standardized test platform for evaluating unified models' capabilities in complex reasoning and cross-modal coordination.
UEval: 统一多模态生成基准数据集概述
数据集基本信息
- 数据集名称: UEval
- 核心内容: 一个包含1,000个专家精心策划提示的基准,要求模型输出同时包含图像和文本。
- 数据来源: 来自8个不同的现实世界领域。
- 创建机构: 普林斯顿大学
- 相关论文: 《UEval: A Benchmark for Unified Multimodal Generation》
排行榜概览
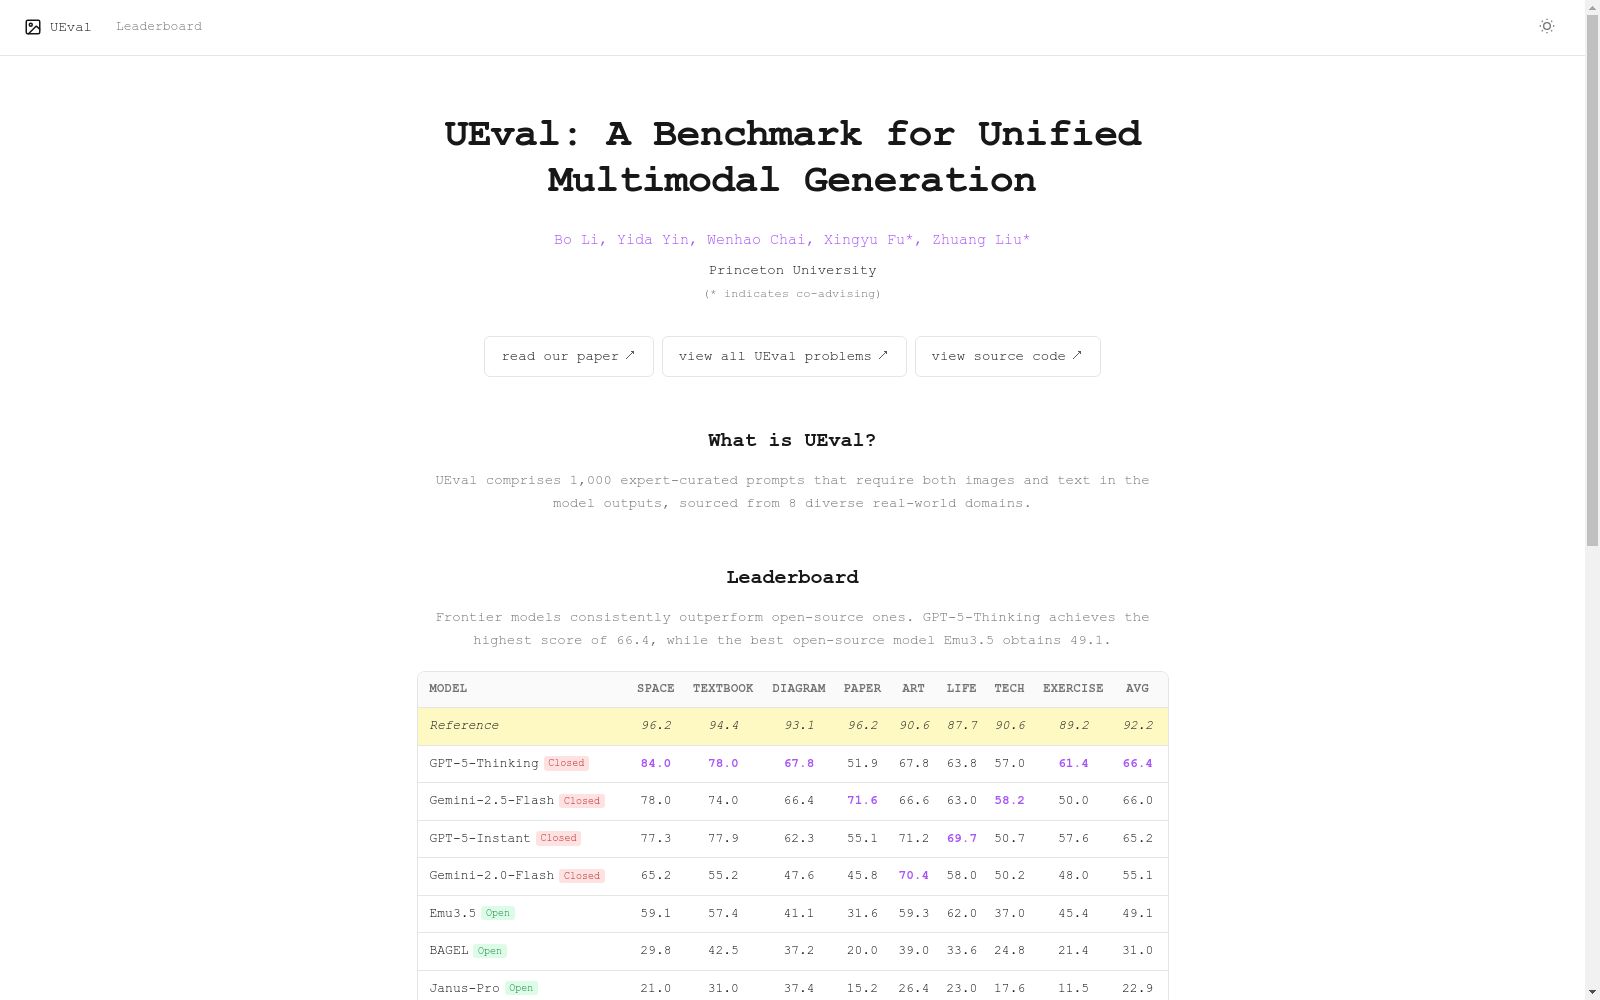
- 最高分模型: GPT-5-Thinking (66.4分)
- 最佳开源模型: Emu3.5 (49.1分)
- 参考分数: 92.2分
- 总体趋势: 前沿模型持续优于开源模型。
模型性能详情(按领域平均分)
| 模型 | Space | Textbook | Diagram | Paper | Art | Life | Tech | Exercise | 平均分 |
|---|---|---|---|---|---|---|---|---|---|
| Reference | 96.2 | 94.4 | 93.1 | 96.2 | 90.6 | 87.7 | 90.6 | 89.2 | 92.2 |
| GPT-5-Thinking (Closed) | 84.0 | 78.0 | 67.8 | 51.9 | 67.8 | 63.8 | 57.0 | 61.4 | 66.4 |
| Gemini-2.5-Flash (Closed) | 78.0 | 74.0 | 66.4 | 71.6 | 66.6 | 63.0 | 58.2 | 50.0 | 66.0 |
| GPT-5-Instant (Closed) | 77.3 | 77.9 | 62.3 | 55.1 | 71.2 | 69.7 | 50.7 | 57.6 | 65.2 |
| Gemini-2.0-Flash (Closed) | 65.2 | 55.2 | 47.6 | 45.8 | 70.4 | 58.0 | 50.2 | 48.0 | 55.1 |
| Emu3.5 (Open) | 59.1 | 57.4 | 41.1 | 31.6 | 59.3 | 62.0 | 37.0 | 45.4 | 49.1 |
| BAGEL (Open) | 29.8 | 42.5 | 37.2 | 20.0 | 39.0 | 33.6 | 24.8 | 21.4 | 31.0 |
| Janus-Pro (Open) | 21.0 | 31.0 | 37.4 | 15.2 | 26.4 | 23.0 | 17.6 | 11.5 | 22.9 |
| Show-o2 (Open) | 25.4 | 33.1 | 33.2 | 17.4 | 25.6 | 15.6 | 17.4 | 13.1 | 22.6 |
| MMaDA (Open) | 10.8 | 20.0 | 14.2 | 13.3 | 15.7 | 15.8 | 12.4 | 12.6 | 14.4 |
评估领域
数据集涵盖以下8个评估领域:Space, Textbook, Diagram, Paper, Art, Life, Tech, Exercise。
快速开始
-
安装依赖:
pip install google-genai datasets pillow -
设置API密钥:
export GEMINI_API_KEY="your-api-key" -
运行评估脚本: bash python ueval_eval.py --model_output_path your_outputs.json --output_path results.json
-
完整文档: 参见GitHub。
引用信息
bibtex @article{li2026ueval, title = {UEval: A Benchmark for Unified Multimodal Generation}, author = {Li, Bo and Yin, Yida and Chai, Wenhao and Fu, Xingyu and Liu, Zhuang}, journal = {arXiv preprint arXiv:2601.22155}, year = {2026} }