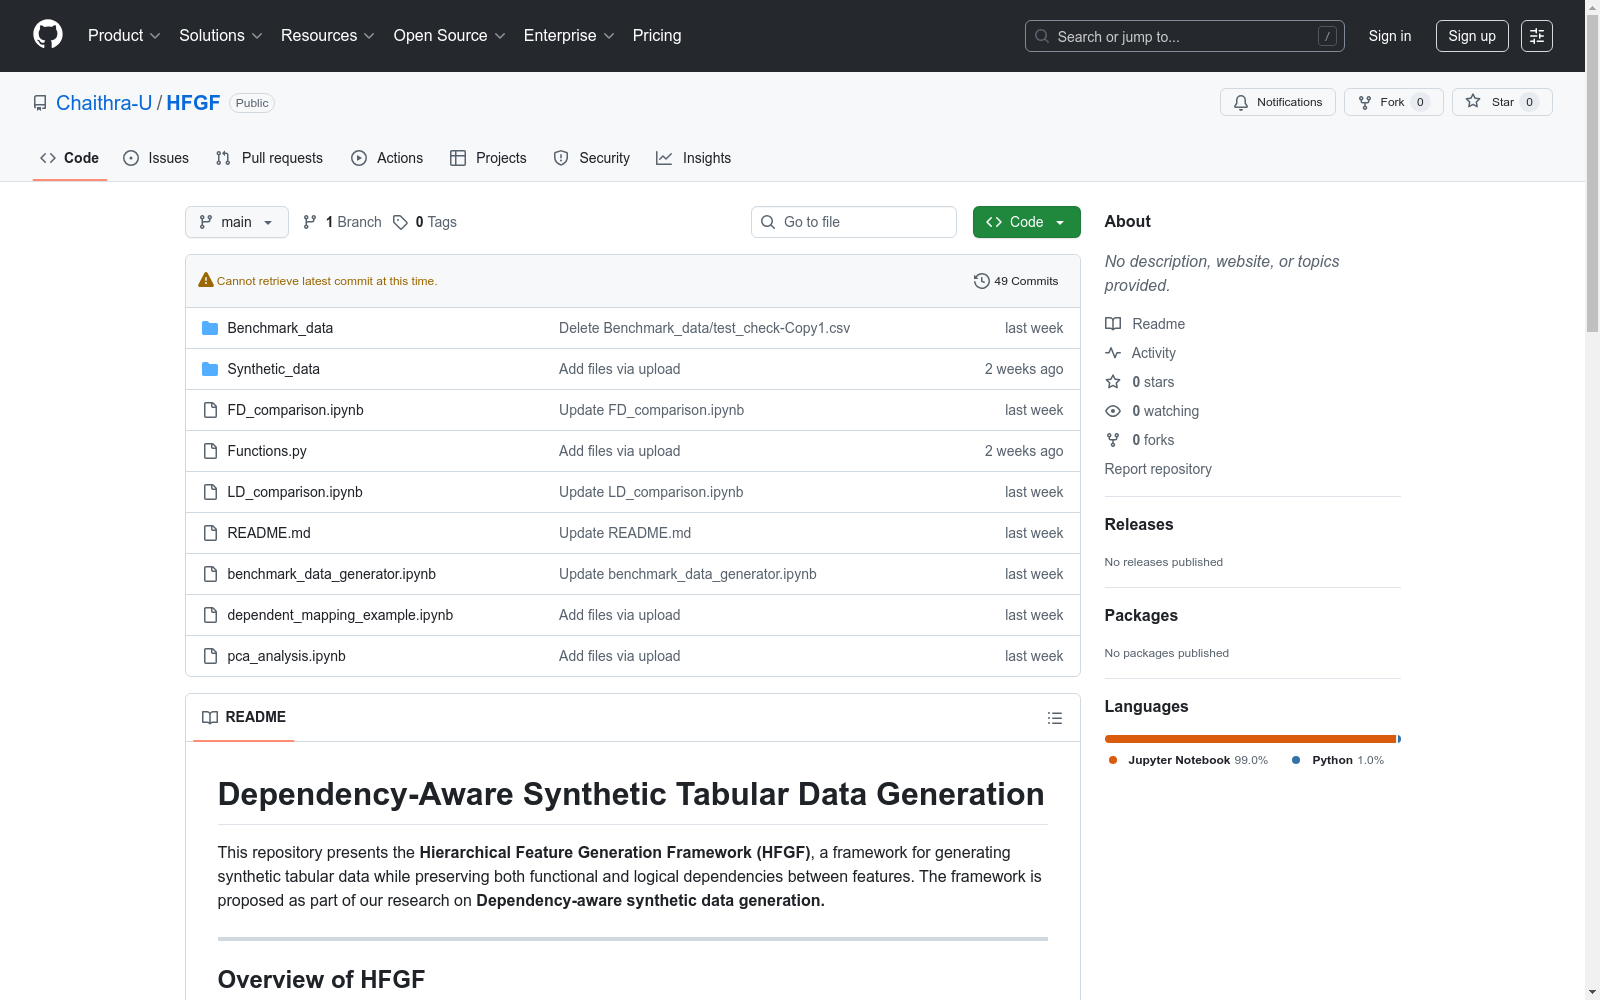
Hierarchical Feature Generation Framework (HFGF) Benchmark Datasets
收藏资源简介:
本文介绍了一个名为HFGF的层次特征生成框架,用于生成保留数据集中属性间依赖关系的合成表格数据。该框架由德国罗斯托克大学计算机科学学院的研究团队提出,旨在解决现有生成模型在隐私敏感领域,如医疗保健,中难以保留属性间关系的问题。HFGF首先使用标准生成模型生成独立特征,然后根据预定义的函数依赖(FD)和逻辑依赖(LD)规则重构依赖特征。该框架通过在四个具有不同大小、特征不平衡和依赖复杂性的基准数据集上的实验,证明了其在六种生成模型中提高了FD和LD的保留程度。HFGF能够显著提高合成表格数据的结构保真度和下游实用性。
This paper presents HFGF, a hierarchical feature generation framework for synthesizing tabular data that preserves dependencies between attributes within the dataset. Developed by a research team from the School of Computer Science at the University of Rostock, Germany, this framework aims to address the critical limitation of existing generative models failing to retain inter-attribute dependencies in privacy-sensitive domains such as healthcare. HFGF first generates independent features using standard generative models, then reconstructs dependent features in line with predefined functional dependency (FD) and logical dependency (LD) rules. Through experiments conducted on four benchmark datasets with varying scales, degrees of feature imbalance, and dependency complexities, the framework validates that it enhances the retention of FDs and LDs across six distinct generative models. HFGF can substantially improve the structural fidelity and downstream task utility of synthesized tabular data.
数据集概述:Dependency-Aware Synthetic Tabular Data Generation
框架介绍
- 框架名称:Hierarchical Feature Generation Framework (HFGF)
- 核心功能:生成合成表格数据,同时保留特征间的功能性和逻辑性依赖关系
框架工作流程
- 特征分类:识别独立特征和依赖特征
- 特征生成:
- 使用标准生成模型生成独立特征
- 根据已知或提取的依赖关系映射依赖特征
- 数据合成:拼接独立和依赖特征形成最终合成数据集
依赖关系识别方法
- 基准数据:依赖关系预定义,独立和依赖特征明确已知
- 真实数据:
- 功能性依赖:使用FDTool提取
- 逻辑性依赖:使用Q-function评估(Q-score=1表示无依赖)
基准数据集
- 数量:4个
- 变量维度:
- 特征数量
- 行数
- 依赖关系的类型和数量
- 文件位置:
- 数据生成代码:Benchmark_data_generator.py
- 生成数据集:Benchmark_data/
应用指南
- 使用FDTool和Q-function提取依赖关系
- 基于依赖信息识别独立特征
- 使用生成模型生成独立特征
- 应用依赖规则映射依赖特征
- 拼接特征形成最终数据集
- 评估依赖关系保留情况
对比生成模型
- CTGAN
- CTABGAN+
- TVAE
- NextConvGeN
- TabuLa
- GReaT