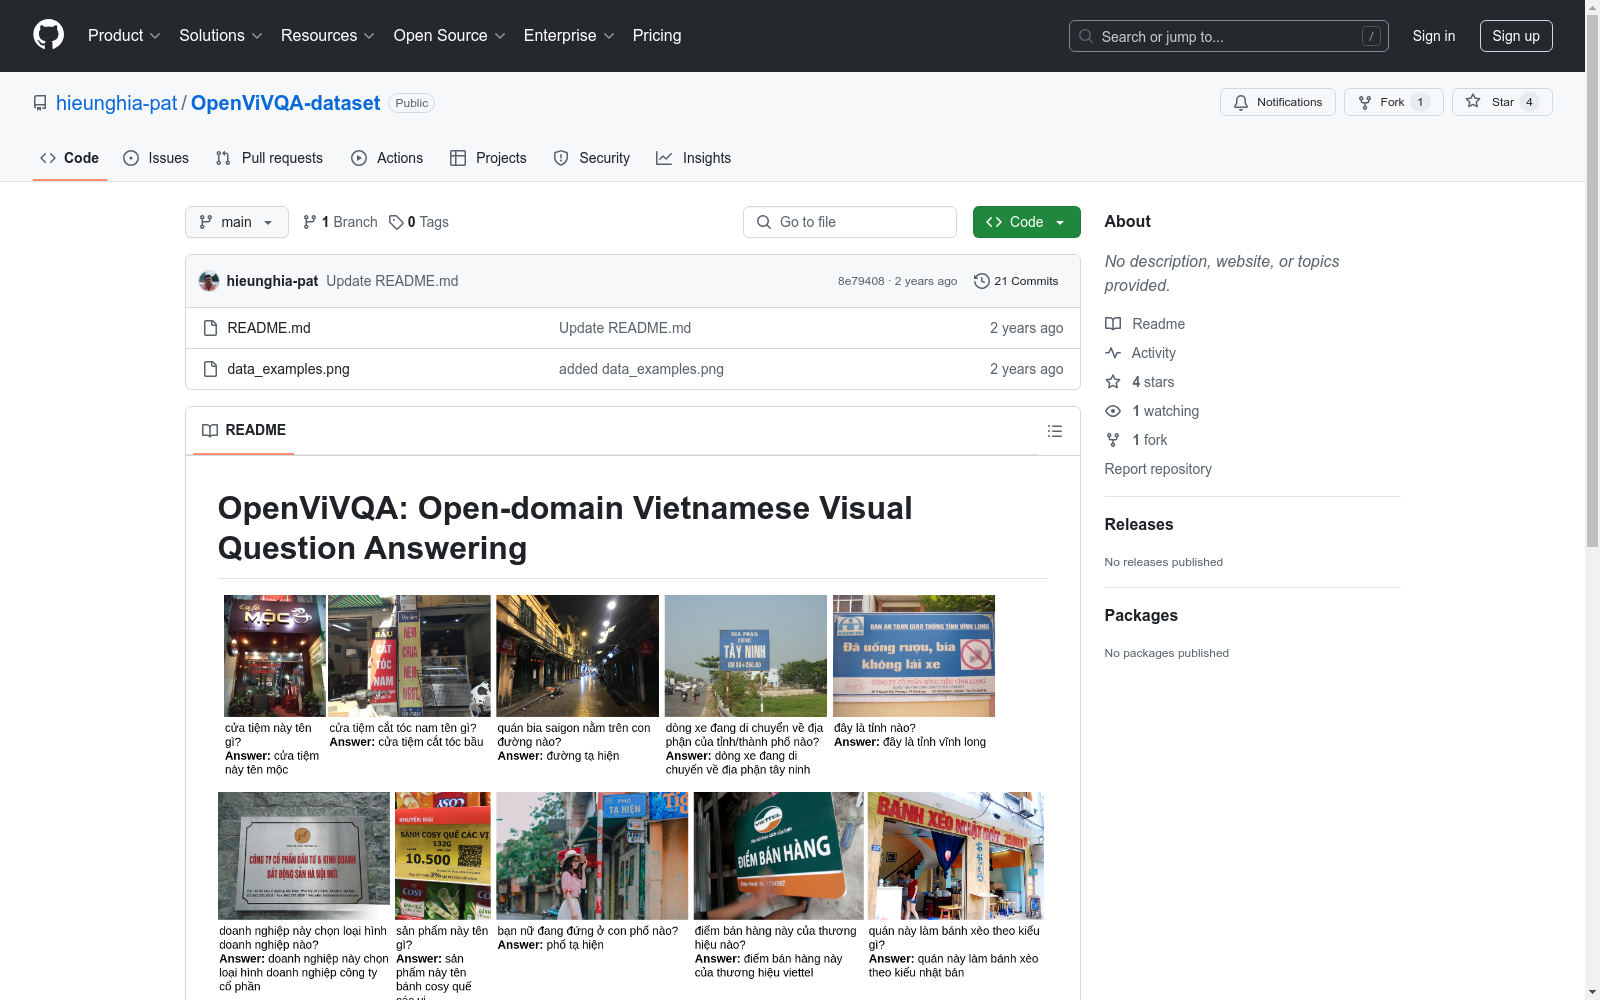
OpenViVQA
收藏资源简介:
OpenViVQA数据集包含超过11,000张图像和37,000多个问题-答案对,引入了基于文本的越南语开放式视觉问答。该数据集对研究社区公开,可在VLSP 2023 - ViVRC共享任务挑战中访问,并通过Codalab评估系统提交结果以评估私有测试集。
The OpenViVQA dataset comprises over 11,000 images and more than 37,000 question-answer pairs, introducing text-based Vietnamese open-ended visual question answering. This dataset is publicly available to the research community and can be accessed during the VLSP 2023 - ViVRC shared task challenge. Results can be submitted via the Codalab evaluation system to assess performance on a private test set.
数据集概述
名称: OpenViVQA
描述: OpenViVQA是一个包含超过11,000张图片和37,000+个问答对的数据集,专注于越南语的文本基础开放域视觉问答。
特点:
- 包含大量图像和问答对。
- 支持越南语的视觉问答任务。
- 适用于开放式答案的视觉问答研究。
用途: 该数据集旨在促进研究社区开发适用于越南语等低资源语言的更通用算法,包括变换器模型。
访问: 数据集可通过VLSP 2023 - ViVRC共享任务挑战公开访问,并可在Codalab评估系统上提交结果以评估私有测试集。
引用: 如使用此数据集,请引用相关论文:
@article{NGUYEN2023101868, title = {OpenViVQA: Task, dataset, and multimodal fusion models for visual question answering in Vietnamese}, journal = {Information Fusion}, volume = {100}, pages = {101868}, year = {2023}, issn = {1566-2535}, doi = {https://doi.org/10.1016/j.inffus.2023.101868}, url = {https://www.sciencedirect.com/science/article/pii/S1566253523001847}, author = {Nghia Hieu Nguyen and Duong T.D. Vo and Kiet {Van Nguyen} and Ngan Luu-Thuy Nguyen}, keywords = {Visual question answering, Vision-language understanding, Low-resource languages, Information fusion, Multimodal representation}, abstract = {In recent years, visual question answering (VQA) has attracted attention from the research community because of its highly potential applications (such as virtual assistance on intelligent cars, assistant devices for blind people, or information retrieval from document images using natural language as queries) and challenge. The VQA task requires methods that have the ability to fuse the information from questions and images to produce appropriate answers. Neural visual question answering models have achieved tremendous growth on large-scale datasets which are mostly for resource-rich languages such as English. However, available datasets narrow the VQA task as the answers selection task or answer classification task. We argue that this form of VQA is far from human ability and eliminates the challenge of the answering aspect in the VQA task by just selecting answers rather than generating them. In this paper, we introduce the OpenViVQA (Open-domain Vietnamese Visual Question Answering) dataset, the first large-scale dataset for VQA with open-ended answers in Vietnamese, consists of 11,000+ images associated with 37,000+ question–answer pairs (QAs). Moreover, we proposed FST, QuMLAG, and MLPAG which fuse information from images and questions, then use these fused features to construct answers as humans iteratively. Our proposed methods achieve results that are competitive with SOTA models such as SAAA, MCAN, LORA, and M4C. The dataset11https://github.com/hieunghia-pat/OpenViVQA-dataset. is available to encourage the research community to develop more generalized algorithms including transformers for low-resource languages such as Vietnamese.} }