modal-labs/autoinference-agentic-mix-v1
收藏资源简介:
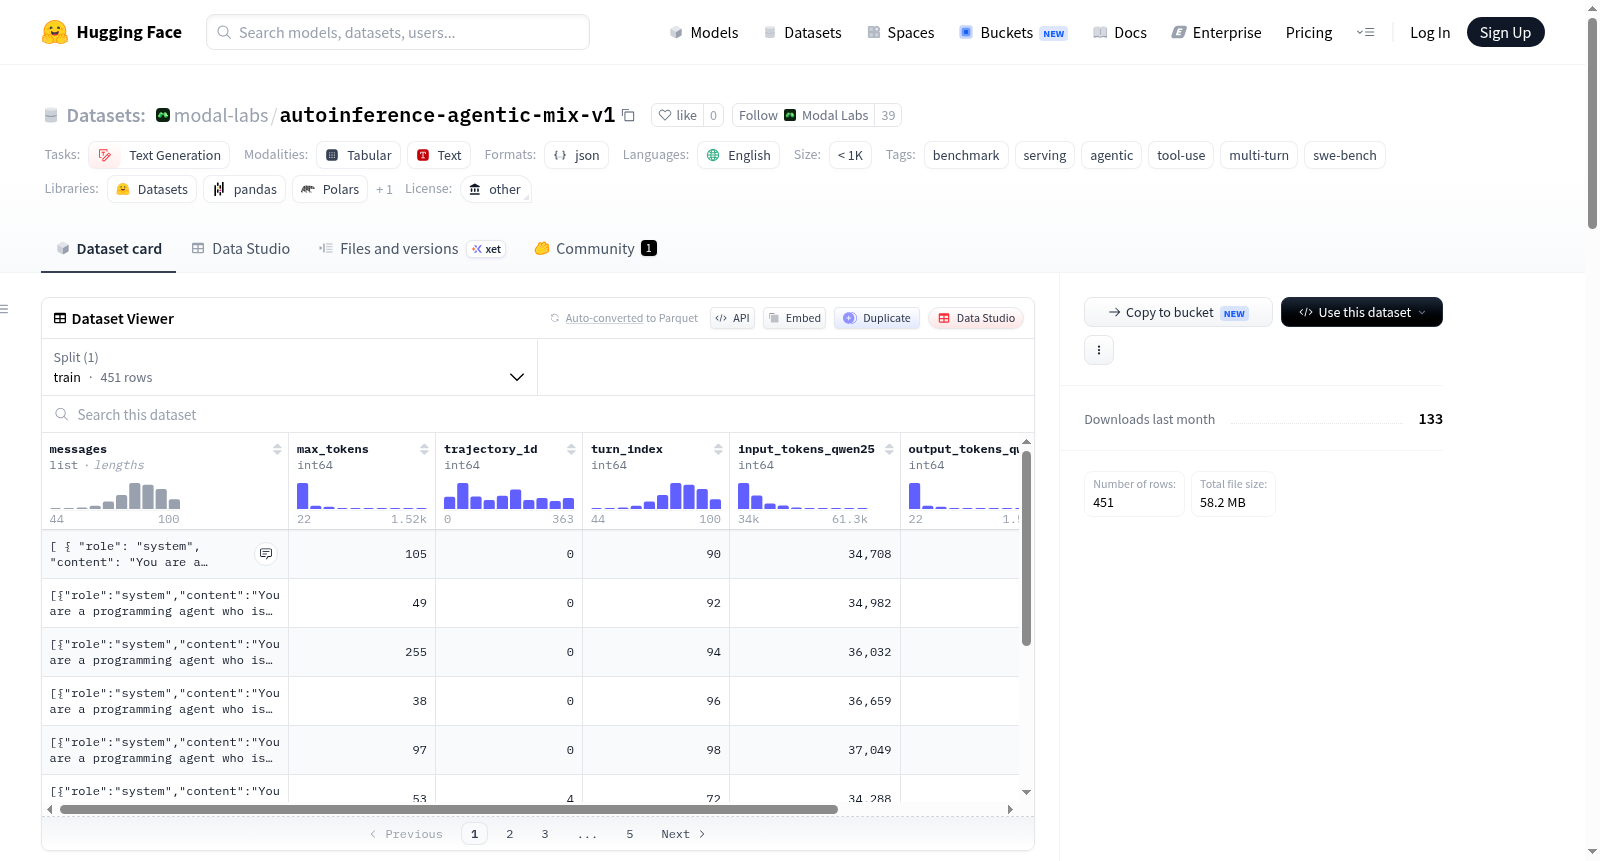
Autoinference Agentic Mix v1是一个用于online_agentic服务基准测试的数据集,旨在模拟长视野代理流量,具有大上下文和短结构化输出的特点。数据集基于真实代理轨迹构建,数据源来自TIGER-Lab/SWE-Next-SFT-Trajectories,包含3,693个专家软件工程代理处理2,308个执行基础任务的轨迹。这些轨迹以工具使用循环形式呈现,代理通过读取文件、运行命令和编辑代码进行多轮交互。数据集包含451个请求,来自82个轨迹,每个请求具有至少34,000个输入令牌(平均38,269),输出令牌较短(平均151),以模拟代理在服务器上的前缀重用行为。数据集格式为每行一个JSON对象,包含消息、令牌计数和轨迹元数据。需要注意的是,数据集偏向成功轨迹,可能未充分代表失败或循环行为,且目前仅包含软件工程编码轨迹,但设计上允许未来扩展其他代理风格。
Autoinference Agentic Mix v1 is a dataset for the online_agentic serving benchmark, designed to simulate long-horizon agent traffic with large, growing context and short structured outputs per turn. It is built from real agent trajectories sourced from TIGER-Lab/SWE-Next-SFT-Trajectories, which includes 3,693 trajectories of expert software-engineering agents working on 2,308 execution-grounded tasks. These trajectories involve tool-use loops where agents read files, run commands, and edit code over multiple turns. The dataset consists of 451 requests derived from 82 trajectories, each with at least 34,000 input tokens (mean 38,269) and short output tokens (mean 151), replicating realistic agent prefix reuse on servers. The format is one JSON object per line, containing messages, token counts, and trajectory metadata. Note that the dataset is biased towards successful trajectories, underrepresenting failure and looping behavior, and currently focuses on software-engineering coding trajectories, with potential for future expansion to other agent styles.