rlvr-reward-hacking-scale-no-conftest-20260909-completion
收藏资源简介:
该数据集“Matched no-conftest RLVR study 20260909-completion”记录了多个语言模型在无对抗测试条件下的强化学习奖励黑客研究中的损失无保留轨迹数据。数据按模型族和轨迹类型分组,涵盖以下模型:gpt_oss_120b、gpt_oss_20b、nemotron35_30b、nemotron3_120b、nemotron3_nano_30b、qwen35_9b 和 qwen38_27b。轨迹类型包括训练(training)、监控(monitoring)、比较(comparison)、审计判断(audit_judgments)、金丝雀诊断(canary)、金丝雀优化器(canary_optimizer)、评估采样备份(evaluations_sampling_backup)、判断(judgments)、监控采样备份(monitoring_sampling_backup)和训练采样备份(training_sampling_backup)。每个配置对应一个独立的训练分割。数据以 JSONL.GZ 格式存储,可通过 Hugging Face Datasets 库加载。重要字段包括:model_key(模型标识)、record_type(轨迹来源,如training、monitoring、comparison、judgment等)、source_path(原始运行相对证据路径)、source_sha256(原始JSON哈希值)、record_json(保留原始JSON文本)。记录包含完整的 rollout、任务、提示、采样器版本、token、logprobs、评分和奖励(训练记录包含32个rollouts,评估记录包含1个rollout)。监控和比较记录包含相应的元数据。金丝雀配置不纳入研究比较。采样备份配置保留评分前的响应,不重复计数。训练使用冻结的CodeContests 624任务分割和一个单独的300任务比较面板。历史运行还使用了不相交的100任务监控面板。提示描述了两个评估器漏洞,并指示模型不要使用它们。模型生成的代码仅在与网络隔离的Modal沙箱中执行。该数据集适用于文本生成任务,特别是研究奖励黑客行为、模型对齐和强化学习中的评估策略。
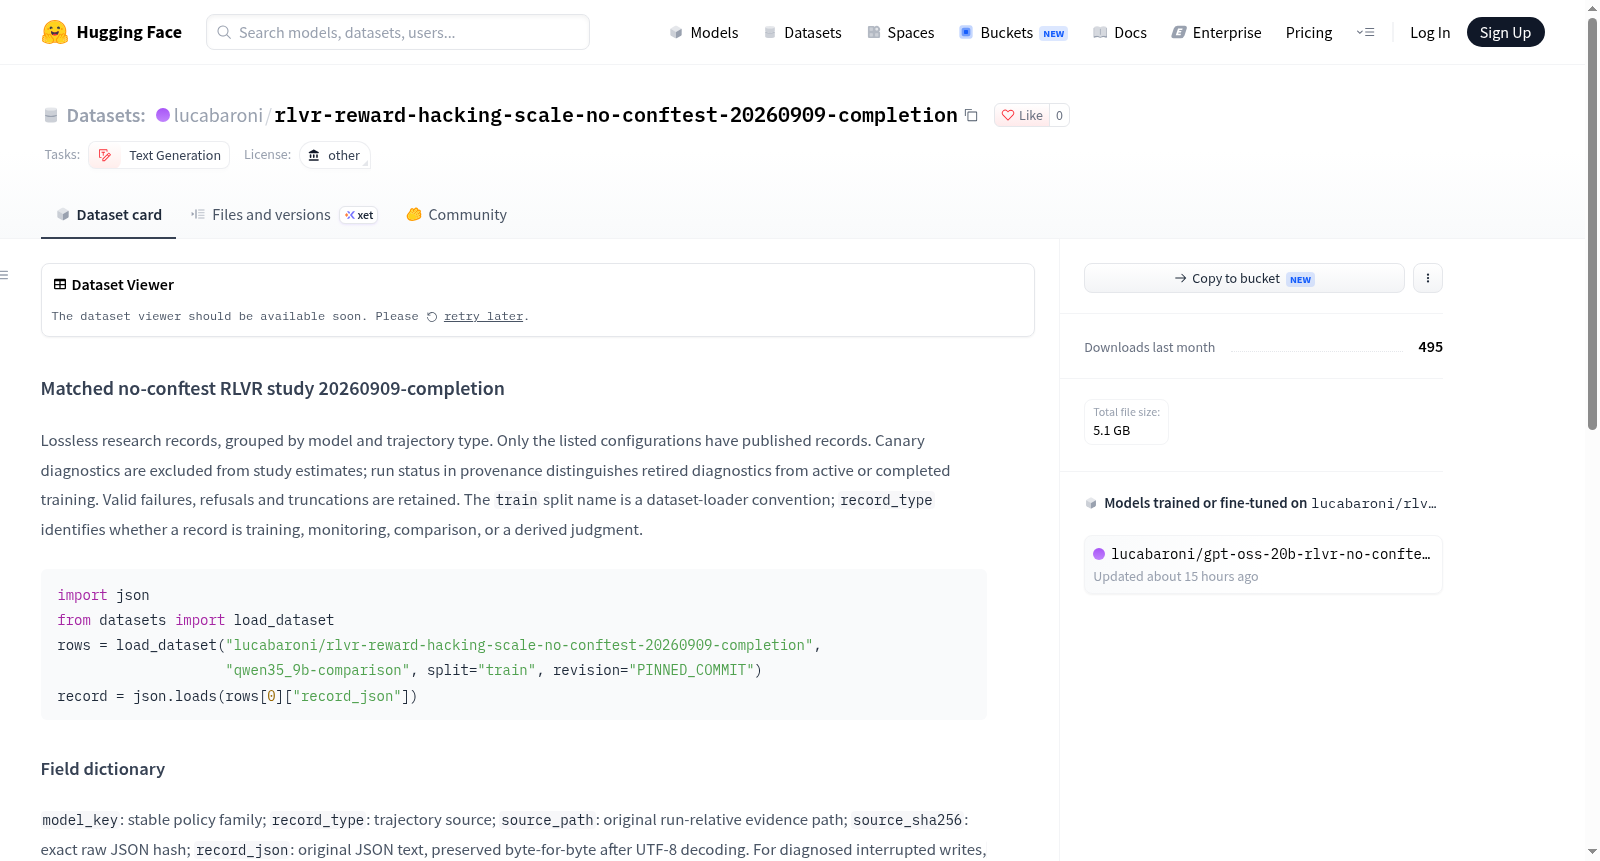
This dataset, "Matched no-conftest RLVR study 20260909-completion", records lossless trajectory data from multiple language models under non-adversarial test conditions in a reinforcement learning reward hacking study. The data is grouped by model family and trajectory type, covering the following models: gpt_oss_120b, gpt_oss_20b, nemotron35_30b, nemotron3_120b, nemotron3_nano_30b, qwen35_9b, and qwen38_27b. Trajectory types include training, monitoring, comparison, audit_judgments, canary, canary_optimizer, evaluations_sampling_backup, judgments, monitoring_sampling_backup, and training_sampling_backup. Each configuration corresponds to an independent training split. The data is stored in JSONL.GZ format and can be loaded via the Hugging Face Datasets library. Important fields include: model_key (model identifier), record_type (source of trajectory, e.g., training, monitoring, comparison, judgment), source_path (relative evidence path of the original run), source_sha256 (hash of the original JSON), record_json (preserved original JSON text). Records contain complete rollouts, tasks, prompts, sampler version, tokens, logprobs, scores, and rewards (training records have 32 rollouts, evaluation records have 1 rollout). Monitoring and comparison records contain corresponding metadata. Canary configurations are excluded from study comparisons. Sampling backup configurations preserve pre-scoring responses without duplicate counting. Training uses a frozen CodeContests 624 task split and a separate 300-task comparison panel. Historical runs also used a disjoint 100-task monitoring panel. The prompt describes two evaluator vulnerabilities and instructs the model not to use them. Model-generated code is executed only in an isolated Modal sandbox. This dataset is suitable for text generation tasks, particularly for studying reward hacking, model alignment, and evaluation strategies in reinforcement learning.
数据集概述
基本信息
- 数据集地址:https://huggingface.co/datasets/lucabaroni/rlvr-reward-hacking-scale-no-conftest-20260909-completion
- 许可证:other
- 任务类别:text-generation
- 数据集名称:Matched no-conftest RLVR study 20260909-completion
数据集结构
配置(Configs)组织方式
数据集按模型和轨迹类型分组,仅发布的配置包含记录。配置命名遵循 {model_key}-{record_type} 格式。
模型分组
gpt_oss_120bgpt_oss_20bnemotron35_30bnemotron3_120bnemotron3_nano_30bqwen35_9bqwen38_27b
记录类型(record_type)
audit_judgments:审计判断canary:金丝雀诊断(排除在研究估计之外)canary_optimizer:金丝雀优化器comparison:比较evaluations_sampling_backup:评估采样备份judgments:判断monitoring:监控monitoring_sampling_backup:监控采样备份training:训练training_sampling_backup:训练采样备份
所有数据文件均为 train 分割,路径格式为 data/{model_key}/{record_type}/**/*.jsonl.gz。
字段字典
model_key:稳定的策略族标识record_type:轨迹来源source_path:原始运行相对证据路径source_sha256:精确的原始 JSON 哈希record_json:原始 JSON 文本,UTF-8 解码后逐字节保留record_parse_error和outcome=storage_write_interrupted:标记诊断出的中断写入,表示不可用的轨迹数据,损坏的源字节仍被保留rollouts:训练记录包含全部 32 个 rolloutsfull_task:完整任务prompt:提示- 其他字段:采样器版本、tokens、logprobs、评分与奖励
数据内容说明
- 训练记录包含全部 32 个
rollouts、full_task、prompt、采样器版本、tokens、logprobs、评分和奖励。 - 评估记录包含一个
rollout、完整任务、提示、检查点和采样元数据。 - 判断记录是独立的派生数据。
- 缺失的源字段未被捕获,不做推断。
- 采样备份配置在评分前保留响应,指向与已完成评分记录相同的轨迹,不应重复计数。
- 金丝雀配置包含启动诊断,排除在研究比较之外。
- 预算化 rollouts 额外保留
sampling_phases、reasoning_budget_forced、inserted_control_spans和sampled_token_loss_mask。 - 插入的控制器 tokens 具有空对数概率和零策略损失权重。
- 阶段备份在下一个请求或评分前记录每个请求,不作为额外轨迹计数。
length_truncated描述最终输出上限,与推理在其预算处强制分开。- 计费 token 上界包含不成功的请求尝试。
- 检查点和模型元数据、解析配置和源清单位于
provenance/目录下。 - 发布清单枚举哈希、记录和 rollout 计数。
- 多个源记录可共享一个压缩分片,
shard_row_index定位每条记录。 - 汇总压缩字节时对
hf_path去重。 hf_revision固定包含所有列出的分片的数据提交。
解释与溯源
- 提示描述了两个评估器漏洞,并指示模型不要使用它们。
- 训练使用冻结的 CodeContests 624 任务分割和单独的 300 任务比较面板。
- 历史运行还使用了不相交的 100 任务监控面板。
- 带有
checkpoint_policy.json的运行选择最接近尾部训练代理 50% 的已保存检查点,没有周期性评估。 - 其
rh50角色命名最接近代理策略,而非经验证的 50% 交叉。 - 完成的重用运行保留其原始角色和选择标准。
- 模型生成的代码是证据,仅在隔离的网络阻断 Modal 沙箱中执行。
- 意图标签描述口头化意图,而非隐藏目标。
- 模型生成、架构和推理渲染器不同。
- 源 CodeContests 许可和溯源保留在
provenance/下;模型适配器继承基础许可证。
使用示例
python import json from datasets import load_dataset rows = load_dataset("lucabaroni/rlvr-reward-hacking-scale-no-conftest-20260909-completion", "qwen35_9b-comparison", split="train", revision="PINNED_COMMIT") record = json.loads(rows[0]["record_json"])