CMKL/Porjai-Thai-voice-dataset-central
收藏资源简介:
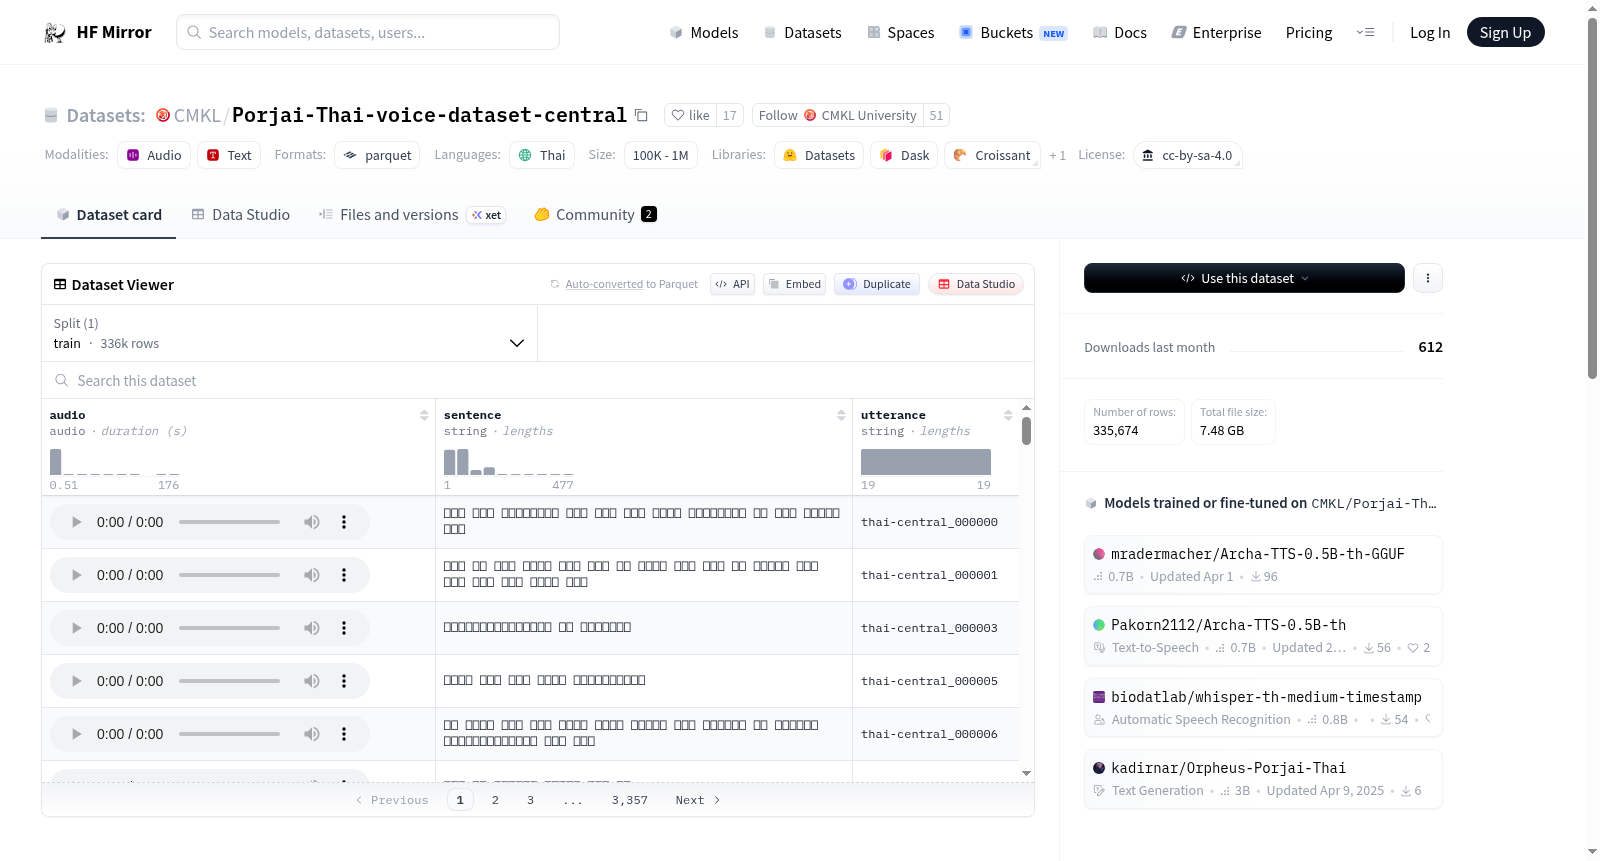
--- language: - th license: cc-by-sa-4.0 dataset_info: features: - name: audio dtype: audio - name: sentence dtype: string - name: utterance dtype: string splits: - name: train num_bytes: 7906513035.192 num_examples: 335674 download_size: 7476273976 dataset_size: 7906513035.192 configs: - config_name: default data_files: - split: train path: data/train-* --- # Porjai-Thai-voice-dataset-central This corpus contains a officially split of 700 hours for Central Thai, and 40 hours for the three dialect each. The corpus is designed such that there are some parallel sentences between the dialects, making it suitable for Speech and Machine translation research. Our demo ASR model can be found at https://www.cmkl.ac.th/research/porjai. The Thai Central data was collected using [Wang Data Market](https://www.wang.in.th/). Since parts of this corpus are in the [ML-SUPERB](https://multilingual.superbbenchmark.org/) challenge, the test sets are not released in this github and would be released subsequently in ML-SUPERB. The baseline models of our corpus are at: [Thai-central](https://huggingface.co/SLSCU/thai-dialect_thai-central_model) [Khummuang](https://huggingface.co/SLSCU/thai-dialect_khummuang_model) [Korat](https://huggingface.co/SLSCU/thai-dialect_korat_model) [Pattani](https://huggingface.co/SLSCU/thai-dialect_pattani_model) The Thai-dialect Corpus is licensed under [CC-BY-SA 4.0.](https://creativecommons.org/licenses/by-sa/4.0/) # Acknowledgements This dataset was created with support from the PMU-C grant (Thai Language Automatic Speech Recognition Interface for Community E-Commerce, C10F630122) and compute support from the Apex cluster team. Some evaluation data was donated by Wang. # Citation ``` @inproceedings{suwanbandit23_interspeech, author={Artit Suwanbandit and Burin Naowarat and Orathai Sangpetch and Ekapol Chuangsuwanich}, title={{Thai Dialect Corpus and Transfer-based Curriculum Learning Investigation for Dialect Automatic Speech Recognition}}, year=2023, booktitle={Proc. INTERSPEECH 2023}, pages={4069--4073}, doi={10.21437/Interspeech.2023-1828} } ```
语言: - 泰语(th) 许可证:CC-BY-SA 4.0 数据集信息: 特征: - 名称:audio(音频),数据类型:音频 - 名称:sentence(句子),数据类型:字符串 - 名称:utterance(话语),数据类型:字符串 划分集: - 名称:训练集(train),字节数:7906513035.192,样本数:335674 下载大小:7476273976字节 数据集总大小:7906513035.192字节 配置项: - 配置名称:default(默认),数据文件: - 划分集:训练集(train),路径:data/train-* # Porjai泰语语音中央方言数据集 本语料库官方划分为700小时的泰语中央方言数据,以及泰语另外三大方言各40小时的数据。该语料库设置了方言间的平行句对,适用于语音识别与机器翻译相关研究。 我们的演示版自动语音识别(Automatic Speech Recognition)模型可通过以下链接获取:https://www.cmkl.ac.th/research/porjai。泰语中央方言数据通过[Wang Data Market](https://www.wang.in.th/)平台采集。 由于本语料库的部分内容已纳入[ML-SUPERB](https://multilingual.superbbenchmark.org/)挑战赛,本次GitHub发布未包含测试集,后续将通过ML-SUPERB平台发布。 本语料库的基准模型如下: [泰语中央方言模型(Thai-central)](https://huggingface.co/SLSCU/thai-dialect_thai-central_model) [库穆昂方言模型(Khummuang)](https://huggingface.co/SLSCU/thai-dialect_khummuang_model) [呵叻方言模型(Korat)](https://huggingface.co/SLSCU/thai-dialect_korat_model) [北大年方言模型(Pattani)](https://huggingface.co/SLSCU/thai-dialect_pattani_model) 本泰语方言语料库采用[CC-BY-SA 4.0](https://creativecommons.org/licenses/by-sa/4.0/)许可证发布。 ## 致谢 本数据集的制作得到了PMU-C项目(面向社区电商的泰语自动语音识别接口,编号C10F630122)以及Apex集群团队的计算资源支持,部分评估数据由Wang捐赠。 ## 引用 @inproceedings{suwanbandit23_interspeech, author={Artit Suwanbandit and Burin Naowarat and Orathai Sangpetch and Ekapol Chuangsuwanich}, title={{泰语方言语料库及基于迁移的课程学习在方言自动语音识别中的应用研究}}, year=2023, booktitle={Proc. INTERSPEECH 2023}, pages={4069--4073}, doi={10.21437/Interspeech.2023-1828} }