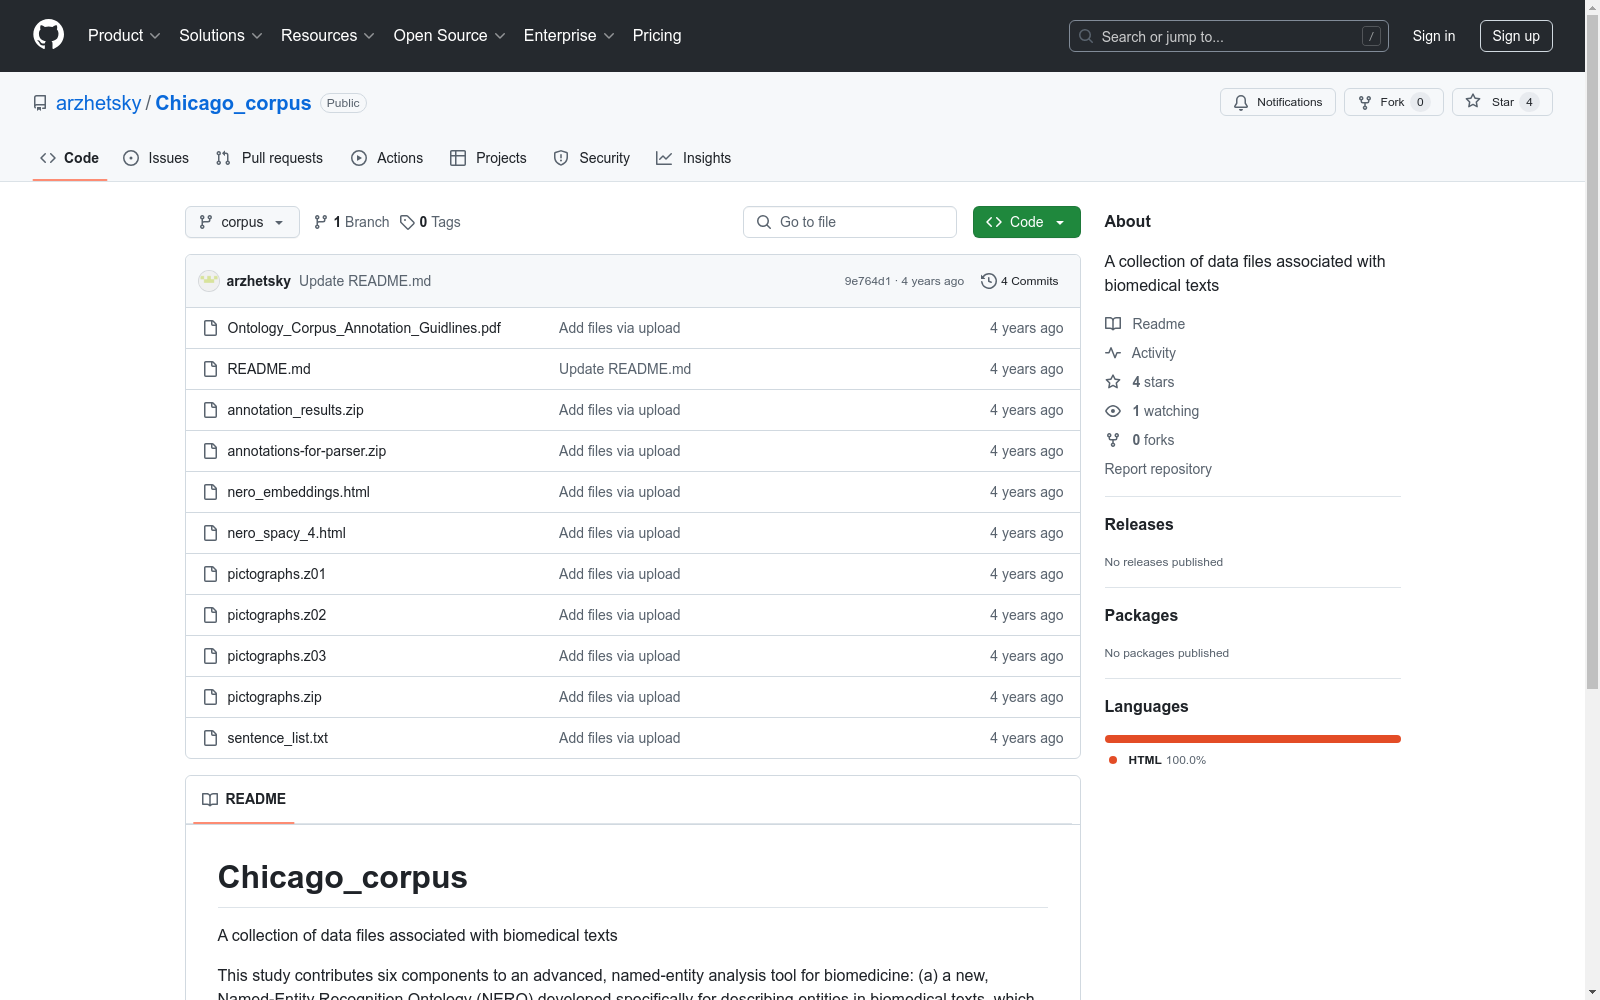
Chicago_corpus
收藏资源简介:
该研究为生物医学的高级命名实体分析工具贡献了六个组件:(a) 一个专为描述生物医学文本中的实体而开发的新命名实体识别本体论(NERO),考虑了不同层次的歧义,连接了分子生物学、遗传学、生物化学和医学的科学子语言;(b) 详细的人类专家标注数百个命名实体类别的指南;(c) 所有命名实体的象形图,以简化管理员的标注负担;(d) 一个原始的、注释过的语料库,包含35,865个句子,封装了190,679个命名实体和43,438个连接两个或多个实体的事件;(e) 经过验证的、现成的命名实体识别自动提取;(f) 嵌入模型,展示了该语料库中嵌入的生物医学关联的潜力。
This research contributes six components to advanced named entity analysis tools in biomedicine: (a) a novel Named Entity Recognition Ontology (NERO) specifically developed for describing entities in biomedical texts, which considers various levels of ambiguity and connects scientific sublanguages of molecular biology, genetics, biochemistry, and medicine; (b) detailed guidelines for human expert annotation of hundreds of named entity categories; (c) pictograms for all named entities to simplify the annotation burden on administrators; (d) an original, annotated corpus containing 35,865 sentences, encapsulating 190,679 named entities and 43,438 events linking two or more entities; (e) validated, ready-to-use automatic extraction for named entity recognition; (f) embedding models demonstrating the potential of biomedical associations embedded in this corpus.
数据集概述
名称: Chicago_corpus
描述: 该数据集是一个与生物医学文本相关的数据文件集合,主要用于支持高级的命名实体分析工具。
数据集组件
- 命名实体识别本体(NERO): 专为描述生物医学文本中的实体而开发,考虑了不同级别的模糊性,涵盖分子生物学、遗传学、生物化学和医学等多个科学子语言。
- 标注指南: 为专家提供详细的标注指南,用于标注数百种命名实体类别。
- 图示: 所有命名实体均配有图示,以简化标注者的标注负担。
- 标注语料库: 包含35,865个句子,涵盖190,679个命名实体和43,438个连接两个或多个实体的事件。
- 自动化提取工具: 验证过的命名实体识别自动化提取工具。
- 嵌入模型: 展示该语料库中嵌入的生物医学关联的潜力。
附加信息
- 图示存储: 图示存储在一个多部分的ZIP档案中,需要下载以下文件进行解压:
pictographs.zippictographs.z01pictographs.z02pictographs.z03