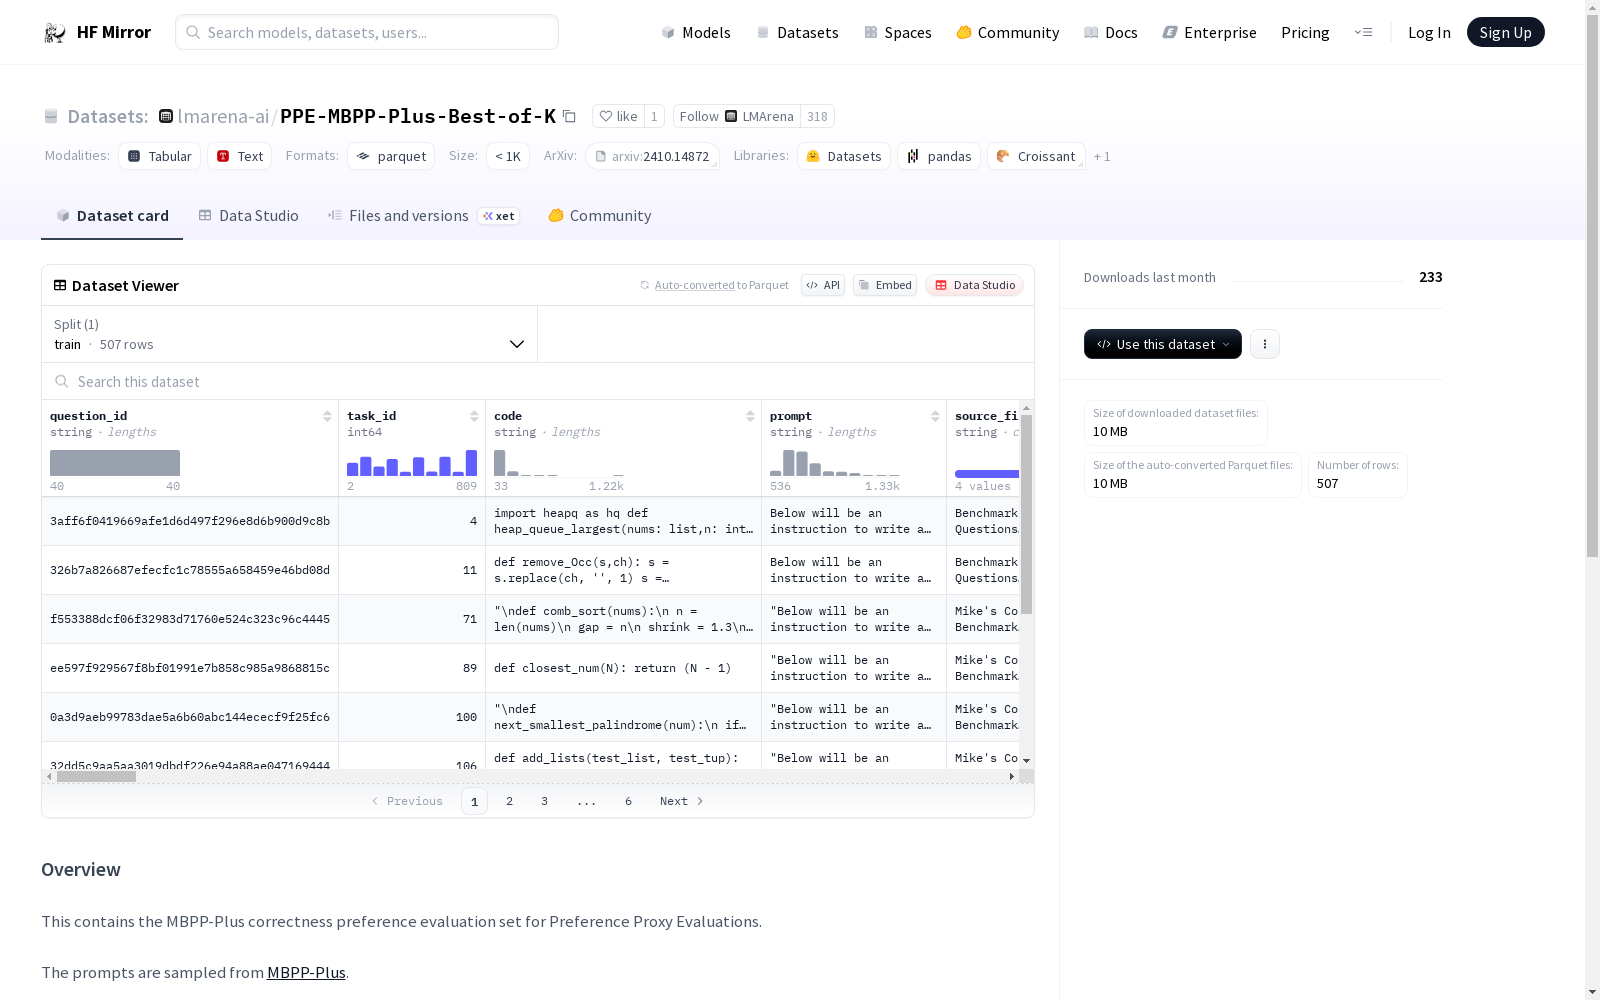
lmarena-ai/PPE-MBPP-Plus-Best-of-K
收藏资源简介:
--- dataset_info: features: - name: question_id dtype: string - name: task_id dtype: int64 - name: code dtype: string - name: prompt dtype: string - name: source_file dtype: string - name: test_imports sequence: string - name: test_list sequence: string - name: test dtype: string - name: model_name dtype: string - name: scores sequence: bool - name: mean_score dtype: float64 - name: response_1 dtype: string - name: response_2 dtype: string - name: response_3 dtype: string - name: response_4 dtype: string - name: response_5 dtype: string - name: response_6 dtype: string - name: response_7 dtype: string - name: response_8 dtype: string - name: response_9 dtype: string - name: response_10 dtype: string - name: response_11 dtype: string - name: response_12 dtype: string - name: response_13 dtype: string - name: response_14 dtype: string - name: response_15 dtype: string - name: response_16 dtype: string - name: response_17 dtype: string - name: response_18 dtype: string - name: response_19 dtype: string - name: response_20 dtype: string - name: response_21 dtype: string - name: response_22 dtype: string - name: response_23 dtype: string - name: response_24 dtype: string - name: response_25 dtype: string - name: response_26 dtype: string - name: response_27 dtype: string - name: response_28 dtype: string - name: response_29 dtype: string - name: response_30 dtype: string - name: response_31 dtype: string - name: response_32 dtype: string - name: conflict_pairs sequence: sequence: int64 - name: sampled_conflict_pairs sequence: sequence: int64 splits: - name: train num_bytes: 29926103 num_examples: 507 download_size: 10040281 dataset_size: 29926103 configs: - config_name: default data_files: - split: train path: data/train-* --- # Overview This contains the MBPP-Plus correctness preference evaluation set for Preference Proxy Evaluations. The prompts are sampled from [MBPP-Plus](https://huggingface.co/datasets/evalplus/mbppplus). This dataset is meant for benchmarking and evaluation, not for training. [Paper](https://arxiv.org/abs/2410.14872) [Code](https://github.com/lmarena/PPE) # License User prompts are licensed under Apache-2.0, and model outputs are governed by the terms of use set by the respective model providers. # Citation ``` @misc{frick2024evaluaterewardmodelsrlhf, title={How to Evaluate Reward Models for RLHF}, author={Evan Frick and Tianle Li and Connor Chen and Wei-Lin Chiang and Anastasios N. Angelopoulos and Jiantao Jiao and Banghua Zhu and Joseph E. Gonzalez and Ion Stoica}, year={2024}, eprint={2410.14872}, archivePrefix={arXiv}, primaryClass={cs.LG}, url={https://arxiv.org/abs/2410.14872}, } ```
dataset_info: 数据集信息: features: - 名称: question_id 数据类型: 字符串 - 名称: task_id 数据类型: 64位整型 - 名称: code 数据类型: 字符串 - 名称: prompt 数据类型: 提示词 - 名称: source_file 数据类型: 源文件 - 名称: 测试导入项 数据类型: 字符串序列 - 名称: 测试用例列表 数据类型: 字符串序列 - 名称: 测试代码 数据类型: 字符串 - 名称: model_name 数据类型: 模型名称 - 名称: scores 数据类型: 布尔值序列 - 名称: mean_score 数据类型: 64位浮点型 - 名称: response_1 数据类型: 字符串 - 名称: response_2 数据类型: 字符串 - 名称: response_3 数据类型: 字符串 - 名称: response_4 数据类型: 字符串 - 名称: response_5 数据类型: 字符串 - 名称: response_6 数据类型: 字符串 - 名称: response_7 数据类型: 字符串 - 名称: response_8 数据类型: 字符串 - 名称: response_9 数据类型: 字符串 - 名称: response_10 数据类型: 字符串 - 名称: response_11 数据类型: 字符串 - 名称: response_12 数据类型: 字符串 - 名称: response_13 数据类型: 字符串 - 名称: response_14 数据类型: 字符串 - 名称: response_15 数据类型: 字符串 - 名称: response_16 数据类型: 字符串 - 名称: response_17 数据类型: 字符串 - 名称: response_18 数据类型: 字符串 - 名称: response_19 数据类型: 字符串 - 名称: response_20 数据类型: 字符串 - 名称: response_21 数据类型: 字符串 - 名称: response_22 数据类型: 字符串 - 名称: response_23 数据类型: 字符串 - 名称: response_24 数据类型: 字符串 - 名称: response_25 数据类型: 字符串 - 名称: response_26 数据类型: 字符串 - 名称: response_27 数据类型: 字符串 - 名称: response_28 数据类型: 字符串 - 名称: response_29 数据类型: 字符串 - 名称: response_30 数据类型: 字符串 - 名称: response_31 数据类型: 字符串 - 名称: response_32 数据类型: 字符串 - 名称: conflict_pairs 数据类型: 整型序列的序列 - 名称: sampled_conflict_pairs 数据类型: 整型序列的序列 splits: - 划分名称: 训练集 字节数: 29926103 样本数量: 507 下载大小: 10040281 数据集总大小: 29926103 configs: - 配置名称: default 数据文件: - 划分: 训练集 路径: data/train-* # 概述 本数据集为用于偏好代理评估(Preference Proxy Evaluations)的MBPP-Plus正确性偏好评估集。 其提示词采样自[MBPP-Plus](https://huggingface.co/datasets/evalplus/mbppplus)。 本数据集仅用于基准测试与模型评估,不可用于模型训练。 [论文](https://arxiv.org/abs/2410.14872) [代码](https://github.com/lmarena/PPE) # 许可协议 用户提示词遵循Apache-2.0许可协议,模型输出需遵守对应模型提供商的使用条款。 # 引用 @misc{frick2024evaluaterewardmodelsrlhf, title={面向人类反馈强化学习(RLHF)的奖励模型评估方法}, author={Evan Frick and Tianle Li and Connor Chen and Wei-Lin Chiang and Anastasios N. Angelopoulos and Jiantao Jiao and Banghua Zhu and Joseph E. Gonzalez and Ion Stoica}, year={2024}, eprint={2410.14872}, archivePrefix={arXiv}, primaryClass={cs.LG}, url={https://arxiv.org/abs/2410.14872}, }