tatsu-lab/alpaca
收藏资源简介:
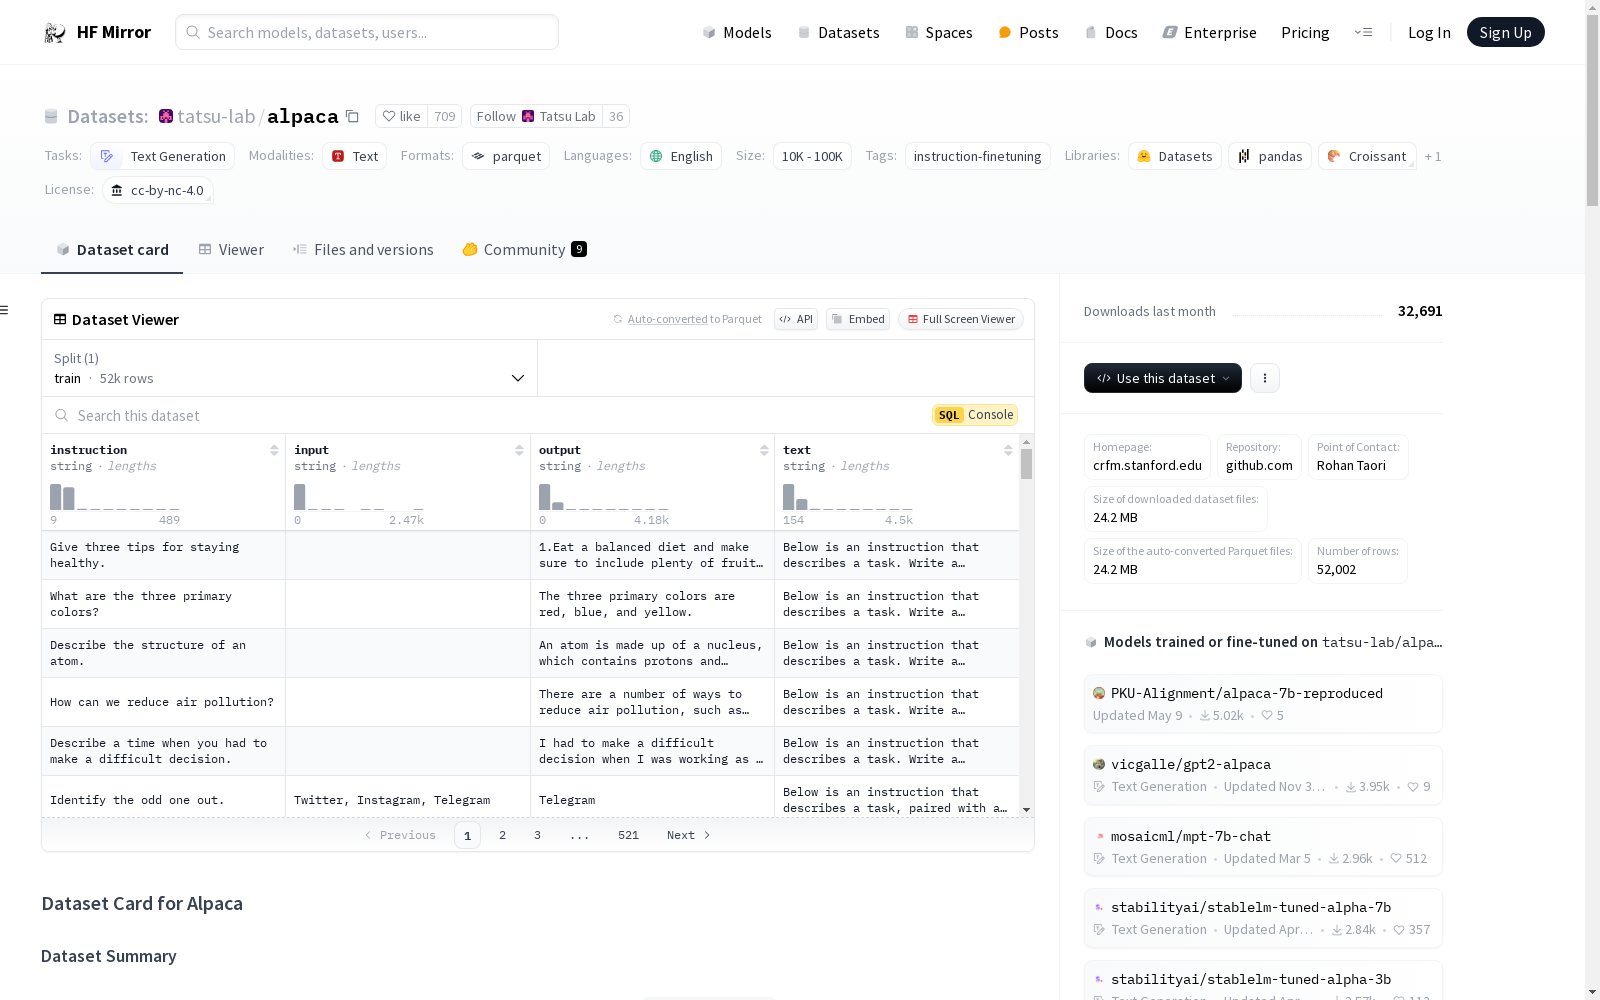
Alpaca数据集是一个包含52,000条指令和演示的数据集,这些数据由OpenAI的`text-davinci-003`引擎生成。该数据集用于指令微调语言模型,使其更好地遵循指令。数据集的生成基于Self-Instruct框架,并进行了多项修改,包括使用`text-davinci-003`引擎、编写新的提示、采用更激进的批量解码、简化数据生成管道以及为每个指令生成单个实例。这些修改显著降低了数据生成的成本,并提高了数据的多样性。数据集的结构包括指令、输入、输出和格式化文本。数据集的使用考虑了社会影响和潜在风险,并采取了相应的风险缓解措施。
The Alpaca dataset is a collection of 52,000 instructions and demonstrations generated by OpenAI's `text-davinci-003` engine. It is designed for instruction tuning of language models to enable them to better follow given instructions. Developed based on the Self-Instruct framework, the dataset incorporates several modifications, including adopting the `text-davinci-003` engine, crafting new prompts, employing more aggressive batch decoding, simplifying the data generation pipeline, and generating a single instance per instruction. These modifications have significantly reduced the cost of data generation and improved the diversity of the dataset. The structure of the dataset includes instructions, inputs, outputs, and formatted text. During the utilization of this dataset, social impacts and potential risks have been taken into consideration, and corresponding risk mitigation measures have been implemented.
数据集概述:Alpaca
数据集描述
- 数据集名称: Alpaca
- 数据集概要: Alpaca是一个包含52,000条指令和演示的数据集,由OpenAI的
text-davinci-003引擎生成。该数据集主要用于语言模型的指令微调,以提高模型遵循指令的能力。 - 语言: 英语(BCP-47 en)
- 许可: 创意共享非商业性许可(CC BY-NC 4.0)
数据集结构
数据实例
- 示例: json { "instruction": "Create a classification task by clustering the given list of items.", "input": "Apples, oranges, bananas, strawberries, pineapples", "output": "Class 1: Apples, Oranges Class 2: Bananas, Strawberries Class 3: Pineapples", "text": "Below is an instruction that describes a task, paired with an input that provides further context. Write a response that appropriately completes the request.
Instruction:
Create a classification task by clustering the given list of items.
Input:
Apples, oranges, bananas, strawberries, pineapples
Response:
Class 1: Apples, Oranges Class 2: Bananas, Strawberries Class 3: Pineapples", }
数据字段
- instruction: 描述模型应执行的任务,每个指令都是唯一的。
- input: 任务的上下文或输入,约40%的示例包含此字段。
- output:
text-davinci-003生成的指令答案。 - text: 使用作者提供的模板格式化的
instruction、input和output。
数据分割
- 训练集: 52002条记录
数据集创建
数据生成
- 生成引擎: 使用
text-davinci-003引擎生成指令数据。 - 生成策略: 采用更积极的批量解码,一次生成20条指令,显著降低数据生成成本。
- 数据简化: 简化数据生成流程,不再区分分类和非分类指令,每个指令仅生成一个实例。
使用考虑
社会影响
- 风险与利益: 发布此数据集可能带来风险,如增加有害内容传播的可能性,但同时也为学术界提供了进行指令遵循语言模型研究的工具。
- 风险缓解措施: 实施内容过滤和输出水印技术,以及严格的非商业使用条款。
数据局限性
- 数据质量: 由于数据由语言模型生成,可能包含错误或偏见,建议用户谨慎使用并探索改进方法。