nhagar/CC-MAIN-2019-39_urls
收藏资源简介:
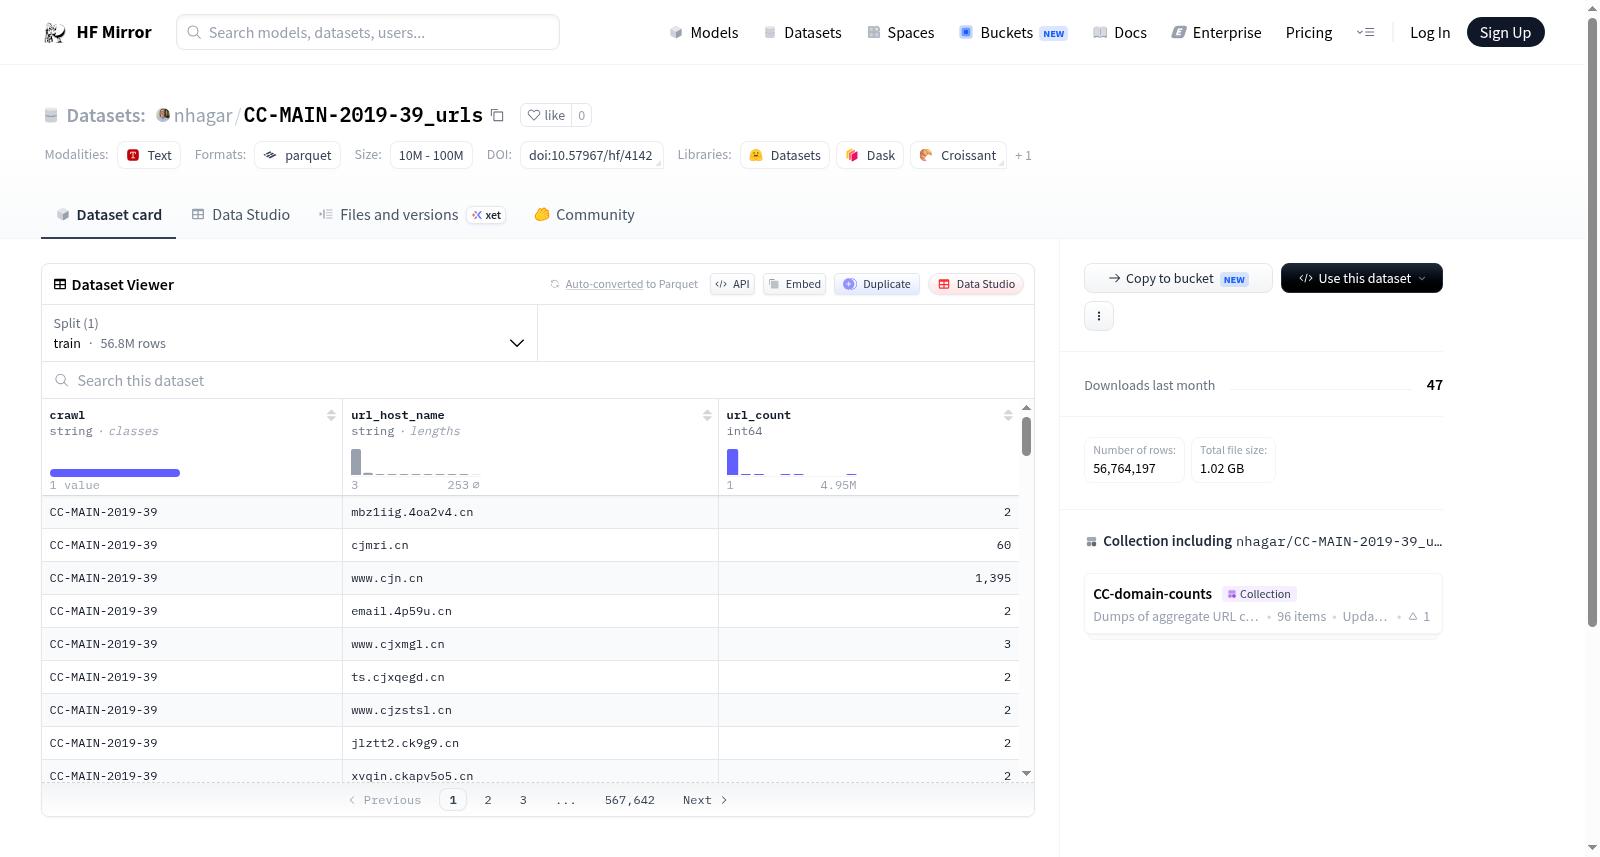
--- dataset_info: features: - name: crawl dtype: string - name: url_host_name dtype: string - name: url_count dtype: int64 splits: - name: train num_bytes: 2844632861 num_examples: 56764197 download_size: 1015654379 dataset_size: 2844632861 configs: - config_name: default data_files: - split: train path: data/train-* --- This dataset contains domain names and counts of (non-deduplicated) URLs for every record in the CC-MAIN-2019-39 snapshot of the Common Crawl. It was collected from the [AWS S3 version](https://aws.amazon.com/marketplace/pp/prodview-zxtb4t54iqjmy?sr=0-1&ref_=beagle&applicationId=AWSMPContessa) of Common Crawl via Amazon Athena. This dataset is derived from Common Crawl data and is subject to Common Crawl's Terms of Use: [https://commoncrawl.org/terms-of-use](https://commoncrawl.org/terms-of-use).
The dataset includes web crawling information, with features such as page content (crawl), URL host names (url_host_name), and the count of URL occurrences (url_count). The dataset contains only the training set, which has a total of 56,764,197 examples and is 2.84GB in size. The download size of the dataset is 1.01GB.