Ro551/WikiCorrupted_spanish_to_GEC-GED_med
收藏资源简介:
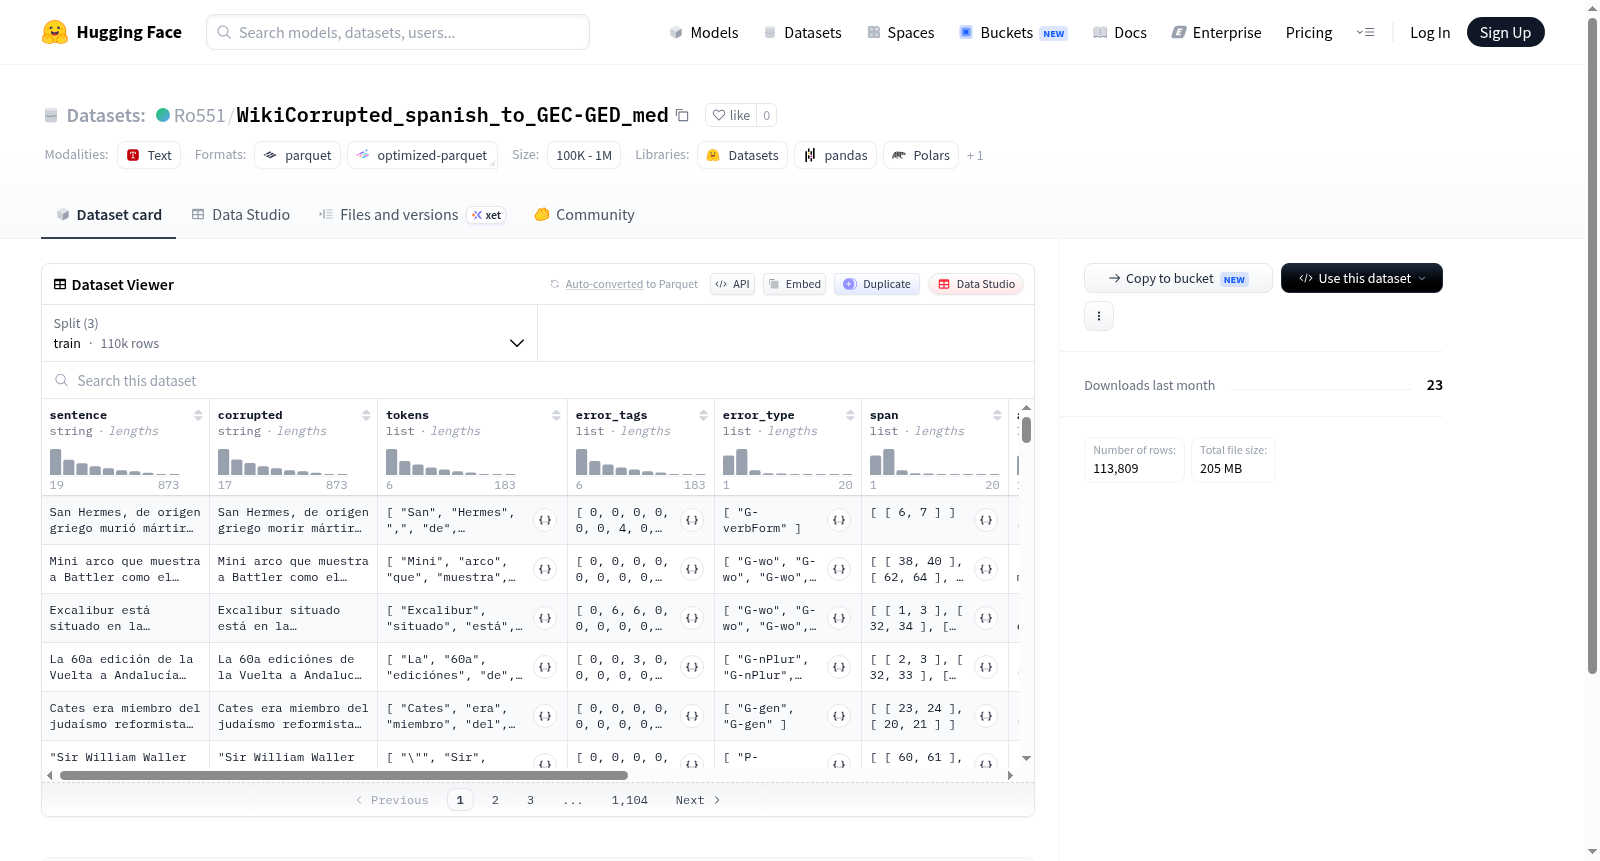
该数据集是一个用于语法或拼写错误检测和纠正的数据集,包含句子及其错误版本(corrupted),以及详细的标记(tokens)、错误标签(error_tags)、错误类型(error_type)、跨度(span)、注释(annotation)等特征。错误标签涵盖多种类型,如正确(Correct)、语法生成错误(G-gen)、单复数错误(G-nSing、G-nPlur)、动词形式错误(G-verbForm)、冠词使用错误(G-uArt)、其他语法错误(G-wo)、标点缺失(P-missing)、标题错误(S-title)、重音缺失(S-noAccent)和拼写错误(S-mistake)。数据集分为训练集(110,330个示例)、验证集(1,727个示例)和测试集(1,752个示例),适用于自然语言处理任务,如自动错误检测和文本纠正。
This dataset is designed for grammar or spelling error detection and correction, containing sentences along with their corrupted versions, as well as detailed features such as tokens, error tags, error types, spans, annotations, and more. The error tags cover various types including Correct, G-gen (grammar generation errors), G-nSing/G-nPlur (singular/plural errors), G-verbForm (verb form errors), G-uArt (article usage errors), G-wo (other grammar errors), P-missing (punctuation missing), S-title (title errors), S-noAccent (accent missing), and S-mistake (spelling errors). The dataset is split into training (110,330 examples), validation (1,727 examples), and test (1,752 examples) sets, making it suitable for natural language processing tasks like automatic error detection and text correction.