Nhoodie/hgt-bootstrap-v2-synthetic
收藏资源简介:
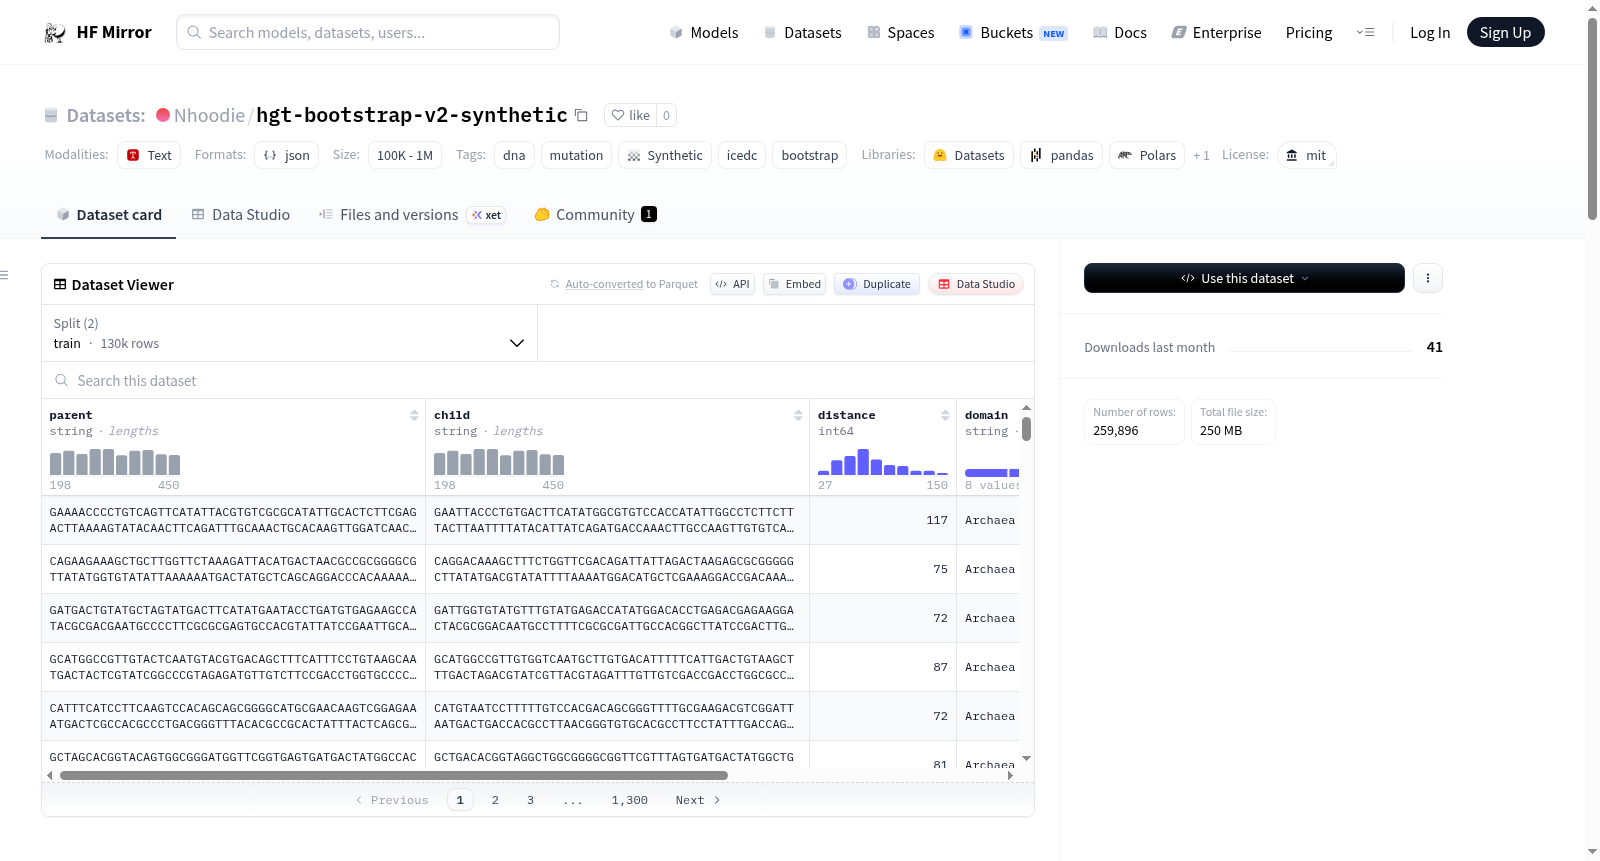
--- license: mit tags: - dna - mutation - synthetic - icedc - bootstrap size_categories: - 100K<n<1M --- --- ## ⚠️ IMPORTANT WARNING — Synthetic Data Quality This synthetic dataset was generated using the ICI-DC method from a bootstrap model in a degeneracy chain. The "mutations" are random nucleotide fills (Ti/Tv ratio ~0.50, entropy ~3.52/3.58) that do NOT reflect biological HGT mutation patterns (real Ti/Tv ~0.77, C>T and T>C dominated). Despite being 16× larger than v1, the mutation biology is equally unrealistic — entropy near-maximum and consensus rate ~1.7%. However, models trained on this data DID develop strong sequence representations (embedding AUC 0.780) even though mutation discrimination was degraded. The dataset has value for representation learning but NOT for mutation pattern learning. **Use with caution. The domain weighting is correct (Metazoa 33.6%, Archaea 25.2%, etc.) but the mutation patterns are artificial.** --- # HGT Bootstrap V2 Synthetic Pairs 259,896 synthetic mutation pairs (129,948 train + 129,948 eval) generated via ICI-DC using the bootstrap S2 checkpoint. ## Generation Details - **Model A**: Nhoodie/omni-dna-sad-mutation-bootstrap (S2 bootstrap checkpoint) - **Model B**: LongSafari/hyenadna-tiny-1k-seqlen-hf - **Source sequences**: 4,998 unique sequences from 8 taxonomic domains - **Gap intervals**: [3, 4, 5, 6] (codon distance between gaps) - **Seeds**: Train=[42, 137, 7, 23, 31, 89, 53], Eval=[101, 157, 27, 43, 51, 109, 73] - **Passes**: 4 × 7 = 28 per split - **Method**: Cross-sequence batched generation (BS=256, dual-process parallel on GTX 1080) ## Properties - Mean Levenshtein distance: 78.1 (median 72, stdev 26.6, range 24–150) - Mean codon changes: 26.0 per pair - Consensus rate: 1.72% (train), 1.73% (eval) - Zero duplicate pairs across splits - Zero overlap with v1 dataset - All 4,998 source sequences contribute equally (~26 per sequence per pass) ## Domain Distribution | Domain | Pairs | % | |--------|------:|--:| | Metazoa | 43,680 | 33.6% | | Archaea | 32,760 | 25.2% | | Bacteria | 16,380 | 12.6% | | Viridiplantae | 10,920 | 8.4% | | Viruses | 10,920 | 8.4% | | Viroids | 7,644 | 5.9% | | Lichenes_HGT | 5,460 | 4.2% | | Satellite_Viruses | 2,184 | 1.7% | ## Distance Distribution | Range | Count | % | |-------|------:|--:| | 25–49 | 17,185 | 13.2% | | 50–74 | 47,864 | 36.8% | | 75–99 | 38,806 | 29.9% | | 100–124 | 16,167 | 12.4% | | 125–150 | 9,926 | 7.6% | ## Format Each line is a JSON object: ```json {"parent": "ATGCGT...", "child": "ATGCGA...", "distance": 72, "domain": "Bacteria", "pair_type": "sad_synthetic", "quality": {"n_codon_changes": 24, "n_consensus": 0, "n_contested": 24, "n_stop": 0, "source_id": "SYNTH_Bacteria_0001", "generation_method": "FDI_dual_causal", "generation_pass": "gap3_seed42", "split": "train"}} ``` ## Related Datasets - [Nhoodie/hgt-real-mutation-pairs](https://huggingface.co/datasets/Nhoodie/hgt-real-mutation-pairs) — Real mutation pairs (3,317 train + 826 test) - [Nhoodie/hgt-bootstrap-v1-synthetic](https://huggingface.co/datasets/Nhoodie/hgt-bootstrap-v1-synthetic) — V1 synthetic pairs (8,112, previous iteration)