VishnuPJ/Malayalam_CultureX_IndicCorp_SMC
收藏资源简介:
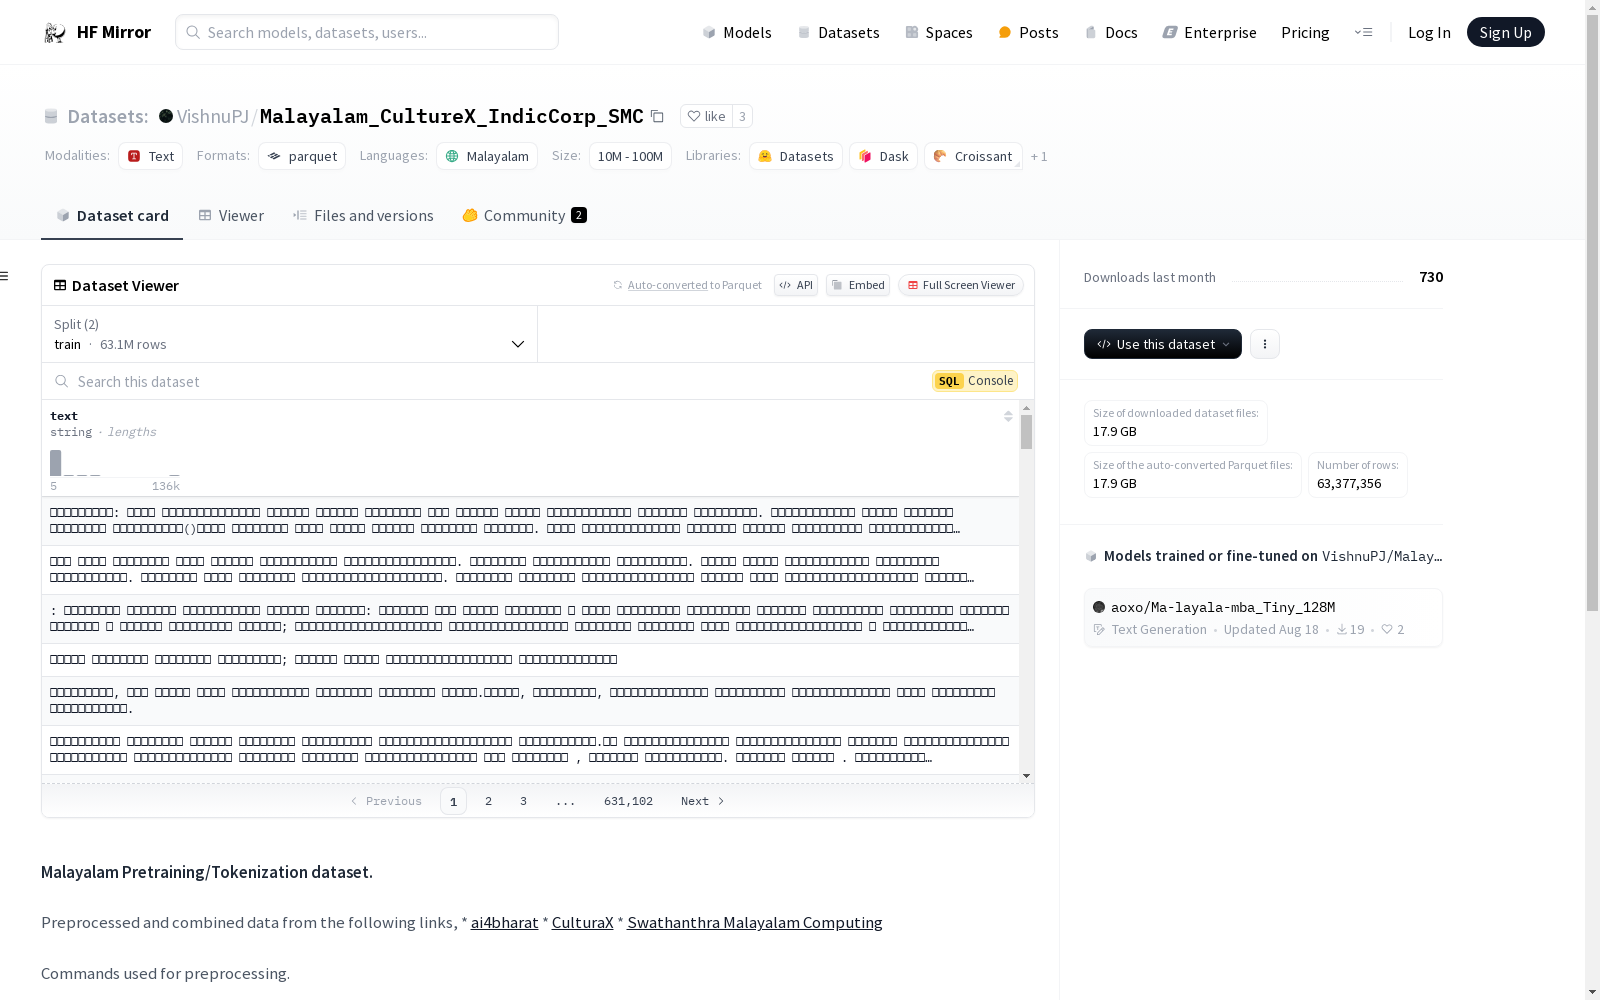
这是一个用于预训练和分词的马拉雅拉姆语数据集,数据来源于ai4bharat、CulturaX和Swathanthra Malayalam Computing等多个来源。数据集经过预处理,移除了非马拉雅拉姆语字符,合并了文本文件,并移除了字符数少于5的行。数据集包含train和test两个分割,分别有63110105和267251个样本,总大小为46864218447字节。
This is a Malayalam dataset intended for pre-training and tokenization. It is sourced from multiple providers including ai4bharat, CulturaX, and Swathanthra Malayalam Computing. The dataset has been preprocessed: non-Malayalam characters have been removed, text files have been merged, and lines with fewer than 5 characters have been filtered out. The dataset contains two splits, train and test, with 63110105 and 267251 samples respectively, and has a total size of 46864218447 bytes.
数据集概述
数据来源
- ai4bharat: ai4bharat
- CulturaX: CulturaX
- Swathanthra Malayalam Computing: Swathanthra Malayalam Computing
预处理步骤
-
移除非马拉雅拉姆语字符 bash sed -i s/[^ം-ൿ.,;:@$%+&?!() ]//g test.txt
-
合并特定目录下的所有文本文件 bash find SMC -type f -name *.txt -exec cat {} ; >> combined_SMC.txt
-
移除少于5个字符的行 bash grep -P [x{0D00}-x{0D7F}] data/ml.txt | awk length($0) >= 5 > preprocessed/ml.txt
数据集信息
-
特征
- 名称: text
- 数据类型: string
-
分割
- 训练集
- 字节数: 46611476142
- 样本数: 63110105
- 测试集
- 字节数: 252742305
- 样本数: 267251
- 训练集
-
下载大小: 17881832073
-
数据集大小: 46864218447
配置
- 默认配置
- 训练集路径: data/train-*
- 测试集路径: data/test-*