hayai-finetuning-dataset
收藏资源简介:
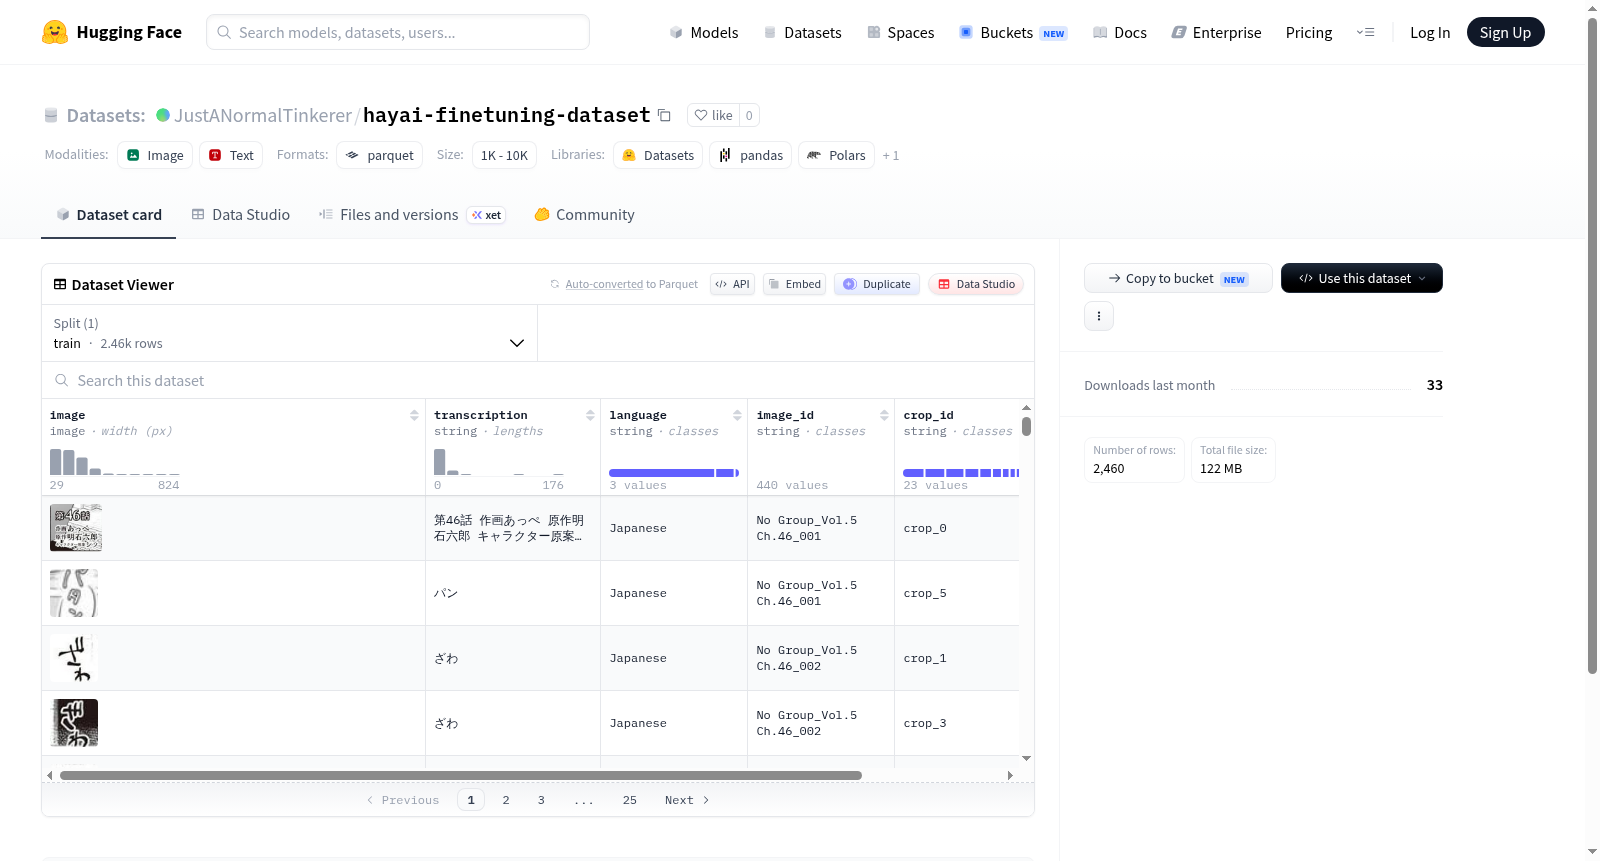
该数据集包含训练集,共2460个样本。每个样本包含以下字段:image(图像,类型为image)、transcription(转录文本,字符串)、language(语言,字符串)、image_id(图像ID,字符串)、crop_id(裁剪ID,字符串)、source(来源,字符串)。数据集总大小约为61.5MB。数据文件位于data/train-*路径下。该数据集的结构表明它可能用于图像到文本的识别任务,如OCR或手写识别,但具体任务和背景未在README中说明。
This dataset contains a training set with 2460 samples. Each sample includes the following fields: image (type: image), transcription (string), language (string), image_id (string), crop_id (string), source (string). The total size of the dataset is approximately 61.5MB. The data files are located under the data/train-* path. The structure of the dataset suggests it may be used for image-to-text recognition tasks, such as OCR or handwriting recognition, but the specific task and background are not described in the README.
Hayai Fine-tuning Dataset 数据集概述
基本信息
| 项目 | 内容 |
|---|---|
| 数据集名称 | hayai-finetuning-dataset |
| 数据集地址 | https://huggingface.co/datasets/JustANormalTinkerer/hayai-finetuning-dataset |
| 数据集大小 | 61,590,021 字节(约58.7 MB) |
| 下载大小 | 61,435,171 字节(约58.6 MB) |
数据特征(Features)
该数据集包含以下6个字段:
| 字段名 | 数据类型 | 说明 |
|---|---|---|
| image | Image(图像) | 图像数据 |
| transcription | String(字符串) | 转录文本 |
| language | String(字符串) | 语言标识 |
| image_id | String(字符串) | 图像唯一标识符 |
| crop_id | String(字符串) | 裁剪区域标识符 |
| source | String(字符串) | 数据来源 |
数据划分(Splits)
- 训练集(Train):
- 样本数量:2,460 条
- 数据字节数:61,590,021 字节
配置信息
- 配置名称:
default - 数据文件路径:
data/train-*(使用通配符匹配多个训练数据文件)
用途分析
该数据集包含图像与对应的转录文本,适用于图像到文本的微调任务,如光学字符识别(OCR)、图像描述生成或图像文本翻译等场景。数据集包含语言字段,可能支持多语言处理。