jurisprudencias_br
收藏资源简介:
该数据集为巴西判例(jurisprudência)数据集,由Juriscraper工具从巴西多个法院网站收集,以Parquet格式发布,便于通过Hugging Face Datasets、DuckDB、Polars、Pandas、PyArrow等工具直接使用。数据集包含来自以下法院的判决:jt、stf、stj、tjrj、tst_datajud。数据集的稳定逻辑标识为(tribunal, unique_key)对,用于去重。模式版本为1,包含以下字段:tribunal(法院)、base、unique_key、documento_id、numero_processo(案件号)、orgao_julgador(审判庭)、relator(报告法官)、data_julgamento(判决日期)、data_publicacao(发布日期)、ementa(摘要)、inteiro_teor(全文)、classe(案件类别)、dg_unique、partes(当事人信息,JSON数组)、data_json(原始完整数据)、scraped_at(采集时间戳)、spider_name(爬虫名称)。其中partes字段为UTF-8 JSON数组,包含当事人名称(nome)、法律角色(polo:ativo为原告/上诉人,passivo为被告/被上诉人)、原始角色标签(tipo)。数据集的采集时间戳scraped_at记录本地SQLite数据库存储时间,data_julgamento和data_publicacao为标准化的YYYY-MM-DD字符串,可能为空。不同法院的原始数据可能不同,data_json字段保留了所有未在扁平字段中体现的原始信息。数据集为公开领域政府文件,但建议商业使用前核实。数据集以确定性快照方式发布,当前快照边界(最大本地ID)为233376,发布行数为88004,分片数为2。
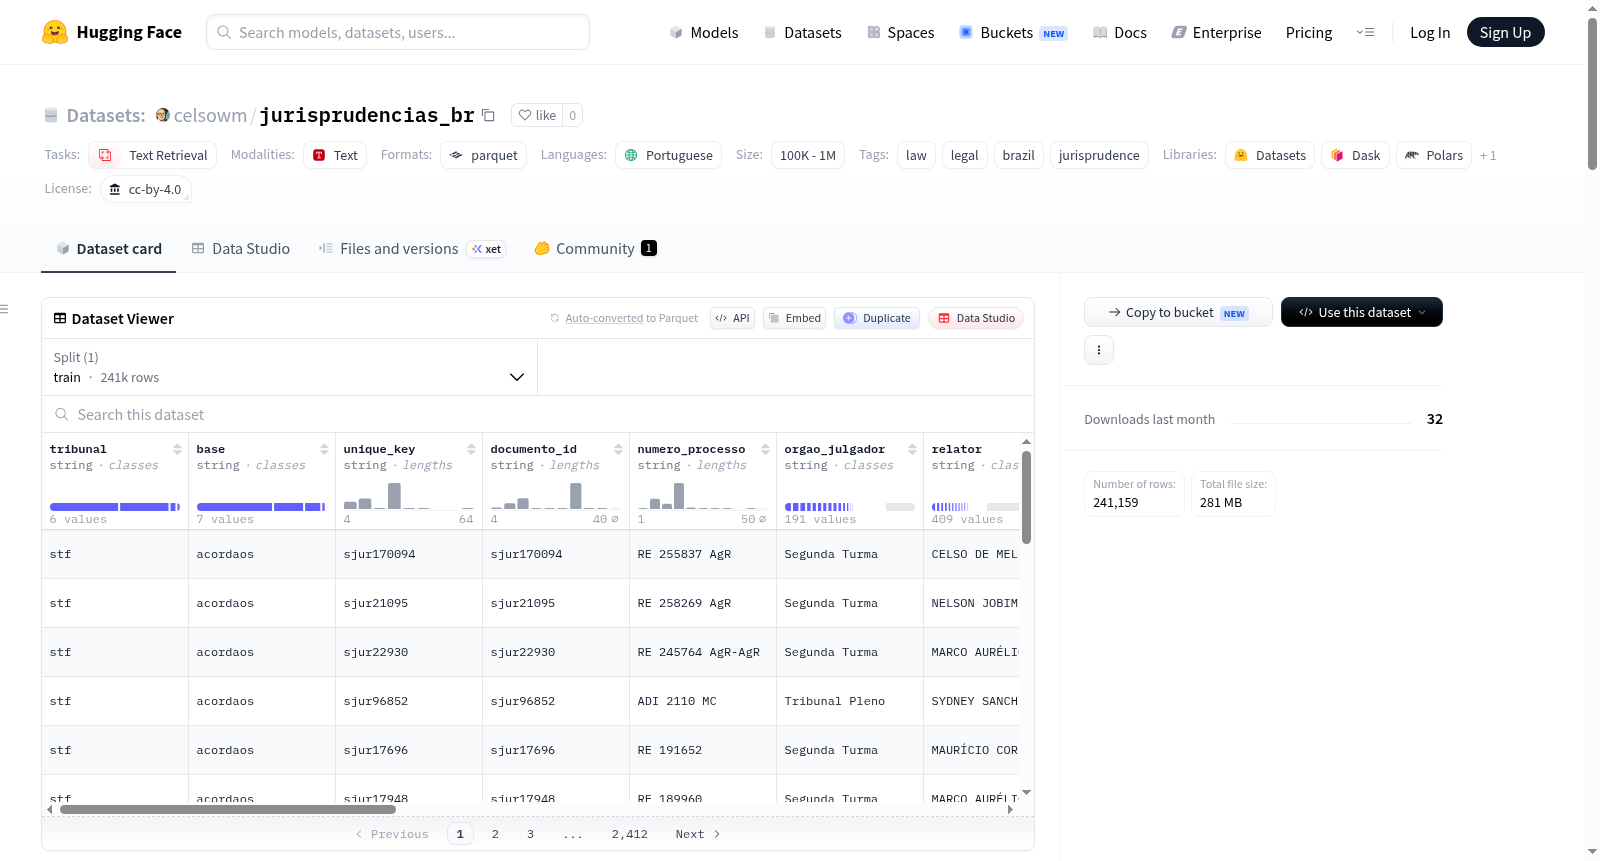
This dataset is a Brazilian jurisprudence dataset collected by the Juriscraper tool from multiple Brazilian court websites, published in Parquet format for direct use with Hugging Face Datasets, DuckDB, Polars, Pandas, PyArrow, and other tools. It includes judgments from the following courts: jt, stf, stj, tjrj, tst_datajud. The stable logical identifier for deduplication is the (tribunal, unique_key) pair. Schema version 1 contains fields: tribunal (court), base, unique_key, documento_id, numero_processo (case number), orgao_julgador (chamber), relator (reporting judge), data_julgamento (judgment date), data_publicacao (publication date), ementa (summary), inteiro_teor (full text), classe (case type), dg_unique, partes (parties information as JSON array), data_json (raw complete data), scraped_at (scraping timestamp), spider_name (spider name). The partes field is a UTF-8 JSON array with fields: nome (name), polo (legal role: ativo for plaintiff/appellant, passivo for defendant/appellee), tipo (original role label). The scraped_at timestamp records the storage time in the local SQLite database. data_julgamento and data_publicacao are standardized YYYY-MM-DD strings, possibly empty. Raw data varies by court; the data_json field preserves all original information not captured in flat fields. The dataset consists of public domain government documents, but commercial use verification is recommended. It is published as deterministic snapshots, with current snapshot boundary (max local ID) 233376, 88004 rows, and 2 shards.
数据集概述
celsowm/jurisprudencias_br 是一个巴西法律判决(jurisprudência)数据集,由 Juriscraper 工具收集,以 Parquet 格式发布,可直接用于 Hugging Face Dataset Viewer、datasets、DuckDB、Polars、Pandas 和 PyArrow。
范围
数据集包含来自巴西多个法院的判决,支持的法院(通过 tribunal 字段标识)包括:
jt(劳动法院)stf(联邦最高法院)stj(高等法院)tjrj(里约热内卢州法院)tjsp(圣保罗州法院)tst_datajud(高等劳动法院)
时间戳语义
scraped_at:记录 Juriscraper 将数据存入本地 SQLite 数据库的时间(ISO-8601 UTC 格式),表示采集时间而非法院发布时间。data_julgamento/data_publicacao:从法院数据中提取的标准化日期(YYYY-MM-DD格式),可能为 null。
数据结构(Schema 版本 1)
数据集中不包含本地的自增 id 字段,稳定的逻辑文档标识为 (tribunal, unique_key) 组合,这也是去重键。
| 列名 | 类型 |
|---|---|
tribunal |
string (nullable) |
base |
string (nullable) |
unique_key |
string (nullable) |
documento_id |
string (nullable) |
numero_processo |
string (nullable) |
orgao_julgador |
string (nullable) |
relator |
string (nullable) |
data_julgamento |
string (nullable) |
data_publicacao |
string (nullable) |
ementa |
string (nullable) |
inteiro_teor |
string (nullable) |
classe |
string (nullable) |
dg_unique |
string (nullable) |
partes |
string (nullable) |
data_json |
string (nullable) |
scraped_at |
string (nullable) |
spider_name |
string (nullable) |
诉讼当事人(polos)
partes 字段是一个 UTF-8 JSON 数组,每个当事人一个对象,包含:
nome:当事人姓名(保留原始大小写和重音符号)。polo:规范立场,ativo(原告/上诉人)或passivo(被告/被上诉人)。tipo:法院提供的原始角色标签(例如APELANTE、APELADO、AGTE、AGDO、AUTOR、RÉU、RECORRENTE、RECLAMANTE等)。对于没有结构化当事人信息的法院(如 TJRJ),会从案件详情页补充;部分法院的partes可能为 null。
来源差异
不同法院返回的数据结构不同。扁平结构之外的字段会以原始形式嵌入到 data_json(UTF-8 JSON)中,需要非标准字段时应优先查看 data_json。
许可与来源
判决书属于巴西公共领域政府作品,但商业使用前需核实。数据来源为各法院官网,Juriscraper 是非官方收集工具。
更新频率
数据集以完整确定性快照形式发布,来源于本地权威 SQLite 数据库。具体发布流程见项目文档 docs/HUGGINGFACE_DATASET_PUBLISHING_REFACTOR_PLAN.md。
使用示例
使用 datasets:
python from datasets import load_dataset
ds = load_dataset("celsowm/jurisprudencias_br")
使用 DuckDB / SQL:
sql SELECT tribunal, count() FROM hf://datasets/celsowm/jurisprudencias_br/data/.parquet GROUP BY tribunal;
使用 PyArrow / Pandas:
python import pyarrow.dataset as ds dataset = ds.dataset( f"hf://datasets/celsowm/jurisprudencias_br/data/", format="parquet", )
快照元数据
- 快照边界(本地最大 id):
270636 - 发布行数:
240627 - 分片数:
5
遗留原始快照
如果存在 jurisprudencia.db,这是抓取过程中使用的 SQLite 原始操作快照,不是推荐的机器学习格式。推荐使用 data/ 下的 Parquet 文件进行分析和训练。