
what-ai-benchmarks-actually-measure
收藏资源简介:
该数据集由多所顶尖研究机构联合创建,旨在系统性地探究AI基准测试的构念效度。数据集囊括了53个模型在56个能力与安全基准上的逐项输出与评分,涵盖了来自SafetyPrompts与HELM等权威来源的基准测试项。创建过程中,研究团队对超过1000项的基准进行等量采样,并以零样本、温度1的设定收集模型响应,随后依据各基准既定指标进行评分。这一数据集为揭露基准测试是否真正测量其声称概念提供了实证基础,尤其适用于验证基准的收敛效度与判别效度,并揭示了诸如BBQ-accuracy等基准可能测量非预期概念的潜在问题。
This dataset was jointly created by multiple top-tier research institutions, aiming to systematically investigate the construct validity of AI benchmarks. It contains itemized outputs and scores of 53 models across 56 capability and safety benchmarks, including benchmark items from authoritative sources such as SafetyPrompts and HELM. During the dataset's development, the research team performed equal sampling across over 1,000 benchmarks, collected model responses under the zero-shot setting with temperature set to 1, and subsequently scored the responses in accordance with the predefined metrics of each respective benchmark. This dataset offers an empirical basis for verifying whether benchmarks actually measure the concepts they claim to evaluate, and is particularly applicable for validating the convergent and discriminant validity of benchmarks, while uncovering potential issues where benchmarks like BBQ-accuracy may measure unintended concepts.
What AI Benchmarks Actually Measure 数据集概述
数据集简介
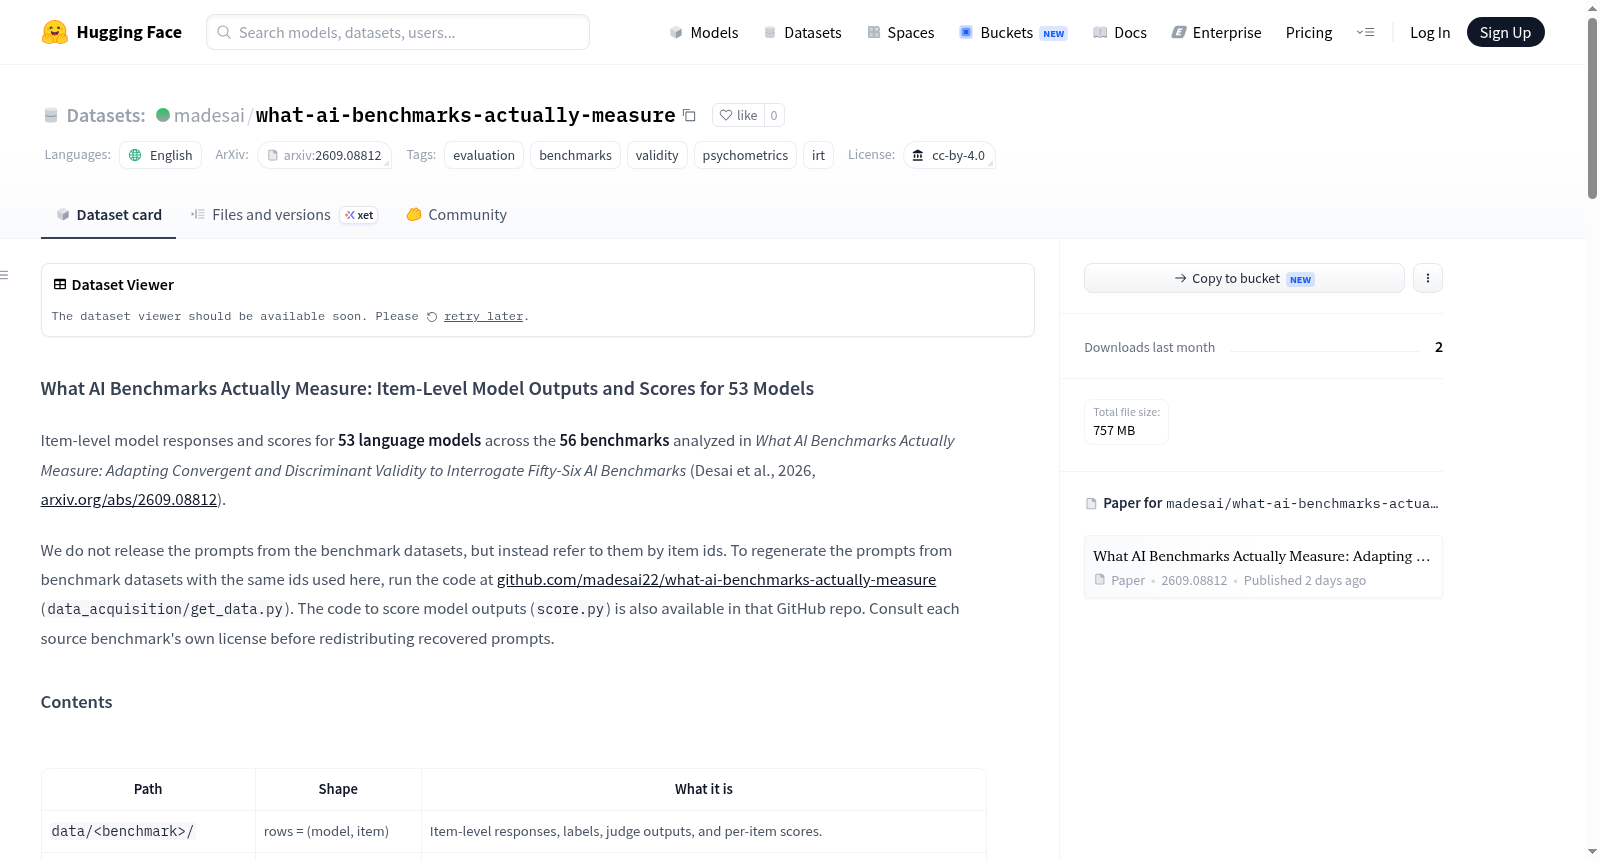
What AI Benchmarks Actually Measure 是一个用于评估AI基准测试有效性的数据集,对应论文 What AI Benchmarks Actually Measure: Adapting Convergent and Discriminant Validity to Interrogate Fifty-Six AI Benchmarks(Desai et al., 2026)。数据集包含53个语言模型在56个基准测试上的逐项(item-level)模型输出和评分结果,许可证为 CC-BY-4.0,语言为英文。
数据内容与结构
该数据集不直接发布基准测试的提示词(prompts),而是通过 item id 引用原始基准。用户可通过 GitHub 仓库(github.com/madesai22/what-ai-benchmarks-actually-measure)中的代码重新生成提示词和评分结果。
| 路径 | 形状 | 内容 |
|---|---|---|
data/<benchmark>/ |
行 = (模型, 条目) | 逐项响应、标签、评判器输出和逐项得分 |
scores/<benchmark> |
行 = 条目, 列 = 模型 | 每个模型在每个条目上的得分矩阵(大多为二值正确/错误,少数为连续得分) |
aggregate/model_scores |
行 = 模型, 列 = 基准 | 每个模型的基准级得分 |
metadata/benchmarks.csv |
每个 (基准, 子集) 一行 | 图表标签、评分策略、评判器信息 |
行数据结构
每行数据包含以下核心列:
model_id benchmark paper_status item_id subset response cleaned_response label score
response:模型原始输出cleaned_response:解析后的答案score:逐项得分subset:用于区分共享同一基准配置的行(如 or_bench、xstest 和 sgxs_test 的refusal和overrefusal取值)
另有 paper_status 列标记因过饱和或格式不符合而被排除分析的数据。
模型覆盖
数据集涵盖来自以下机构的53个模型:
- Alibaba:Qwen 系列(包括 Qwen 1.5/2/2.5/3 多个规模版本)
- AllenAI:OLMo 2 系列和 OLMoE
- Anthropic:Claude 3.5 Haiku、Claude Sonnet 4.5
- AI21:Jamba Mini
- Databricks:DBRX Instruct
- DeepSeek:DeepSeek V3、V4-flash
- Google:Gemma 2/3 系列
- Meta:Llama 2、Llama 3.2、Llama 3.3 系列
- Microsoft:Phi-3.5 和 Phi-4 系列
- Mistral:Mistral 7B、Mixtral、Mistral Nemo/Small/Large 等
- Moonshot AI:Moonlight 16B-A3B
- 01.AI:Yi 系列
- OpenAI:GPT-3.5 Turbo、GPT-4 Turbo、GPT-4o mini、GPT-5 nano、o1、o1-mini、o3-mini
- TII:Falcon3 系列
- xAI:grok-4-1-fast-reasoning
LLM 评判器
经过安全评判的基准测试包含每位评判器的输出,包括 judge_<name>_raw_output、judge_<name>_verdict、judge_<name>_full_refusal_acc 和 judge_<name>_indirect_refusal_acc 列。其中:
- 提示型评判器(Qwen、Llama)包含
raw_output和解析出的verdict - 微调分类器评判器(如 LLaMA-2-CLS、Mistral、WildGuard、MD-Judge、LlamaGuard、WalledGuard)仅输出标签,
raw_output始终为空 - 论文主要使用 Qwen3-30B 评判器;Llama-3.3-70B 评判器的输出也被包含以供比较
*_refusal_acc是准确率而非拒绝率,其极性随提示词的label翻转
内容警告
数据集中 HarmBench、SorryBench、SG-Bench-jailbreak、OR-Bench、XSafety、SALAD-Bench 和 WildGuard 包含模型对对抗性和有害提示的响应(包括成功的越狱)。RealToxicityPrompts 和 BOLD 包含有毒内容生成。personal_info_leak 子集包含模型回忆出的真实电子邮件地址(来自 Enron 公共语料库)。
配置列表
数据集包含超过100个配置(config),主要包括三类:
- 数据配置(64个):各基准测试的模型响应数据,如
aegis、babi、bbq、gsm8k、mmlu、hellaswag、truthful_qa、wmdp等,每个配置对应一个data/<benchmark>/data.parquet文件 - 评分配置(50个):以
scores__为前缀的各基准测试评分矩阵,对应scores/<benchmark>.parquet文件 - 聚合与元数据配置(2个):
model_scores(模型基准级得分)和metadata__benchmarks(基准元数据)
- 1What AI Benchmarks Actually Measure: Adapting Convergent and Discriminant Validity to Interrogate Fifty-Six AI Benchmarks密歇根大学; 斯坦福大学; 耶鲁大学; 微软研究院; Abridge; 康奈尔科技 · 2026年



