chat_turns_probe_trong_24
收藏资源简介:
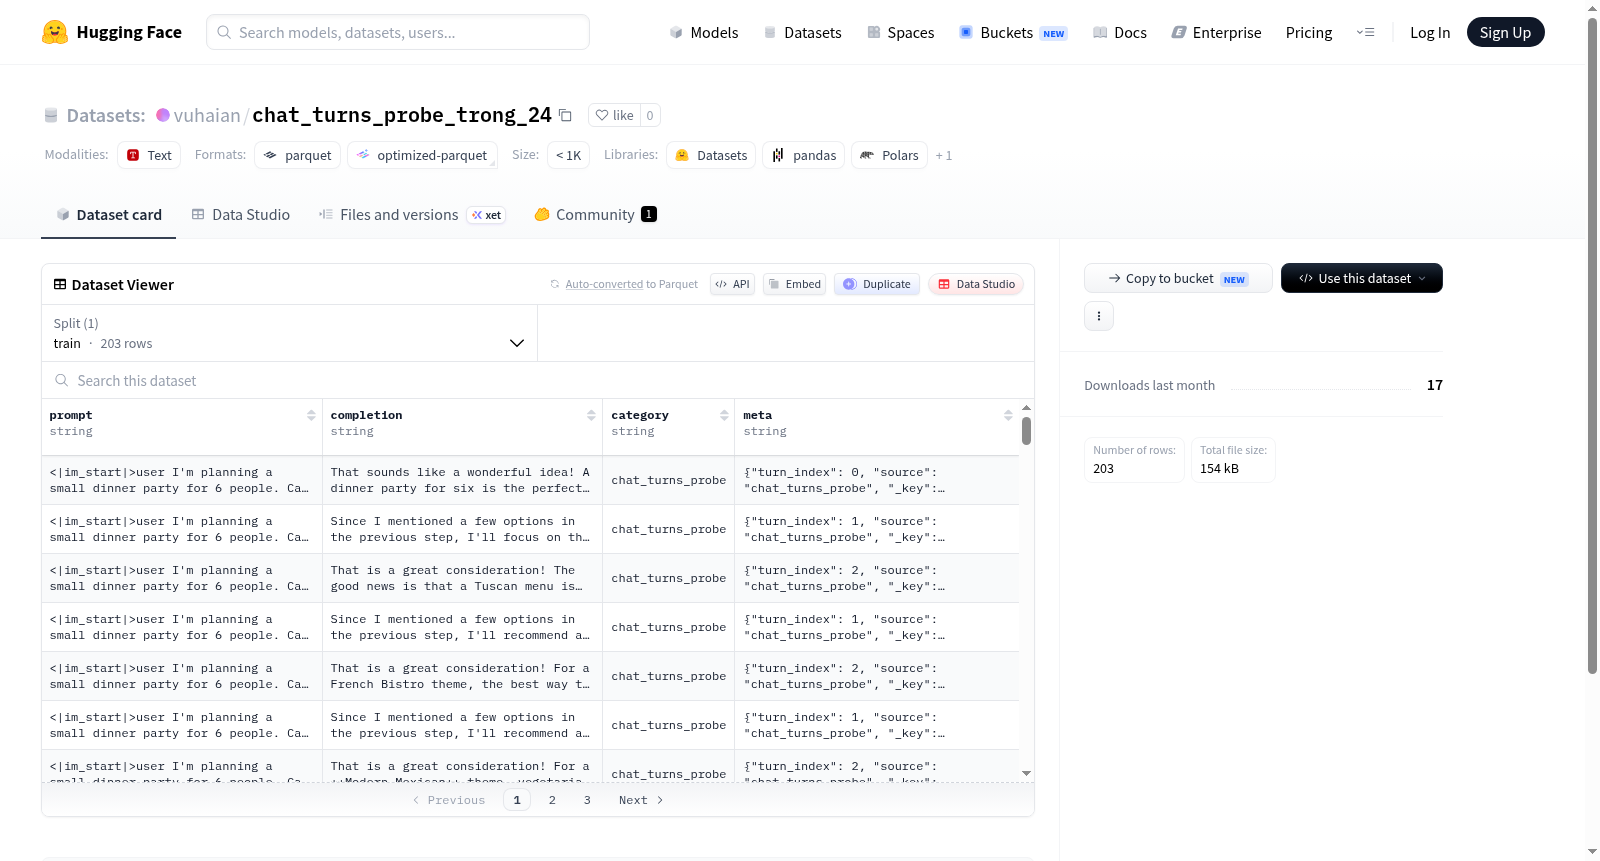
该数据集是一个结构化的文本对集合,专门设计用于支持文本生成或指令遵循类任务。数据集中每个样本包含四个核心字段:prompt(输入提示或问题)、completion(对应的输出回答或生成文本)、category(样本所属的类别)以及meta(包含额外信息的元数据字段)。数据集规模为203个训练样本,以纯文本形式组织。基于其数据结构,该数据集适用于训练或评估大语言模型在理解提示并生成相应回复方面的能力,例如开放域问答、对话生成或任务导向的指令执行。
This dataset is a structured collection of text pairs, specifically designed to support text generation or instruction-following tasks. Each sample in the dataset includes four core fields: prompt (input prompt or question), completion (corresponding output answer or generated text), category (the category to which the sample belongs), and meta (a metadata field containing additional information). The dataset consists of 203 training samples, organized in plain text format. Based on its structure, it is suitable for training or evaluating large language models in tasks such as open-domain question answering, dialogue generation, or task-oriented instruction execution.
数据集概述
- 数据集名称:
chat_turns_probe_trong_24 - 数据集地址: https://huggingface.co/datasets/vuhaian/chat_turns_probe_trong_24
- 数据集大小: 约 423,280 字节
- 下载大小: 约 151,194 字节
数据特征
数据集包含以下字段:
- prompt: 字符串类型,表示用户输入或问题。
- completion: 字符串类型,表示模型输出或回答。
- category: 字符串类型,表示对话类别或标签。
- meta: 字符串类型,包含额外的元数据信息。
数据划分
数据集仅包含一个划分:
| 划分名称 | 样本数量 | 数据大小 |
|---|---|---|
| train | 203 | 423,280 字节 |
配置文件
- 配置名称:
default - 数据文件路径:
data/train-*