kanitakorn-th-sft
收藏资源简介:
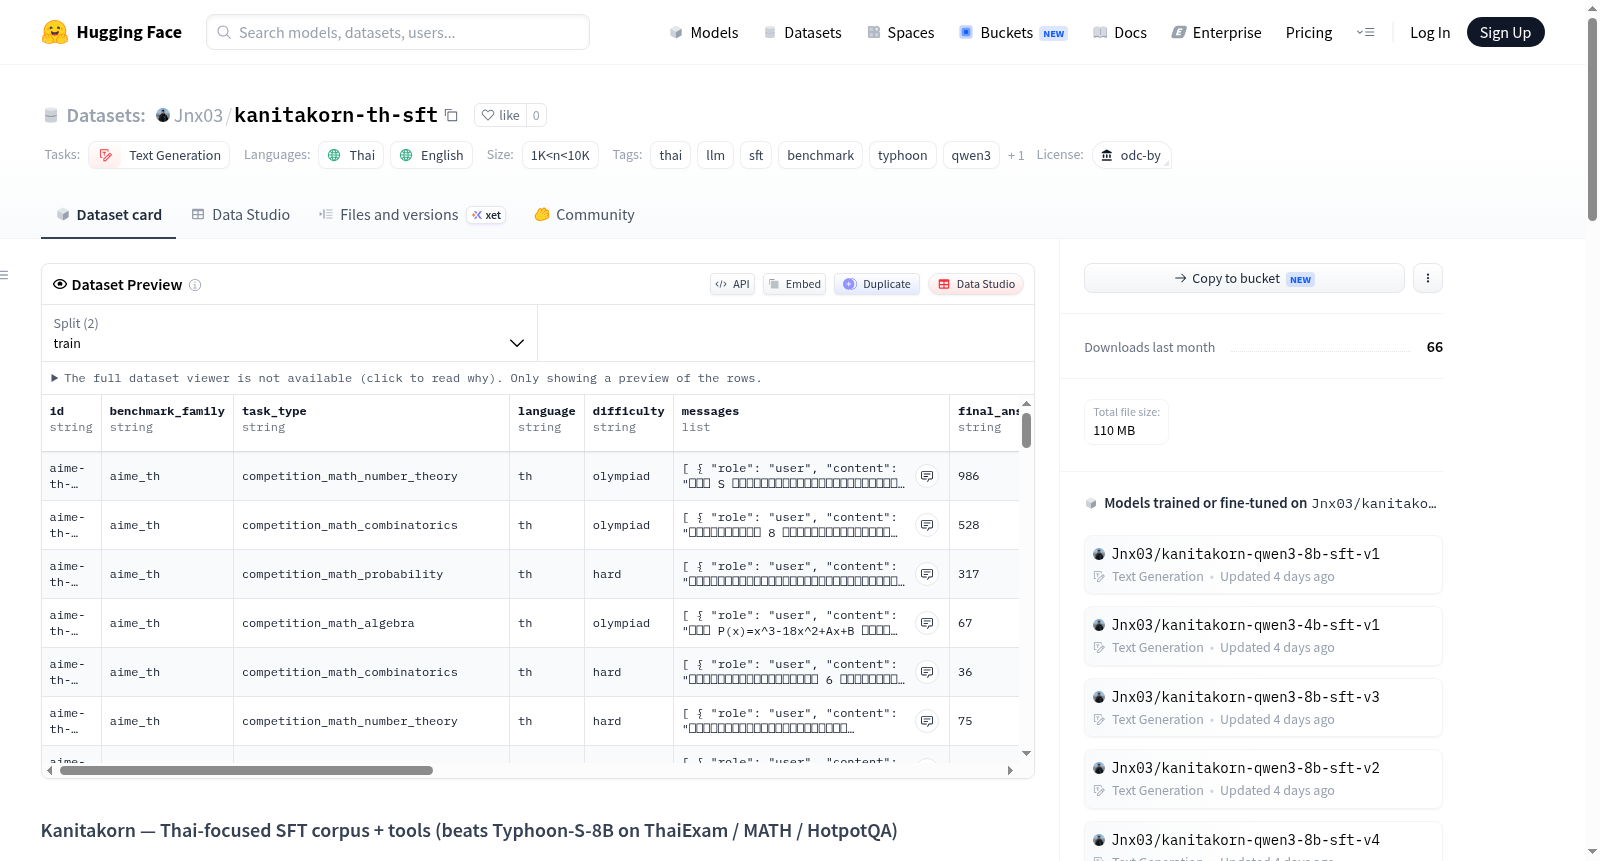
Kanitakorn是一个专注于泰语任务的监督微调(SFT)语料库及相关工具链。该数据集旨在对Qwen3-8B和Qwen3-4B-Instruct-2507等大语言模型进行微调,以提升其在多项泰语基准测试上的性能,使其超越Typhoon-S-8B模型。数据集原始包含4,147条记录,通过利用Typhoon-S-instruct-post-training数据集进行第二轮增强后,总规模扩展至23,715条。数据涵盖多种任务类型,构成了一个多领域的泰语SFT语料库。数据集配套提供了完整的训练和评估工具链,包括LoRA SFT训练器、多种推理脚本、针对不同基准测试(如ThaiExam、MATH、HotpotQA、IFEval-TH、MT-Bench-TH等)的评分模块以及数据集过滤和增强管道。该资源主要用于泰语大语言模型的指令微调、性能基准测试以及相关研究。
Kanitakorn is a supervised fine-tuning (SFT) corpus and related toolchain focused on Thai language tasks. This dataset is designed to fine-tune large language models such as Qwen3-8B and Qwen3-4B-Instruct-2507, aiming to enhance their performance on multiple Thai benchmark tests and surpass the Typhoon-S-8B model. Originally containing 4,147 records, the dataset was expanded to 23,715 entries through a second round of enhancement using the Typhoon-S-instruct-post-training dataset. It covers various task types, forming a multi-domain Thai SFT corpus. The dataset is accompanied by a comprehensive training and evaluation toolchain, including a LoRA SFT trainer, multiple inference scripts, scoring modules for different benchmarks (e.g., ThaiExam, MATH, HotpotQA, IFEval-TH, MT-Bench-TH), as well as data filtering and enhancement pipelines. This resource is primarily used for instruction fine-tuning, performance benchmarking, and related research on Thai large language models.