clasp-audioset
收藏资源简介:
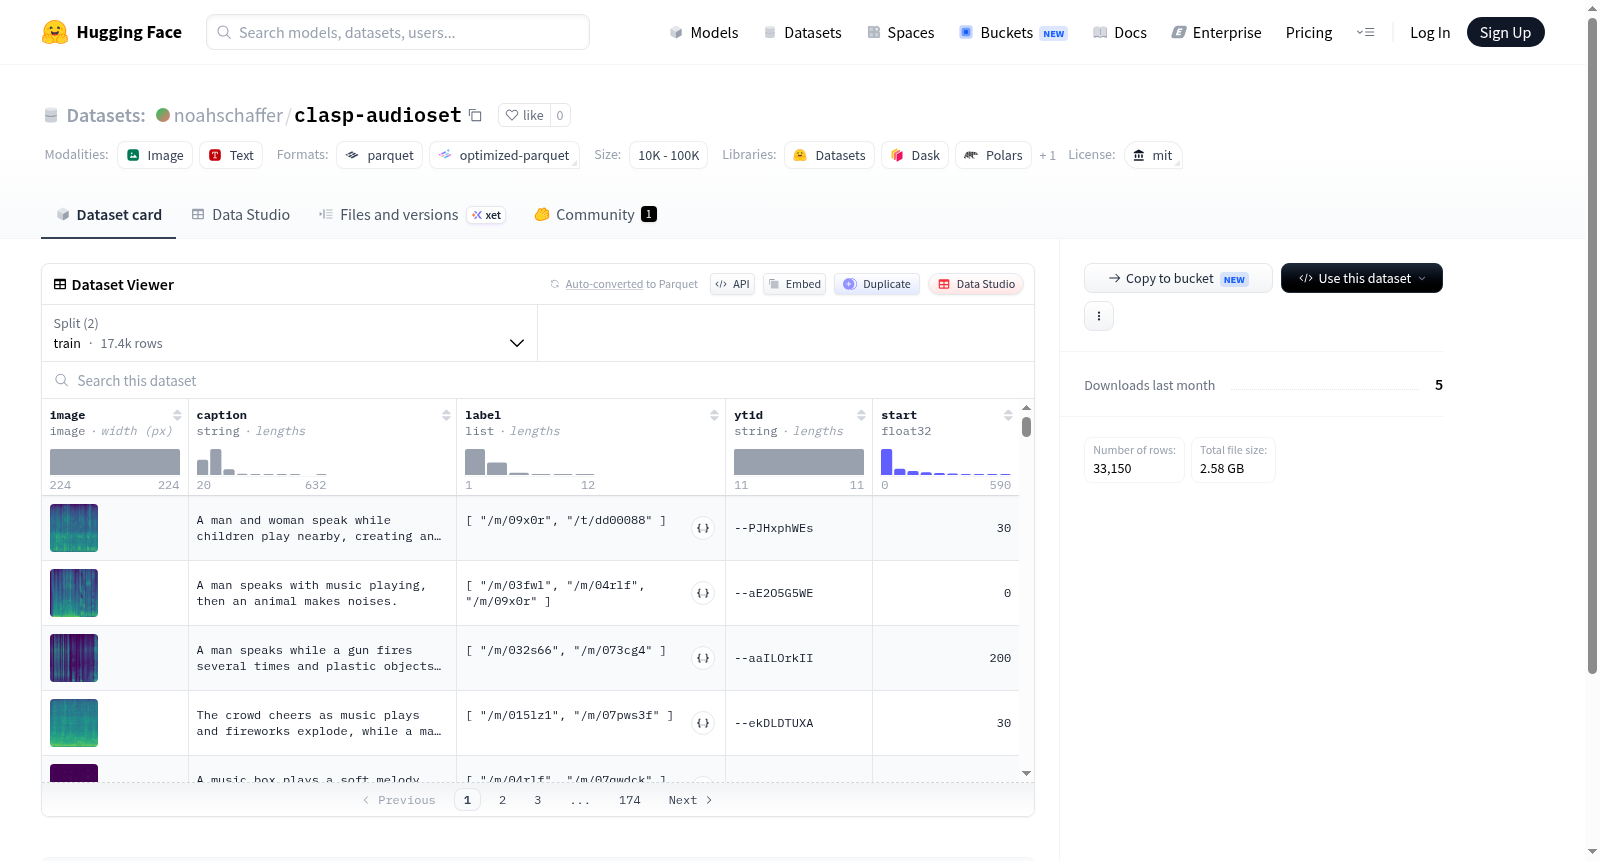
该数据集是一个多模态数据集,包含图像及其相关的文本描述和标签。每个数据样本由以下字段构成:image(图像数据)、caption(描述图像的文本字符串)、label(一个或多个分类标签的字符串列表)、ytid(字符串标识符,可能关联视频来源)以及 start(浮点数,可能表示时间起始点)。数据集总规模约为 2.6 GB,包含 17,372 个训练样本和 15,778 个评估样本,适用于多模态任务,如图像描述生成、图像-文本匹配、多标签图像分类或视频片段分析。数据集采用 MIT 开源许可证。
This dataset is a multimodal dataset containing images along with their associated textual descriptions and labels. Each data sample consists of the following fields: image (image data), caption (text string describing the image), label (a list of strings representing one or more classification labels), ytid (a string identifier possibly linked to a video source), and start (a float that may indicate a temporal starting point). The total dataset size is approximately 2.6 GB, comprising 17,372 training samples and 15,778 evaluation samples, and is suitable for multimodal tasks such as image caption generation, image-text matching, multi-label image classification, or video segment analysis. The dataset is licensed under the MIT open-source license.
数据集概述:CLASP-AudioSet
- 许可证:MIT
- 数据集大小:约2.59 GB(下载大小约2.58 GB)
特征
数据集包含以下字段:
- image(图像)
- caption(文本描述)
- label(标签,字符串列表)
- ytid(YouTube视频ID)
- start(起始时间点,浮点数)
数据划分
数据集分为两个子集:
- 训练集(train):17,372 个样本,约1.36 GB
- 评估集(eval):15,778 个样本,约1.23 GB
配置文件
- 配置名称:default
- 数据文件路径:
- 训练集:
data/train-* - 评估集:
data/eval-*
- 训练集: