swebench_verified_random_100_folders_a1_stack_pytest_synthetic_gpt5nano_20260818_162724
收藏资源简介:
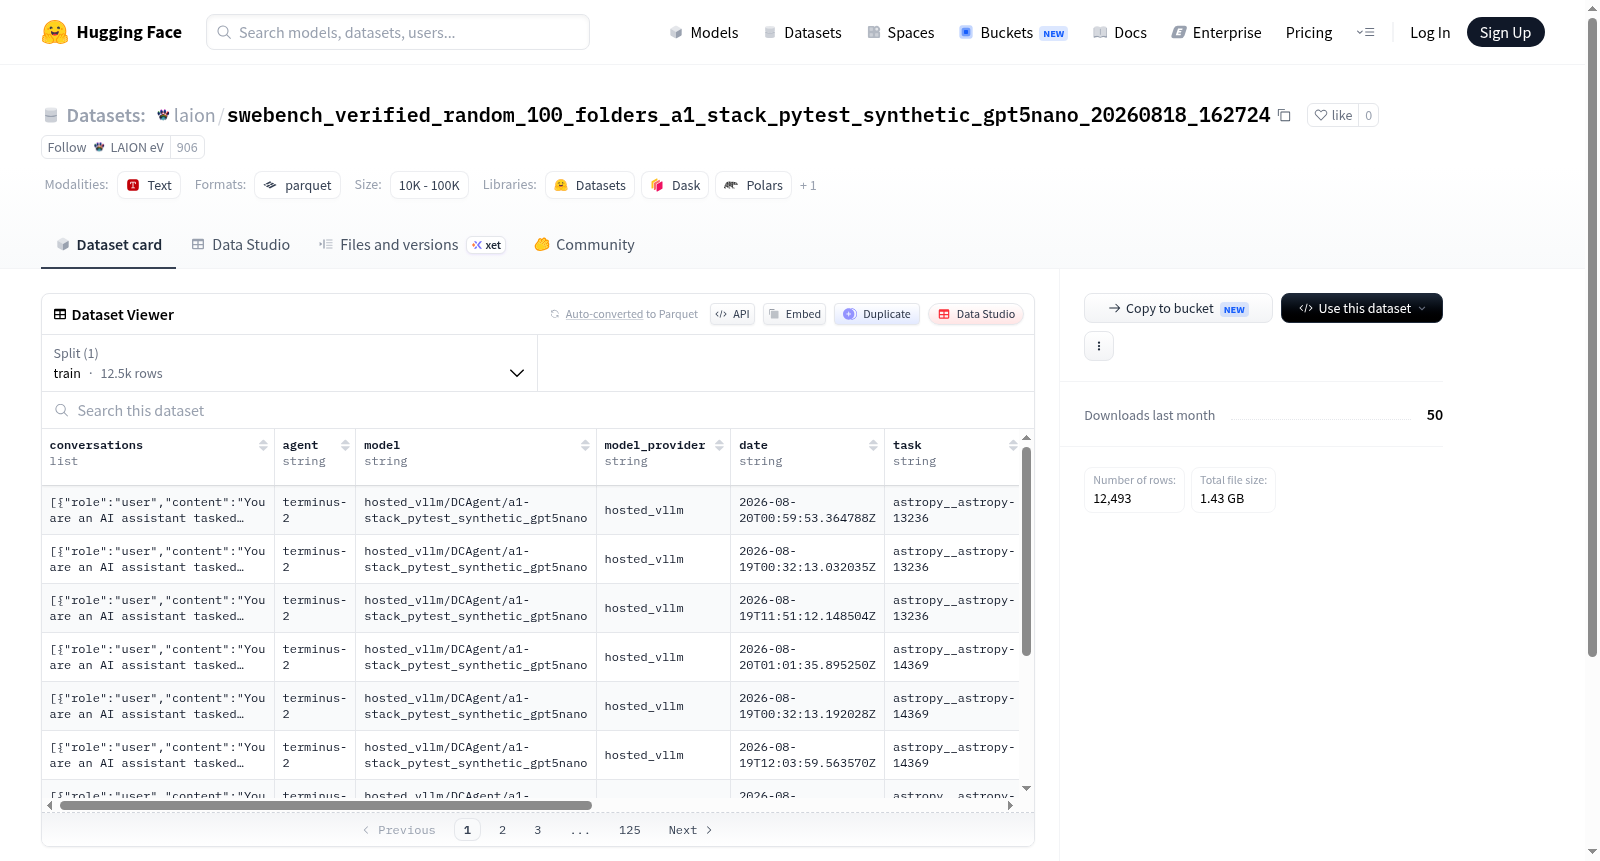
该数据集包含多轮对话记录,每条样本包含以下字段:对话轮次(conversations,含角色和内容)、代理名称(agent)、模型名称(model)、模型提供商(model_provider)、日期(date)、任务(task)、剧集(episode)、运行ID(run_id)、实验名称(trial_name)、结果(result)、验证器输出(verifier_output)以及追踪来源(trace_source)。数据集仅提供训练集,共12493个样本,总大小约2.37GB,数据文件位于data/train-*路径下。该数据集可能用于训练或评估对话代理、模型推理或任务执行效果。
This dataset contains multi-turn conversation records. Each sample includes the following fields: conversation turns (conversations, including role and content), agent name (agent), model name (model), model provider (model_provider), date (date), task (task), episode (episode), run ID (run_id), trial name (trial_name), result (result), verifier output (verifier_output), and trace source (trace_source). The dataset only provides a training set, with a total of 12493 samples, approximately 2.37GB in size, and data files located under the data/train-* path. This dataset may be used for training or evaluating dialogue agents, model reasoning, or task execution performance.
数据集详情总结
基本信息
- 数据集名称:laion/swebench_verified_random_100_folders_a1_stack_pytest_synthetic_gpt5nano_20260818_162724
- 数据集地址:https://huggingface.co/datasets/laion/swebench_verified_random_100_folders_a1_stack_pytest_synthetic_gpt5nano_20260818_162724
数据集特征
该数据集包含以下特征字段:
| 字段名 | 类型 | 说明 |
|---|---|---|
conversations |
列表 | 对话记录,由 role(角色,字符串)和 content(内容,字符串)组成 |
agent |
字符串 | 智能体标识 |
model |
字符串 | 使用的模型名称 |
model_provider |
字符串 | 模型提供方 |
date |
字符串 | 日期 |
task |
字符串 | 任务描述 |
episode |
字符串 | 会话轮次 |
run_id |
字符串 | 运行标识符 |
trial_name |
字符串 | 试验名称 |
result |
字符串 | 结果 |
verifier_output |
字符串 | 验证器输出 |
trace_source |
字符串 | 追踪来源 |
数据划分
- 数据划分:仅包含
train划分 - 训练集样本数:12,493 条
- 训练集大小:2,376,764,652 字节(约 2.38 GB)
- 下载大小:1,432,458,370 字节(约 1.43 GB)
- 总数据集大小:2.38 GB
数据文件
- 数据文件路径:
data/train-*(使用通配符匹配多个文件) - 配置名称:
default