fitfuel-recipes
收藏资源简介:
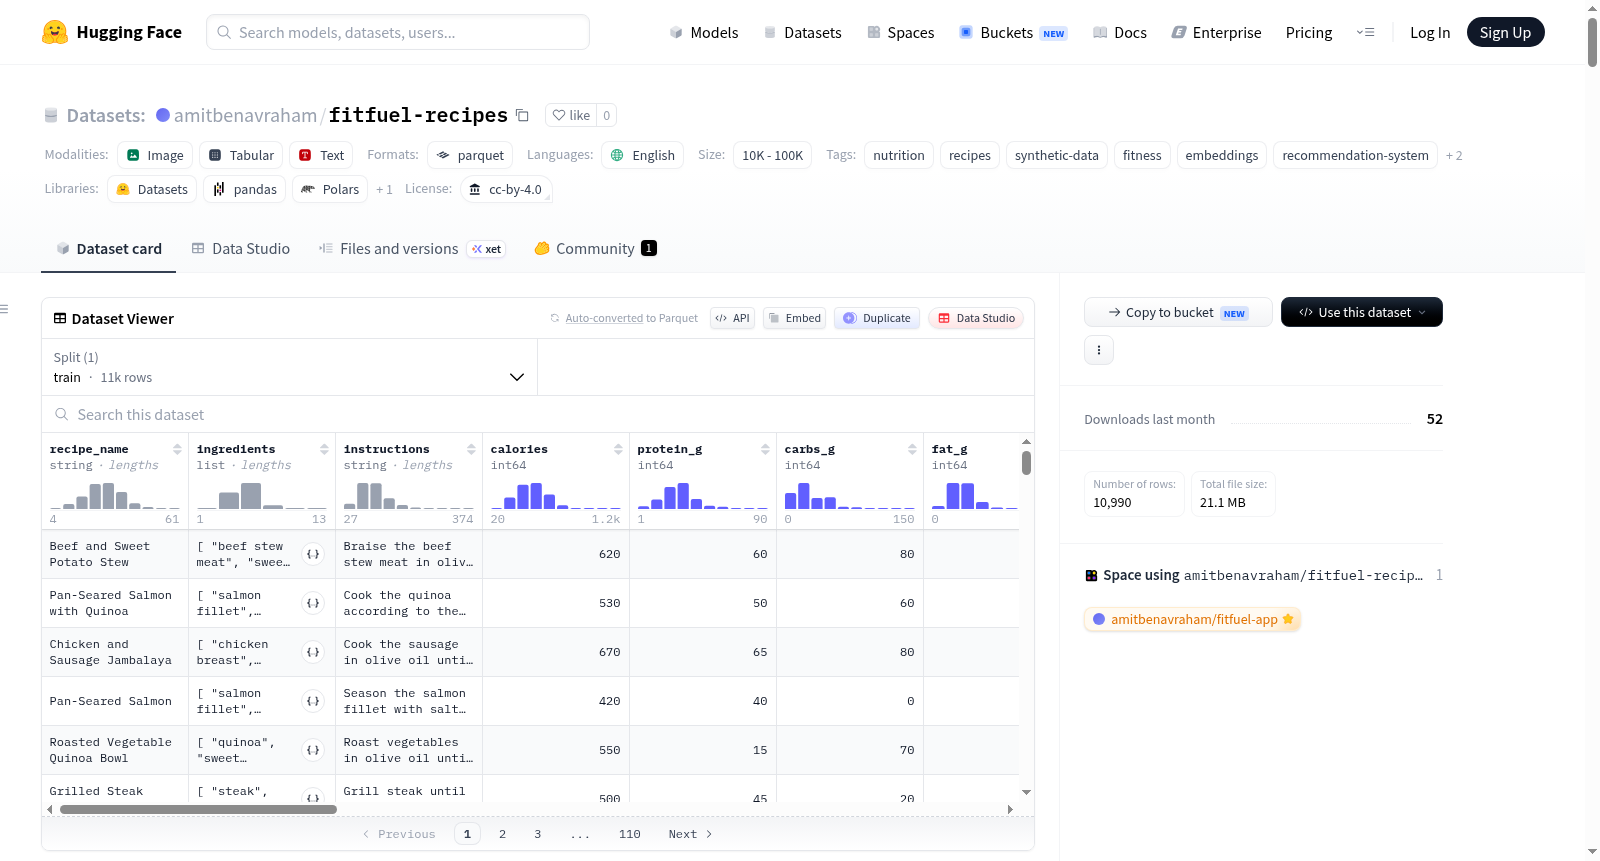
FitFuel Recipes 数据集是一个合成生成的食谱数据集,专为 FitFuel 项目(Reichman University 的 AI 应用课程)设计。该数据集包含 10,169 个经过清洗的食谱,通过 Groq API(llama-3.1-8b-instant)生成,并使用 Pydantic 模式进行验证,种子固定为 42。每个食谱包含以下字段:食谱名称(recipe_name)、配料列表(ingredients)、烹饪步骤(instructions)、AI 估算的营养值(calories, protein_g, carbs_g, fat_g)、目标标签(goal_tag:bulking/cutting/maintenance)、餐型(meal_type:breakfast/lunch/dinner/snack)、难度(difficulty:beginner/intermediate/advanced)、准备时间(prep_time_min)、菜系(cuisine)、原始过敏原标签(allergen_tags_model_raw,不可靠,仅用于审计)、最终确定性过敏原标签(allergen_tags_final,基于配料的正则表达式推导)、饮食分类(is_vegan, is_vegetarian, is_pescatarian, diet_tag,基于配料确定性推导)、以及营养一致性指标(calories_implied, calorie_diff, calorie_diff_pct)。数据集还包含生成模型来源(source_model)。已知限制包括:原始过敏原标签与确定性方法的一致性仅约 41%,卡路里与宏量营养素推算值差异超过 10 kcal 的样本约占 80%,存在网格覆盖缺口(216 种(目标×餐型×菜系×难度)组合中有 27 种无食谱),以及食谱名称不唯一(约 95% 唯一)。域逻辑检查显示目标标签与卡路里、难度与准备时间之间存在预期相关性。该数据集适用于非医疗、教育性的营养/健身应用,营养值为 AI 估计,不可作为医学依据。
The FitFuel Recipes dataset is a synthetically generated recipe dataset designed for the FitFuel project (AI Applications course at Reichman University). It contains 10,169 cleaned recipes generated via the Groq API (llama-3.1-8b-instant), validated using Pydantic schema with a fixed seed of 42. Each recipe includes the following fields: recipe name (recipe_name), ingredient list (ingredients), cooking instructions (instructions), AI-estimated nutritional values (calories, protein_g, carbs_g, fat_g), goal tag (goal_tag: bulking/cutting/maintenance), meal type (meal_type: breakfast/lunch/dinner/snack), difficulty (difficulty: beginner/intermediate/advanced), preparation time (prep_time_min), cuisine (cuisine), raw allergen tags (allergen_tags_model_raw, unreliable, for audit only), final deterministic allergen tags (allergen_tags_final, derived via regex from ingredients), dietary classifications (is_vegan, is_vegetarian, is_pescatarian, diet_tag, deterministically derived from ingredients), and nutritional consistency metrics (calories_implied, calorie_diff, calorie_diff_pct). The dataset also includes the source model (source_model). Known limitations include: only about 41% agreement between raw allergen tags and deterministic methods, about 80% of samples with calorie vs. macronutrient discrepancy exceeding 10 kcal, coverage gaps (27 out of 216 combinations of goal×meal_type×cuisine×difficulty have no recipes), and non-unique recipe names (about 95% unique). Domain logic checks show expected correlations between goal tags and calories, and between difficulty and prep time. The dataset is intended for non-medical, educational nutrition/fitness applications; nutritional values are AI estimates and should not be used as medical evidence.
FitFuel Recipes 数据集概述
基本信息
- 数据集名称:FitFuel Recipes
- 许可证:CC-BY-4.0
- 语言:英语
- 数据集规模:约 10,000-100,000 条(实际为 10,790 条食谱)
- 数据类型:合成数据(由 AI 生成)
- 标签:营养、食谱、合成数据、健身、嵌入向量、推荐系统、视觉语言模型、Gradio
- 作者:Daniel Halali 与 Amit Ben-Avraham,赖希曼大学数据科学导论课程(2026)
数据集内容
数据集包含 10,790 条由 Groq API(llama-3.1-8b-instant)生成的合成食谱,覆盖目标、餐食类型、菜系和难度的各种组合。
主要字段
| 字段名 | 描述 |
|---|---|
recipe_name |
食谱名称 |
ingredients |
食材列表 |
instructions |
烹饪说明 |
calories, protein_g, carbs_g, fat_g |
AI 估算的营养值 |
goal_tag |
健身目标(增肌/减脂/维持) |
meal_type |
餐食类型(早/午/晚/零食) |
difficulty |
难度(入门/中级/高级) |
prep_time_min |
预计准备时间(分钟) |
cuisine |
菜系类别 |
allergen_tags_model_raw |
LLM 生成的过敏原标签(不可靠,仅审计用) |
allergen_tags_final |
确定性的、基于正则表达式的过敏原标签(推荐使用) |
is_vegan, is_vegetarian, is_pescatarian, diet_tag |
确定性的饮食分类 |
calories_implied, calorie_diff, calorie_diff_pct |
宏量营养素推算热量与声明热量的差异 |
source_model |
生成该行的 LLM |
数据质量与验证
- 领域逻辑检查通过:
goal_tag与热量相关性符合预期(减脂 309 kcal < 维持 354 kcal < 增肌 518 kcal);难度与准备时间相关(入门 19.7 分钟 < 中级 22.0 分钟 < 高级 23.9 分钟) - 过敏原标签可靠性:LLM 自动生成的标签与确定性词表仅有约 41% 精确匹配,因此应用使用
allergen_tags_final - 热量一致性:约 80% 食谱的声明热量与宏量营养素推算热量偏差超过 10 kcal,属于 LLM 生成数据的预期噪声
- 组合覆盖:216 种(目标 × 餐食 × 菜系 × 难度)组合中有 27 种无食谱,推荐系统采用放宽单一条件作为回退机制
嵌入向量与推荐系统
- 嵌入模型:GTE-small(384 维),在三个模型基准测试中胜出(加载 9.6 秒、编码 3.6 秒、约 3,000 条/秒吞吐量、平均 top-3 相似度 0.86-0.92)
- 推荐流程:确定性过滤(过敏原/饮食/目标/餐食/时间/难度)→ GTE-small 查询编码 → 余弦相似度排序 → 输出 top-k 结果,并带有自动放宽约束的回退机制(过敏原/饮食约束永不放宽)
- 未使用 FAISS 的原因:10,790 条数据规模下,暴力余弦相似度(
np.dot)毫秒级完成,FAISS 在此规模无显著收益
视觉与生成模型
- 视觉模型:
HuggingFaceTB/SmolVLM-500M-Instruct,用于从冰箱/储藏室照片中自动识别食材 - 生成模型:
Qwen/Qwen2.5-0.5B-Instruct,用于生成食谱适配性说明(最多 20 词,避免医疗声明) - 视觉流程:模糊检测(Laplacian 方差)→ 食材提取 → 输出清洗(去重、规范化)→ 空结果回退 → 食材作为查询文本进入推荐引擎
数据文件
fitfuel_recipes_clean.parquet— 清洗后的食谱数据集(10,790 行)embeddings/fitfuel_embeddings_gte_small.npy— 预计算的 GTE-small 嵌入向量(384 维,已归一化)embeddings/fitfuel_embeddings_index.csv— 嵌入向量与食谱的行索引对齐文件images/— 所有 EDA 和第三部分图表 PNGFitFuel Final Project.ipynb— 完整项目笔记本(数据生成、EDA、嵌入)
已知局限
allergen_tags_model_raw不可靠,应始终使用allergen_tags_final- 热量/宏量营养素值存在噪声,应视为估算值
- 嵌入向量无法强制硬性饮食规则,须结合确定性过滤
- 食谱名称约 95% 唯一,重名可能对应不同食谱
- 小型视觉模型可能漏检冰箱/储藏室照片中不明显或被遮挡的食材
预期用途
该数据集用于构建和测试推荐系统、评估嵌入模型,以及探索合成数据生成,不作为经核实的营养数据库或专业饮食建议的替代品。