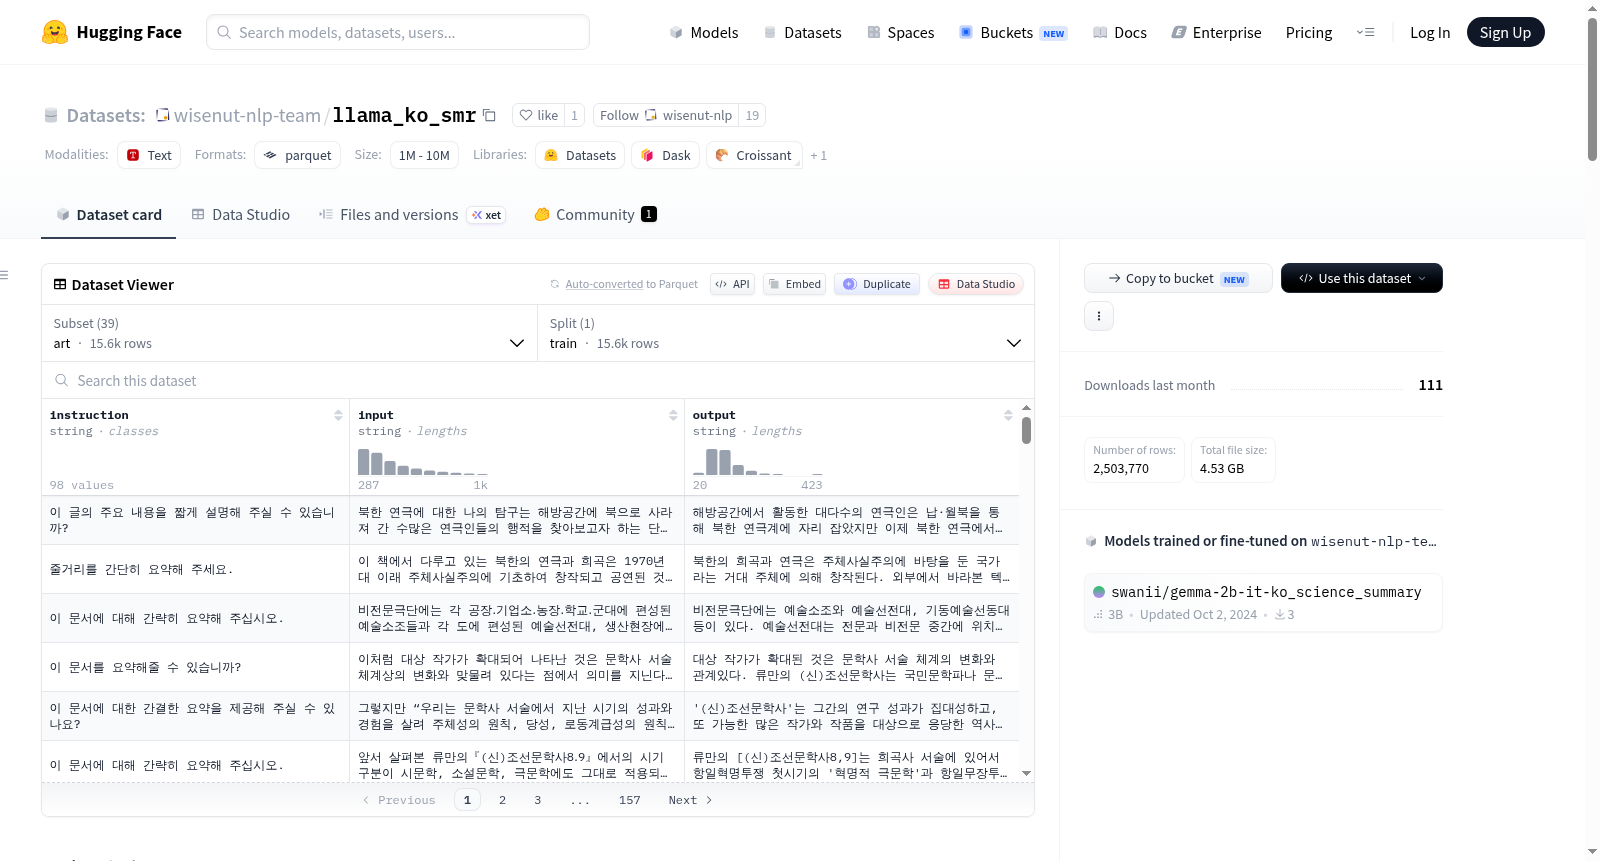
wisenut-nlp-team/llama_ko_smr
收藏资源简介:
--- dataset_info: - config_name: art features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 23253173 num_examples: 15627 download_size: 12801716 dataset_size: 23253173 - config_name: artifact_science features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 362643834 num_examples: 89531 download_size: 167429211 dataset_size: 362643834 - config_name: beauty_and_health features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 11495982 num_examples: 19203 download_size: 6174548 dataset_size: 11495982 - config_name: briefing features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string - name: tpye dtype: string splits: - name: train num_bytes: 84092000 num_examples: 36000 download_size: 26138279 dataset_size: 84092000 - config_name: c_event features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string - name: tpye dtype: string splits: - name: train num_bytes: 70105743 num_examples: 31166 download_size: 21295859 dataset_size: 70105743 - config_name: culture features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string - name: tpye dtype: string splits: - name: train num_bytes: 35908844 num_examples: 23700 download_size: 11289413 dataset_size: 35908844 - config_name: daily_and_occupation features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 14495402 num_examples: 22982 download_size: 7769431 dataset_size: 14495402 - config_name: edit features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string - name: tpye dtype: string splits: - name: train num_bytes: 41226597 num_examples: 18000 download_size: 13617131 dataset_size: 41226597 - config_name: editorial features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 204950743 num_examples: 63768 download_size: 117562937 dataset_size: 204950743 - config_name: education features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 8992532 num_examples: 14759 download_size: 4846739 dataset_size: 8992532 - config_name: enter features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string - name: tpye dtype: string splits: - name: train num_bytes: 77007245 num_examples: 36092 download_size: 24622632 dataset_size: 77007245 - config_name: etc features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 13009615 num_examples: 7597 download_size: 6696866 dataset_size: 13009615 - config_name: event features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 13632825 num_examples: 24006 download_size: 7160232 dataset_size: 13632825 - config_name: fm_drama features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string - name: tpye dtype: string splits: - name: train num_bytes: 65279567 num_examples: 36000 download_size: 20994133 dataset_size: 65279567 - config_name: food_and_drink features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 18831258 num_examples: 33957 download_size: 9768013 dataset_size: 18831258 - config_name: fs_drama features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string - name: tpye dtype: string splits: - name: train num_bytes: 62984894 num_examples: 36004 download_size: 20000234 dataset_size: 62984894 - config_name: his_cul features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string - name: tpye dtype: string splits: - name: train num_bytes: 30609601 num_examples: 18000 download_size: 10628675 dataset_size: 30609601 - config_name: history features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string - name: tpye dtype: string splits: - name: train num_bytes: 48220219 num_examples: 25766 download_size: 14665043 dataset_size: 48220219 - config_name: housing_and_living features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 29295812 num_examples: 50827 download_size: 15854030 dataset_size: 29295812 - config_name: law features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 59837947 num_examples: 27333 download_size: 29960383 dataset_size: 59837947 - config_name: leisure features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 23140399 num_examples: 39654 download_size: 12420477 dataset_size: 23140399 - config_name: life_science features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 35720463 num_examples: 7802 download_size: 17482630 dataset_size: 35720463 - config_name: literature features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string - name: tpye dtype: string splits: - name: train num_bytes: 51905166 num_examples: 21600 download_size: 18123605 dataset_size: 51905166 - config_name: minute features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string - name: tpye dtype: string splits: - name: train num_bytes: 149240389 num_examples: 61200 download_size: 41433544 dataset_size: 149240389 - config_name: narration features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string - name: tpye dtype: string splits: - name: train num_bytes: 24511774 num_examples: 18742 download_size: 7720190 dataset_size: 24511774 - config_name: nature_science features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 31775215 num_examples: 10862 download_size: 12939961 dataset_size: 31775215 - config_name: news_r features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string - name: tpye dtype: string splits: - name: train num_bytes: 161506493 num_examples: 48600 download_size: 52108494 dataset_size: 161506493 - config_name: newspaper features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 778034038 num_examples: 274105 download_size: 453662932 dataset_size: 778034038 - config_name: paper features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 669171434 num_examples: 324174 download_size: 354490940 dataset_size: 669171434 - config_name: paper2 features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string - name: tpye dtype: string splits: - name: train num_bytes: 40000149 num_examples: 18000 download_size: 13367455 dataset_size: 40000149 - config_name: patent features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 6932303601 num_examples: 312600 download_size: 2398178917 dataset_size: 6932303601 - config_name: patent_section features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 499358509 num_examples: 151000 download_size: 239316958 dataset_size: 499358509 - config_name: public features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string - name: tpye dtype: string splits: - name: train num_bytes: 40666888 num_examples: 18000 download_size: 12762114 dataset_size: 40666888 - config_name: relationships features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 45706612 num_examples: 80022 download_size: 24000637 dataset_size: 45706612 - config_name: shopping features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 17079513 num_examples: 29586 download_size: 9159776 dataset_size: 17079513 - config_name: social_science features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 186311981 num_examples: 129870 download_size: 96285745 dataset_size: 186311981 - config_name: speech features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string - name: tpye dtype: string splits: - name: train num_bytes: 162899290 num_examples: 72000 download_size: 48896868 dataset_size: 162899290 - config_name: technology_science features: - name: instruction dtype: string - name: input dtype: string - name: output dtype: string splits: - name: train num_bytes: 37930287 num_examples: 26907 download_size: 19950147 dataset_size: 37930287 - config_name: wisenut features: - name: instruction dtype: string - name: input dtype: string - name: title dtype: string - name: output dtype: string - name: lenght dtype: string splits: - name: train num_bytes: 440353415 num_examples: 228728 download_size: 145508702 dataset_size: 440353415 configs: - config_name: art data_files: - split: train path: art/train-* - config_name: artifact_science data_files: - split: train path: artifact_science/train-* - config_name: beauty_and_health data_files: - split: train path: beauty_and_health/train-* - config_name: briefing data_files: - split: train path: briefing/train-* - config_name: c_event data_files: - split: train path: c_event/train-* - config_name: culture data_files: - split: train path: culture/train-* - config_name: daily_and_occupation data_files: - split: train path: daily_and_occupation/train-* - config_name: edit data_files: - split: train path: edit/train-* - config_name: editorial data_files: - split: train path: editorial/train-* - config_name: education data_files: - split: train path: education/train-* - config_name: enter data_files: - split: train path: enter/train-* - config_name: etc data_files: - split: train path: etc/train-* - config_name: event data_files: - split: train path: event/train-* - config_name: fm_drama data_files: - split: train path: fm_drama/train-* - config_name: food_and_drink data_files: - split: train path: food_and_drink/train-* - config_name: fs_drama data_files: - split: train path: fs_drama/train-* - config_name: his_cul data_files: - split: train path: his_cul/train-* - config_name: history data_files: - split: train path: history/train-* - config_name: housing_and_living data_files: - split: train path: housing_and_living/train-* - config_name: law data_files: - split: train path: law/train-* - config_name: leisure data_files: - split: train path: leisure/train-* - config_name: life_science data_files: - split: train path: life_science/train-* - config_name: literature data_files: - split: train path: literature/train-* - config_name: minute data_files: - split: train path: minute/train-* - config_name: narration data_files: - split: train path: narration/train-* - config_name: nature_science data_files: - split: train path: nature_science/train-* - config_name: news_r data_files: - split: train path: news_r/train-* - config_name: newspaper data_files: - split: train path: newspaper/train-* - config_name: paper data_files: - split: train path: paper/train-* - config_name: paper2 data_files: - split: train path: paper2/train-* - config_name: patent data_files: - split: train path: patent/train-* - config_name: patent_section data_files: - split: train path: patent_section/train-* - config_name: public data_files: - split: train path: public/train-* - config_name: relationships data_files: - split: train path: relationships/train-* - config_name: shopping data_files: - split: train path: shopping/train-* - config_name: social_science data_files: - split: train path: social_science/train-* - config_name: speech data_files: - split: train path: speech/train-* - config_name: technology_science data_files: - split: train path: technology_science/train-* - config_name: wisenut data_files: - split: train path: wisenut/train-* --- ## [문서요약 텍스트](https://www.aihub.or.kr/aihubdata/data/view.do?currMenu=115&topMenu=100&aihubDataSe=data&dataSetSn=97) - subset: law - length: 27.3k - subset: newspaper - length: 274k - subset: editorial - length: 63.8k ## [도서자료 요약](https://www.aihub.or.kr/aihubdata/data/view.do?currMenu=115&topMenu=100&aihubDataSe=data&dataSetSn=93) * subset: art - length: 15.6k * subset: technology_science - length: 26.9k * subset: social_science - length: 130k * subset: etc - length: 7.6k ## [논문자료 요약](https://www.aihub.or.kr/aihubdata/data/view.do?currMenu=115&topMenu=100&aihubDataSe=data&dataSetSn=90) * subset: paper - length: 324k * subset: patent - length: 313k * subset: patent_section - length: 151k ## [방송 콘텐츠 대본 요약 데이터](https://www.aihub.or.kr/aihubdata/data/view.do?currMenu=115&topMenu=100&aihubDataSe=data&dataSetSn=591) * subset: fm_drama - length: 36k * subset: fs_drama - length: 36k * subset: history - length: 25.8k * subset: culture - length: 23.7k * subset: enter - length: 36k * subset: c_event - length: 31.1k ## [요약문 및 레포트 생성 데이터](https://www.aihub.or.kr/aihubdata/data/view.do?currMenu=115&topMenu=100&aihubDataSe=data&dataSetSn=582) * subset: news_r - length: 48.6k * subset: briefing - length: 36k * subset: his_cul - length: 18k * subset: paper2 - length: 18k * subset: minute - length: 61.2k * subset: edit - length: 18k * subset: public - length: 18k * subset: speech - length: 72k * subset: literature - length: 21.6k * subset: narration - length: 18.7k ## [한국어 대화 요약](https://www.aihub.or.kr/aihubdata/data/view.do?currMenu=115&topMenu=100&aihubDataSe=data&dataSetSn=117) * subset: relationships - length: 80k * subset: beauty_and_health - length: 19.2k * subset: shopping - length: 29.5k * subset: education - length: 14.7k * subset: food_and_drink - length: 33.9k * subset: leisure - length: 39.6k * subset: daily_and_occupation - length: 22.9k * subset: housing_and_living - length: 50.8k * subset: event - length: 24k ## [기술과학 요약 데이터](https://www.aihub.or.kr/aihubdata/data/view.do?currMenu=115&topMenu=100&aihubDataSe=data&dataSetSn=71532) * subset: life_science - length: 7.8k * subset: artifact_science - length: 89.5k * subset: nature_science - length: 10.8k
数据集概述
本数据集包含多个子集,每个子集针对不同的主题和领域,具有各自的特征和数据规模。以下是各子集的详细信息:
1. 艺术 (art)
- 特征: instruction, input, output
- 训练集: 15627个样本,总大小23253173字节
- 下载大小: 12801716字节
2. 文物科学 (artifact_science)
- 特征: instruction, input, output
- 训练集: 89531个样本,总大小362643834字节
- 下载大小: 167429211字节
3. 美容与健康 (beauty_and_health)
- 特征: instruction, input, output
- 训练集: 19203个样本,总大小11495982字节
- 下载大小: 6174548字节
4. 简报 (briefing)
- 特征: instruction, input, output, tpye
- 训练集: 36000个样本,总大小84092000字节
- 下载大小: 26138279字节
5. C事件 (c_event)
- 特征: instruction, input, output, tpye
- 训练集: 31166个样本,总大小70105743字节
- 下载大小: 21295859字节
6. 文化 (culture)
- 特征: instruction, input, output, tpye
- 训练集: 23700个样本,总大小35908844字节
- 下载大小: 11289413字节
7. 日常生活与职业 (daily_and_occupation)
- 特征: instruction, input, output
- 训练集: 22982个样本,总大小14495402字节
- 下载大小: 7769431字节
8. 编辑 (edit)
- 特征: instruction, input, output, tpye
- 训练集: 18000个样本,总大小41226597字节
- 下载大小: 13617131字节
9. 社论 (editorial)
- 特征: instruction, input, output
- 训练集: 63768个样本,总大小204950743字节
- 下载大小: 117562937字节
10. 教育 (education)
- 特征: instruction, input, output
- 训练集: 14759个样本,总大小8992532字节
- 下载大小: 4846739字节
11. 进入 (enter)
- 特征: instruction, input, output, tpye
- 训练集: 36092个样本,总大小77007245字节
- 下载大小: 24622632字节
12. 其他 (etc)
- 特征: instruction, input, output
- 训练集: 7597个样本,总大小13009615字节
- 下载大小: 6696866字节
13. 事件 (event)
- 特征: instruction, input, output
- 训练集: 24006个样本,总大小13632825字节
- 下载大小: 7160232字节
14. FM戏剧 (fm_drama)
- 特征: instruction, input, output, tpye
- 训练集: 36000个样本,总大小65279567字节
- 下载大小: 20994133字节
15. 食品与饮料 (food_and_drink)
- 特征: instruction, input, output
- 训练集: 33957个样本,总大小18831258字节
- 下载大小: 9768013字节
16. FS戏剧 (fs_drama)
- 特征: instruction, input, output, tpye
- 训练集: 36004个样本,总大小62984894字节
- 下载大小: 20000234字节
17. 历史与文化 (his_cul)
- 特征: instruction, input, output, tpye
- 训练集: 18000个样本,总大小30609601字节
- 下载大小: 10628675字节
18. 历史 (history)
- 特征: instruction, input, output, tpye
- 训练集: 25766个样本,总大小48220219字节
- 下载大小: 14665043字节
19. 住房与生活 (housing_and_living)
- 特征: instruction, input, output
- 训练集: 50827个样本,总大小29295812字节
- 下载大小: 15854030字节
20. 法律 (law)
- 特征: instruction, input, output
- 训练集: 27333个样本,总大小59837947字节
- 下载大小: 29960383字节
21. 休闲 (leisure)
- 特征: instruction, input, output
- 训练集: 39654个样本,总大小23140399字节
- 下载大小: 12420477字节
22. 生命科学 (life_science)
- 特征: instruction, input, output
- 训练集: 7802个样本,总大小35720463字节
- 下载大小: 17482630字节
23. 文学 (literature)
- 特征: instruction, input, output, tpye
- 训练集: 21600个样本,总大小51905166字节
- 下载大小: 18123605字节
24. 分钟 (minute)
- 特征: instruction, input, output, tpye
- 训练集: 61200个样本,总大小149240389字节
- 下载大小: 41433544字节
25. 叙述 (narration)
- 特征: instruction, input, output, tpye
- 训练集: 18742个样本,总大小24511774字节
- 下载大小: 7720190字节
26. 自然科学 (nature_science)
- 特征: instruction, input, output
- 训练集: 10862个样本,总大小31775215字节
- 下载大小: 12939961字节
27. 新闻R (news_r)
- 特征: instruction, input, output, tpye
- 训练集: 48600个样本,总大小161506493字节
- 下载大小: 52108494字节
28. 报纸 (newspaper)
- 特征: instruction, input, output
- 训练集: 274105个样本,总大小778034038字节
- 下载大小: 453662932字节
29. 论文 (paper)
- 特征: instruction, input, output
- 训练集: 324174个样本,总大小669171434字节
- 下载大小: 354490940字节
30. 论文2 (paper2)
- 特征: instruction, input, output, tpye
- 训练集: 18000个样本,总大小40000149字节
- 下载大小: 13367455字节
31. 专利 (patent)
- 特征: instruction, input, output
- 训练集: 312600个样本,总大小6932303601字节
- 下载大小: 2398178917字节
32. 专利部分 (patent_section)
- 特征: instruction, input, output
- 训练集: 151000个样本,总大小499358509字节
- 下载大小: 239316958字节
33. 公共 (public)
- 特征: instruction, input, output, tpye
- 训练集: 18000个样本,总大小40666888字节
- 下载大小: 12762114字节
34. 关系 (relationships)
- 特征: instruction, input, output
- 训练集: 80022个样本,总大小45706612字节
- 下载大小: 24000637字节
35. 购物 (shopping)
- 特征: instruction, input, output
- 训练集: 29586个样本,总大小17079513字节
- 下载大小: 9159776字节
36. 社会科学 (social_science)
- 特征: instruction, input, output
- 训练集: 129870个样本,总大小186311981字节
- 下载大小: 96285745字节
37. 演讲 (speech)
- 特征: instruction, input, output, tpye
- 训练集: 72000个样本,总大小162899290字节
- 下载大小: 48896868字节
38. 技术科学 (technology_science)
- 特征: instruction, input, output
- 训练集: 26907个样本,总大小37930287字节
- 下载大小: 19950147字节
39. Wisenut (wisenut)
- 特征: instruction, input, title, output, lenght
- 训练集: 228728个样本,总大小440353415字节
- 下载大小: 145508702字节
以上数据集提供了丰富的文本数据,适用于多种研究和应用场景。