autophagycode_D_mercury_Qwen3-4B_lr0.0001_c142_trust_t1_g2_run2
收藏资源简介:
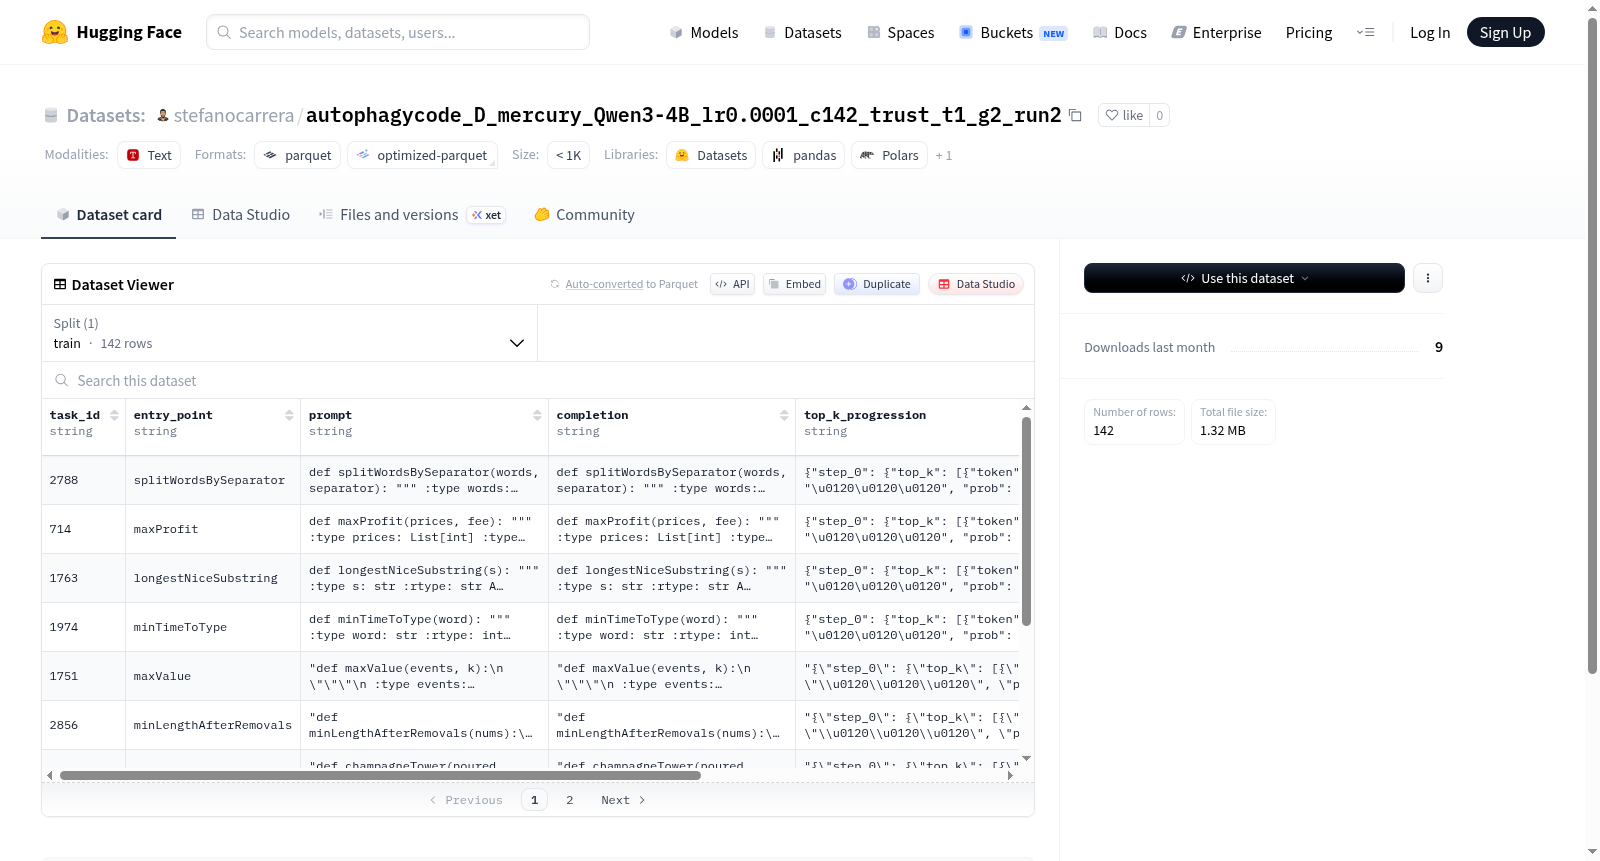
该数据集包含142个训练样本,每个样本由6个字符串类型字段组成:task_id(任务标识)、entry_point(入口点)、prompt(提示文本)、completion(完成文本)、top_k_progression(top_k进度)和test(测试内容)。数据集总大小为6.3MB,下载压缩包为1.3MB,以单一训练集形式组织,未提供验证集或测试集划分。从字段命名推测,该数据集可能用于代码生成或文本补全类任务,但具体应用场景需进一步分析字段内容以确认。
This dataset contains 142 training samples, each with 6 string-type fields: task_id, entry_point, prompt, completion, top_k_progression, and test. The total dataset size is 6.3MB, with a download compressed package of 1.3MB. It is organized as a single training set, without validation or test splits. Based on field naming, it may be intended for code generation or text completion tasks, but the specific application scenario requires further confirmation by analyzing the field content.
根据您提供的README文件,该数据集详情总结如下:
数据集概述
- 数据集名称:autophagycode_D_mercury_Qwen3-4B_lr0.0001_c142_trust_t1_g2_run2
- 数据集来源:Hugging Face Datasets(链接:https://huggingface.co/datasets/stefanocarrera/autophagycode_D_mercury_Qwen3-4B_lr0.0001_c142_trust_t1_g2_run2)
数据特征
该数据集包含以下字段(均为字符串类型):
- task_id:任务标识符
- entry_point:入口点(函数/代码入口)
- prompt:提示文本
- completion:补全文本(生成的代码或答案)
- top_k_progression:top-k 进度信息
- test:测试部分
数据划分
- 训练集(train):共142个样本,占用存储约6.26 MB。
- 无其他划分(如验证集或测试集)。
数据集大小
- 下载大小:约1.32 MB
- 数据集总大小:约6.26 MB
配置文件
- 默认配置(default):训练数据文件路径为
data/train-*(分片文件,位于数据集根目录下的data文件夹内)。