ParaVT-Parquet
收藏资源简介:
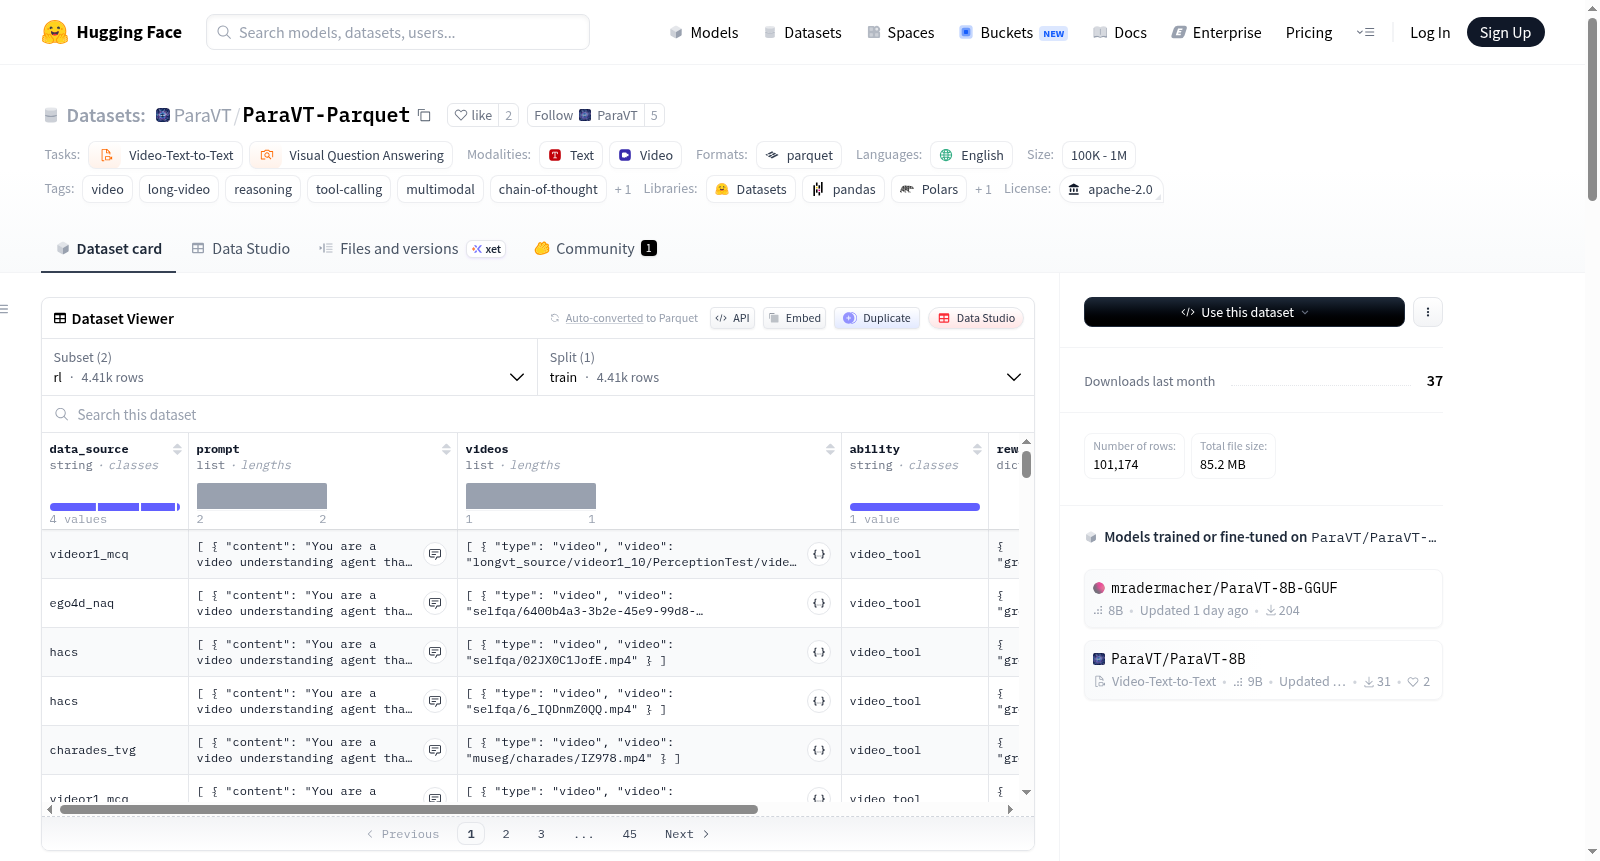
ParaVT-Parquet数据集是ParaVT项目的训练标注集合,ParaVT是一个采用PARSEABILITY-ANCHORED AND RATIO-GATED GRPO(PARA-GRPO)方法进行后训练的多智能体框架,专注于长视频理解。该数据集用于训练ParaVT/ParaVT-8B模型及其冷启动初始化模型,包含两个主要配置:1)监督微调(SFT)配置,总计约97,000行数据,汇集了来自七个不同来源的数据,支持多种任务,如Charades-STA的时间定位、Gemini蒸馏的工具调用链、长视频推理、MuSeG并行工具调用、自蒸馏的交错多模态工具思维链、时序视频定位以及Video-R1子集;2)强化学习(RL)配置,包含4,406行数据,混合了来自四个数据源(如videor1_mcq、hacs开放式问答、charades_tvg、ego4d_naq开放式问答)的样本,并设计了多种奖励形式(如多项选择题精确匹配、开放式问答F1分数、时序交并比),格式与AReaL训练栈兼容。数据集以Parquet文件格式提供,属于多模态数据集,涉及视频和文本,任务类别包括视频文本到文本和视觉问答。为保护隐私,数据文件中的媒体文件绝对路径已被替换为基于虚拟根目录的相对哨兵路径,需使用配套工具还原后才能正常使用,源媒体文件存储于独立的ParaVT/ParaVT-Source仓库。
The ParaVT-Parquet dataset is a training annotation collection for the ParaVT project, which is a multi-agent framework focusing on long video understanding using the PARSEABILITY-ANCHORED AND RATIO-GATED GRPO (PARA-GRPO) method for post-training. It serves as the precise corpus for training the ParaVT/ParaVT-8B models and their cold-start initialization models. The dataset includes two main configurations: 1) Supervised Fine-tuning (SFT) configuration, with approximately 97,000 rows of data aggregated from seven different sources for various tasks, including temporal localization in Charades-STA, tool call chains from Gemini distillation, long video reasoning, parallel tool calls from MuSeG, interleaved multimodal tool chains of thought from self-distillation, temporal video grounding, and the Video-R1 subset; 2) Reinforcement Learning (RL) configuration, containing 4,406 rows of data mixed from four data sources (videor1_mcq, hacs open-ended QA, charades_tvg, ego4d_naq open-ended QA), with various reward designs (e.g., multiple-choice exact match, open-ended QA F1 score, temporal IoU), and its format is compatible with the AReaL training stack. The dataset is provided in Parquet format, is multimodal involving video and text, and covers task categories such as video text-to-text and visual question answering. For privacy protection, absolute paths to media files in the data files have been replaced with relative sentinel paths based on a specific virtual root directory, requiring restoration with accompanying tools for normal use, and the source media files are stored in a separate ParaVT/ParaVT-Source repository.
ParaVT-Parquet 数据集概述
基本信息
- 许可证: Apache-2.0
- 任务类型: 视频-文本到文本、视觉问答
- 语言: 英语
- 数据规模: 100K < 样本数 < 1M
- 标签: 视频、长视频、推理、工具调用、多模态、思维链、智能体强化学习
数据集描述
ParaVT-Parquet 是 ParaVT 项目的训练注释数据集,用于长视频理解的多智能体智能体框架,通过 PARA-GRPO 方法进行后训练。该数据集是训练 ParaVT/ParaVT-8B 及其冷启动初始化模型 mwxely/ParaVT-8B-SFT 所使用的精确训练语料。
数据集结构
sft 配置(冷启动训练,共 97,000 行)
| 子集 | 行数 | 来源 |
|---|---|---|
charades |
12,408 | Charades-STA 时间定位 |
geminicot |
4,881 | Gemini 蒸馏的工具调用链 |
longvideoreason |
5,238 | 长视频推理 |
museg |
2,499 | MuSeG 并行工具调用 |
selftrace |
15,349 | 自蒸馏的交错多模态工具链思维 |
tvg |
6,393 | 时间视频定位 |
videor1 |
50,000 | Video-R1 子集 |
rl 配置(强化学习,共 4,406 行)
| 项目 | 说明 |
|---|---|
| 数据来源混合 | videor1_mcq(1,600)+ hacs 开放式问答(1,439)+ charades_tvg(1,200)+ ego4d_naq 开放式问答(167) |
| 奖励形式 | 多选题精确匹配、开放式 F1 分数、时间 IoU |
| 数据格式 | prompt / videos / reward_model / extra_info(兼容 AReaL 训练框架) |
文件路径处理
出于隐私考虑,Parquet 文件中的绝对媒体路径已被替换为相对"哨兵"路径,映射到四个虚拟根目录:
| 哨兵前缀 | 映射路径(ParaVT-Source/<sentinel>/ 下) |
|---|---|
longvt_source/ |
每个来源的长视频训练视频存档(videor1_*、longvideoreason_*、geminicot_*、tvg_*、selftrace_*) |
museg/charades/ |
用于时间定位训练的 Charades-STA 片段 |
museg/et_instruct_164k/ |
MuSeG et_instruct_164k 片段 |
selfqa/ |
自行策划的开放式问答片段(混合 HACS 和 Ego4D 衍生) |
可通过 paravt.data.materialize 将哨兵路径还原为绝对路径。
致谢
- SFT 语料复用了 LongVT 训练数据的子集(来源:
longvideotool/LongVT-Parquet) - MuSeG、Charades-STA、HACS 和 Ego4D 的源片段归属于其各自的原始出版物