hezarai/parsynth-ocr-4m
收藏资源简介:
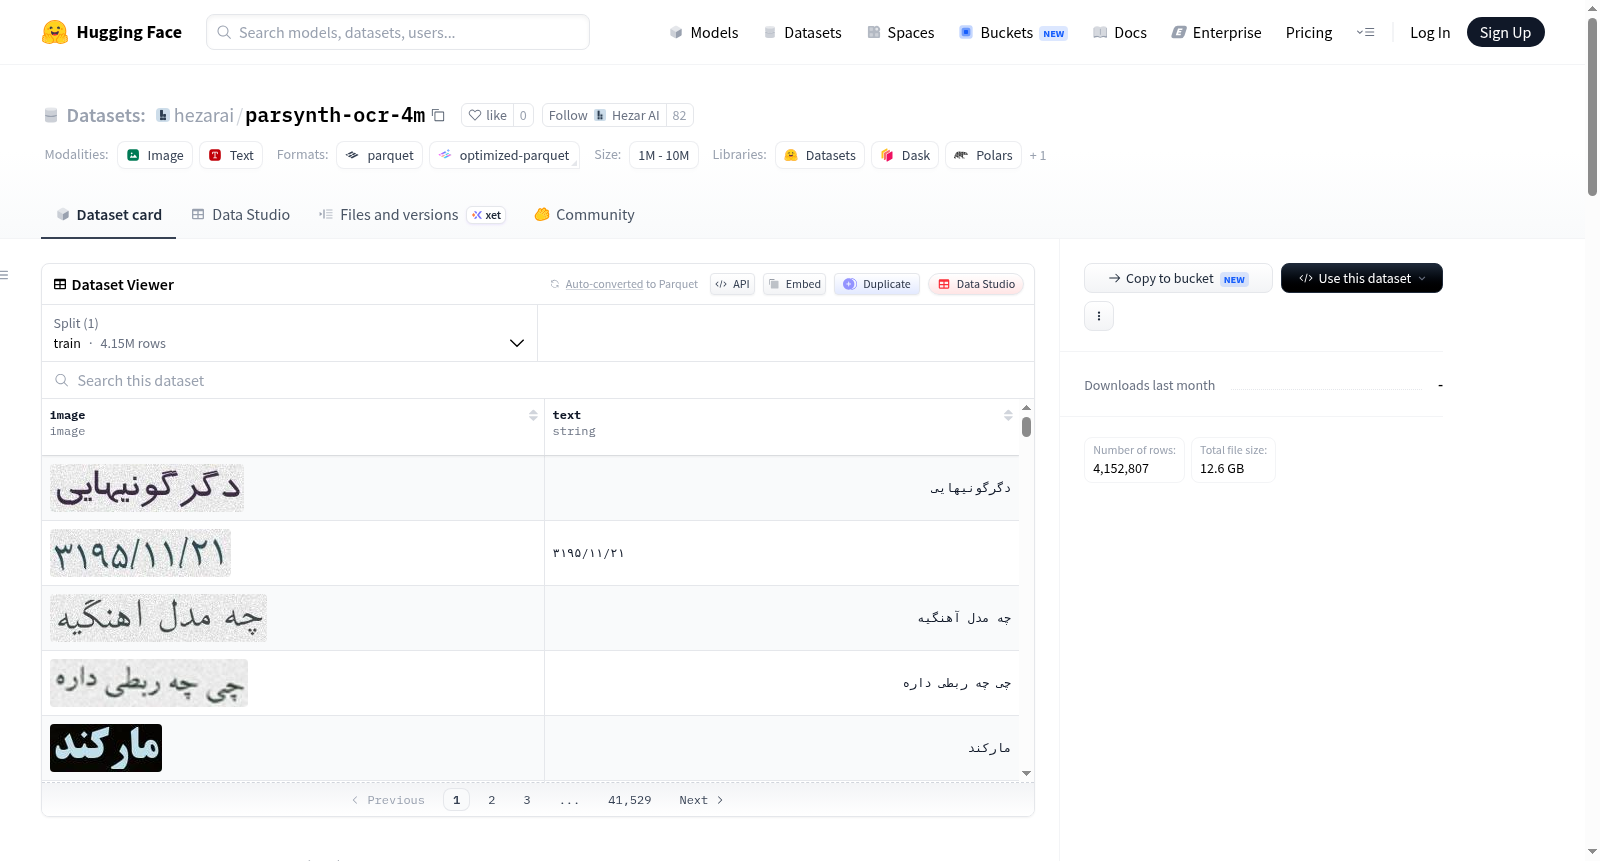
该数据集包含400万个合成的波斯语文本行图像,使用基于TextRecognitionDataGenerator(trdg)的定制波斯语分支生成。它专为训练高性能的波斯语光学字符识别(OCR)和文本识别模型而设计,是Hezar AI官方波斯语OCR模型(如hezarai/crnn-base-fa-v2和hezarai/crnn-fa-license-plate-recognition-v2)的基础预训练数据集。数据集分为三个分区:高斯噪声背景(300万样本)、浅色文档背景(100万样本)和深色文档背景(100万样本),每个分区具有不同的文本颜色、背景纹理和质量退化,以增强模型多样性。文本来源自hezarai/lscp-pos-500k词典语料库,生成工具为hezarai/trdg-persian,支持波斯语从右到左渲染、连字保留和分词处理。主要用途包括波斯语OCR模型的预训练或微调(如CRNN、TrOCR、Donut等),以及下游任务(如车牌识别、文档扫描)的微调。
This dataset contains 4,000,000 synthetic Persian text line images generated using a customized Persian fork of TextRecognitionDataGenerator (trdg). It is designed specifically for training high-performance optical character recognition (OCR) and text recognition models for Persian text. This dataset served as the foundational pre-training dataset for the official Hezar AI Persian OCR models, including hezarai/crnn-base-fa-v2 and hezarai/crnn-fa-license-plate-recognition-v2. The dataset consists of three distinct partitions: Gaussian noise backgrounds (3M samples), light document backgrounds (1M samples), and dark document backgrounds (1M samples), each with varying text colors, background textures, and quality degradations to expose OCR models to diverse conditions. The text is sampled from the hezarai/lscp-pos-500k dictionary corpus, and the generation tool is hezarai/trdg-persian, featuring custom RTL fixes, ligature preservation, and word-split handling. The primary use case is pre-training or fine-tuning OCR models (e.g., CRNN, TrOCR, Donut) for general Persian text and downstream fine-tuning (e.g., license plates, document scanning).
数据集概述
- 数据集名称: Synthetic Persian OCR Dataset (4M)
- 数据集规模: 4,000,000 张合成波斯语文本行图像
- 语言: 波斯语 (
fa) - 文本来源: 从
hezarai/lscp-pos-500k词典语料库中直接采样 - 生成工具:
hezarai/trdg-persian(包含自定义 RTL 修复、连字保留和分词处理) - 主要用途: 用于预训练或微调 OCR 模型(如 CRNN、TrOCR、Donut 等),适用于通用波斯语文本识别及下流任务微调(如车牌识别、文档扫描)
数据集分区详情
数据集包含三个不同的分区,旨在让 OCR 模型接触多样化的文本颜色、背景纹理和质量退化:
| 分区 | 样本数量 | 索引范围 | 背景类型 | 文本颜色调色板 | 质量退化 |
|---|---|---|---|---|---|
| 分区 1(高斯噪声) | 3,000,000 | 0 – 2,999,999 |
高斯噪声 (-b 0) |
深色调 (#284854, #542828) |
50% 降采样,20% 应用 (-rqf 0.5 -rqp 0.2) |
| 分区 2(浅色文档) | 1,000,000 | 3,000,000 – 3,999,999 |
浅色文档背景 (-b 3) |
深色调 (#284854, #542828) |
标准质量 |
| 分区 3(深色文档) | 1,000,000 | 4,000,000 – 4,999,999 |
深色文档背景 (-b 3) |
柔和粉彩色调 (#ed8c8c, #8ceced) |
50% 降采样,20% 应用 (-rqf 0.5 -rqp 0.2) |
数据格式
- 模态: 图像、文本
- 文件格式: parquet, optimized-parquet
- 数据集行数: 4,152,807 行
- 总文件大小: 12.6 GB
基于该数据集的预训练模型
该数据集已被用于训练以下模型:
- 通用波斯语 OCR:
hezarai/crnn-base-fa-v2hezarai/crnn-base-fa-v1
- 专用微调模型:
hezarai/crnn-fa-license-plate-recognition-v2hezarai/crnn-fa-license-plate-recognition-v1
数据集主页
- 地址: https://hf-mirror.com/datasets/hezarai/parsynth-ocr-4m