german-dynaword
收藏资源简介:
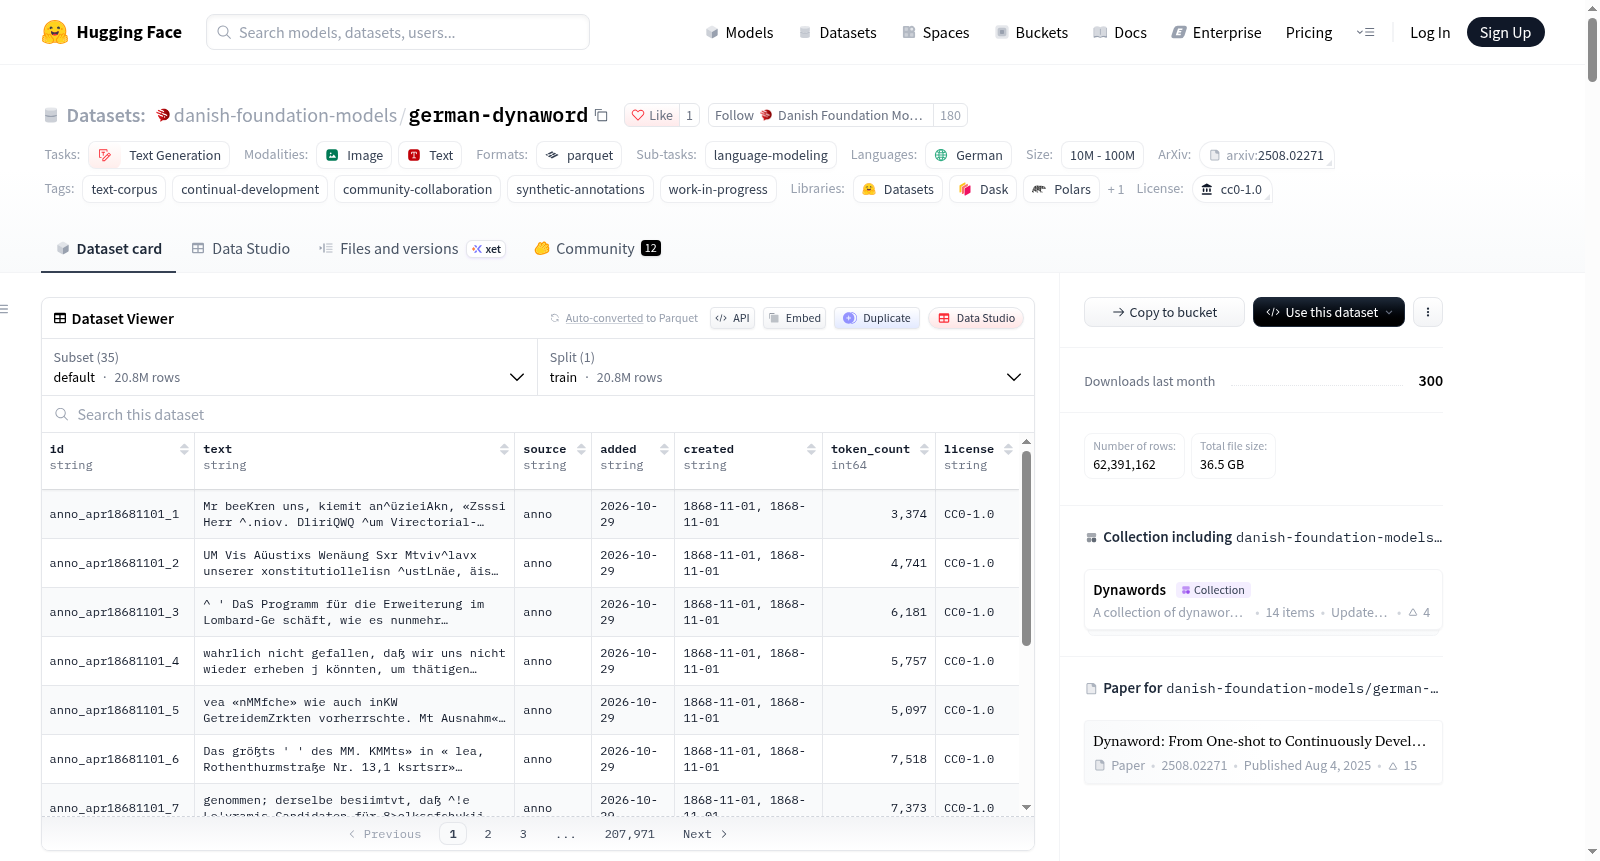
German Dynaword(Hugging Face 数据集 id:danish-foundation-models/german-dynaword)是一个持续开发中的德语自由文本数据集集合,汇集来自多个领域的公开许可文本,旨在为大规模语言模型训练提供可用语料。数据集状态为 work in progress,当前版本为 0.0.6;来源仍在增加,因此样本量、统计信息和图表会随版本变化。README 说明目前没有在该数据集上训练的模型,用户可通过讨论区 issue 联系。所有纳入的数据集均为开放许可,并被认为可用于训练大规模语言模型。YAML 元数据标明 annotations_creators 为 machine-generated,language_creators 为 found,source_datasets 为 original,multilinguality 为 monolingual。规模与语言:当前包含约 20.80M 个样本,约 18.34B 个 Llama 3 token;平均文档长度为 881.79 token,最短 5 token,最长 2.92M token。主要语言为德语(de / deu-Latn),属于单语数据集,但可能在引用、法律引文和嵌入参考中包含少量英语及其他语言。语言标签使用 BCP-47,并基于 ISO 639-3 和 ISO 15924。构成与领域:数据覆盖新闻、书籍、百科、法律、演讲、社交媒体、口语、报告及其他等域。新闻 6.74B token,书籍 4.11B,百科 2.38B,法律 2.36B,演讲 1.18B,社交媒体 1.03B,口语 250.63M,其他 146.41M,报告 139.73M,总计 18.34B。来源包括 gutenberg、wikipedia、wikidiscussions、wikisource、wikivoyage、wikiquote、wikibooks、wikiversity、wikinews、openlegaldata、plenarprotokolle、drucksachen、germanpoliticalspeeches、mosel、sbbfulltexts、eurlex、onemillionposts、tedeutenders、blbooks、dibilit、dibiphil、polyjournal、bverfgaes、bundesrecht、bag、bfh、bgh、bgh_strafsachen、bpatg、bverfg、bverwg、anno、reichstagsprotokolle。配置包括 default(data/*/data.parquet)、meta(metadata.parquet)以及每个来源单独的配置(如 bundesrecht),均按 train split 提供。可通过 datasets.load_dataset 加载完整数据集、流式加载或单独加载子集;meta 配置提供注释,便于过滤;可通过 revision 固定版本,以获得一致的版本。注释与元数据:每个文档带有机器生成的注释,描述内容质量、信息密度和教育价值等维度。注释级别从 worst 到 best 的分布图见各来源 datasheet,计数存于 descriptive_stats.json 的 annotations。部分来源存在 null annotations,原因是 German Commons id 在集合中不唯一且注释发布版没有 source 列,按 id 连接可能错误关联其他文档的注释;这些来源将在后续批次中基于文本重新注释。许可:数据集卡顶层 license 字段为 cc0-1.0;README 正文进一步说明 CC-0 适用于集合层面的元数据、质量控制等,组成文本遵循各来源的许可,使用时应查看各来源。README 仅接受允许再分发和训练使用的来源,实际包括 CC0、CC-BY、CC-BY-SA;不明确、非商业、无法遵守的 copyleft 或仅定制协议来源会被排除。每个文档按来源记录的许可证检查。按 token 统计:CC-0 10.46B,CC-BY-SA 4.0 4.59B,CC-BY 4.0 3.08B,其他需署名 198.60M,总计 18.34B。任务类别为 text-generation / language-modeling,标签包括 text-corpus、continual-development、community-collaboration、synthetic-annotations、work-in-progress。
German Dynaword (Hugging Face dataset id: danish-foundation-models/german-dynaword) is an ongoing collection of German free-text datasets, gathering publicly licensed texts from multiple domains to provide usable corpus for large-scale language model training. Its status is work in progress, current version 0.0.6; sources are still being added, so sample counts, statistics, and charts change across versions. The README states that no models have currently been trained on this dataset, and users can contact via the discussion issue. All included datasets are openly licensed and considered usable for large-scale language model training. YAML metadata indicates annotations_creators is machine-generated, language_creators is found, source_datasets is original, and multilinguality is monolingual. Scale and language: currently about 20.80M samples and about 18.34B Llama 3 tokens; average document length is 881.79 tokens, minimum 5 tokens, maximum 2.92M tokens. Main language is German (de / deu-Latn), a monolingual dataset, but it may contain small amounts of English and other languages in quotations, legal citations, and embedded references. Language tags use BCP-47, based on ISO 639-3 and ISO 15924. Composition and domains: covers news, books, encyclopedia, legal, speeches, social media, spoken, reports, and other domains. News 6.74B tokens, books 4.11B, encyclopedia 2.38B, legal 2.36B, speeches 1.18B, social media 1.03B, spoken 250.63M, other 146.41M, reports 139.73M, total 18.34B. Sources include gutenberg, wikipedia, wikidiscussions, wikisource, wikivoyage, wikiquote, wikibooks, wikiversity, wikinews, openlegaldata, plenarprotokolle, drucksachen, germanpoliticalspeeches, mosel, sbbfulltexts, eurlex, onemillionposts, tedeutenders, blbooks, dibilit, dibiphil, polyjournal, bverfgaes, bundesrecht, bag, bfh, bgh, bgh_strafsachen, bpatg, bverfg, bverwg, anno, reichstagsprotokolle. Configurations include default (data/*/data.parquet), meta (metadata.parquet), and individual configurations per source (such as bundesrecht), all provided under the train split. The full dataset, streaming loading, or individual subsets can be loaded via datasets.load_dataset; the meta configuration provides annotations for filtering; revisions can pin versions for consistency. Annotations and metadata: each document has machine-generated annotations describing dimensions such as content quality, information density, and educational value. Distribution charts of annotation levels from worst to best are in each source datasheet, and counts are stored in annotations in descriptive_stats.json. Some sources have null annotations because the German Commons id is not unique in the collection and the annotation release has no source column, so joining by id may incorrectly associate annotations from other documents; these sources will be re-annotated based on text in later batches. License: the top-level license field of the dataset card is cc0-1.0; the README body further explains that CC-0 applies to collection-level metadata, quality control, etc., while constituent texts follow their source licenses, which should be checked when using. The README only accepts sources that allow redistribution and training use, actually including CC0, CC-BY, and CC-BY-SA; unclear, non-commercial, uncompliable copyleft, or custom-only-license sources are excluded. Each document is checked against the license recorded by source. By token: CC-0 10.46B, CC-BY-SA 4.0 4.59B, CC-BY 4.0 3.08B, other attribution-required 198.60M, total 18.34B. Task categories are text-generation / language-modeling, tags include text-corpus, continual-development, community-collaboration, synthetic-annotations, work-in-progress.
German Dynaword 数据集总结
1. 基本信息
- 数据集地址:https://huggingface.co/datasets/danish-foundation-models/german-dynaword
- 状态:🚧 Work in progress
- 版本:0.0.6
- Changelog:https://huggingface.co/datasets/danish-foundation-models/german-dynaword/CHANGELOG.md
- 语言:German(de, deu)
- 许可:Openly Licensed, See the respective dataset
- 当前模型:Currently there are no models trained on this dataset
- 联系:如有问题,可在 https://huggingface.co/datasets/danish-foundation-models/german-dynaword/discussions 创建 issue
- 样本数:20.80M
- Token 数(Llama 3):18.34B
- 平均文档长度(tokens):881.79
- 最小文档长度(tokens):5
- 最大文档长度(tokens):2.92M
2. YAML 元数据
- annotations_creators:machine-generated
- language_creators:found
- language:de
- license:cc0-1.0
- multilinguality:monolingual
- source_datasets:original
- task_categories:text-generation
- task_ids:language-modeling
- tags:text-corpus, continual-development, community-collaboration, synthetic-annotations, work-in-progress
- pretty_name:German Dynaword
- language_bcp47:deu-Latn
3. 数据集描述
German Dynaword 是德语自由形式文本数据集集合,来自多个领域。所有数据集均为开放许可,并被认为允许用于训练大型语言模型。
该语料库仍在开发中,来源仍在添加,因此大小、统计信息和图表会随版本变化。German Dynaword 持续开发,会在新数据集可用时主动更新。
4. 语言
- 主要语言:German(deu-Latn)
- 可能包含少量英语及其他语言,出现在引用、法律引用和嵌入参考文献中。
- 语言标注使用 BCP-47,语言代码来自 ISO 639-3,脚本代码来自 ISO 15924。
5. 配置与数据划分
所有配置均提供 train split。
配置包括:
- default
- meta
- gutenberg
- wikipedia
- wikidiscussions
- wikisource
- wikivoyage
- wikiquote
- wikibooks
- wikiversity
- wikinews
- openlegaldata
- plenarprotokolle
- drucksachen
- germanpoliticalspeeches
- mosel
- sbbfulltexts
- eurlex
- onemillionposts
- tedeutenders
- blbooks
- dibilit
- dibiphil
- polyjournal
- bverfgaes
- bundesrecht
- bag
- bfh
- bgh
- bgh_strafsachen
- bpatg
- bverfg
- bverwg
- anno
- reichstagsprotokolle
default 配置聚合各来源数据;meta 配置聚合各来源元数据;各子集配置使用对应来源数据。meta 配置提供 extensive annotations,可用于过滤。
6. 领域分布
| Domain | Sources | N. Tokens |
|---|---|---|
| News | wikinews, anno | 6.74B |
| Books | gutenberg, wikisource, wikibooks, sbbfulltexts, blbooks, dibilit, dibiphil | 4.11B |
| Encyclopedic | wikipedia | 2.38B |
| Legal | openlegaldata, eurlex, bverfgaes, bundesrecht, bag, bfh, bgh, bgh_strafsachen, bpatg, bverfg, bverwg | 2.36B |
| Speeches | plenarprotokolle, drucksachen, germanpoliticalspeeches, reichstagsprotokolle | 1.18B |
| Social Media | wikidiscussions, onemillionposts | 1.03B |
| Spoken | mosel | 250.63M |
| Other | wikivoyage, wikiquote, wikiversity, tedeutenders | 146.41M |
| Report | polyjournal | 139.73M |
| Total | 18.34B |
7. 许可
- 集合的元数据、质量控制等部分使用 CC-0 许可。
- 构成数据文本使用各自数据集许可。
- 仅接受允许再分发和用于训练的源。实践中包括 CC0、CC-BY 和 CC-BY-SA 源。
- 许可不清晰、非商业许可、无法遵守的 copyleft 许可,或仅通过定制协议提供的源不纳入。
- 每个文档按源记录的许可检查,而不仅按集合整体许可检查。
| License | Sources | N. Tokens |
|---|---|---|
| CC-0 | openlegaldata, plenarprotokolle, drucksachen, tedeutenders, blbooks, bverfgaes, bundesrecht, bag, bfh, bgh, bgh_strafsachen, bpatg, bverfg, bverwg, anno | 10.46B |
| CC-BY-SA 4.0 | wikipedia, wikidiscussions, wikisource, wikivoyage, wikiquote, wikibooks, wikiversity, wikinews, dibilit, dibiphil, polyjournal, reichstagsprotokolle | 4.59B |
| CC-BY 4.0 | germanpoliticalspeeches, mosel, sbbfulltexts, eurlex, onemillionposts | 3.08B |
| Other(Attribution required) | gutenberg | 198.60M |
| Total | 18.34B |
8. 标注
- 每个文档都带有标注,描述其内容特征,例如内容质量、信息密度和教育价值。
- 每个条形显示某一标注在各等级上的文档占比,从 worst(浅色)到 best(深色)。
- 每个来源的 datasheet 中都有相同类型的图,计数存储于 descriptive_stats.json 的 annotations 下。
- meta 配置提供 annotations,可用于过滤。
- 部分来源包含 null annotations:其 German Commons ids 在整个集合中不唯一,且 annotation release 没有 source 列,因此仅按 id 连接会将另一文档的标注附加过来。这些来源会在后续批次中基于其文本进行标注,其卡片会在 Limitations 下说明。
9. 加载方式
py from datasets import load_dataset
name = "danish-foundation-models/german-dynaword" ds = load_dataset(name, split="train") sample = ds[0]
流式加载: py ds = load_dataset(name, split="train", streaming=True) sample = next(iter(ds))
加载单个子集: py ds = load_dataset(name, "bundesrecht", split="train")
加载 meta 配置以使用标注: py meta = load_dataset(name, "meta", split="train")
指定 revision 以获取每次相同的版本: py ds = load_dataset(name, revision="{desired revision}")
10. 贡献与更新
- German Dynaword 持续扩展和策展,支持社区贡献数据集。
- 如需贡献数据集,可参考 contribute section。
- 如需获取每次相同的版本,可指定 revision。