ghananlpcommunity/pristine-twi-english-parallel-sentences
收藏资源简介:
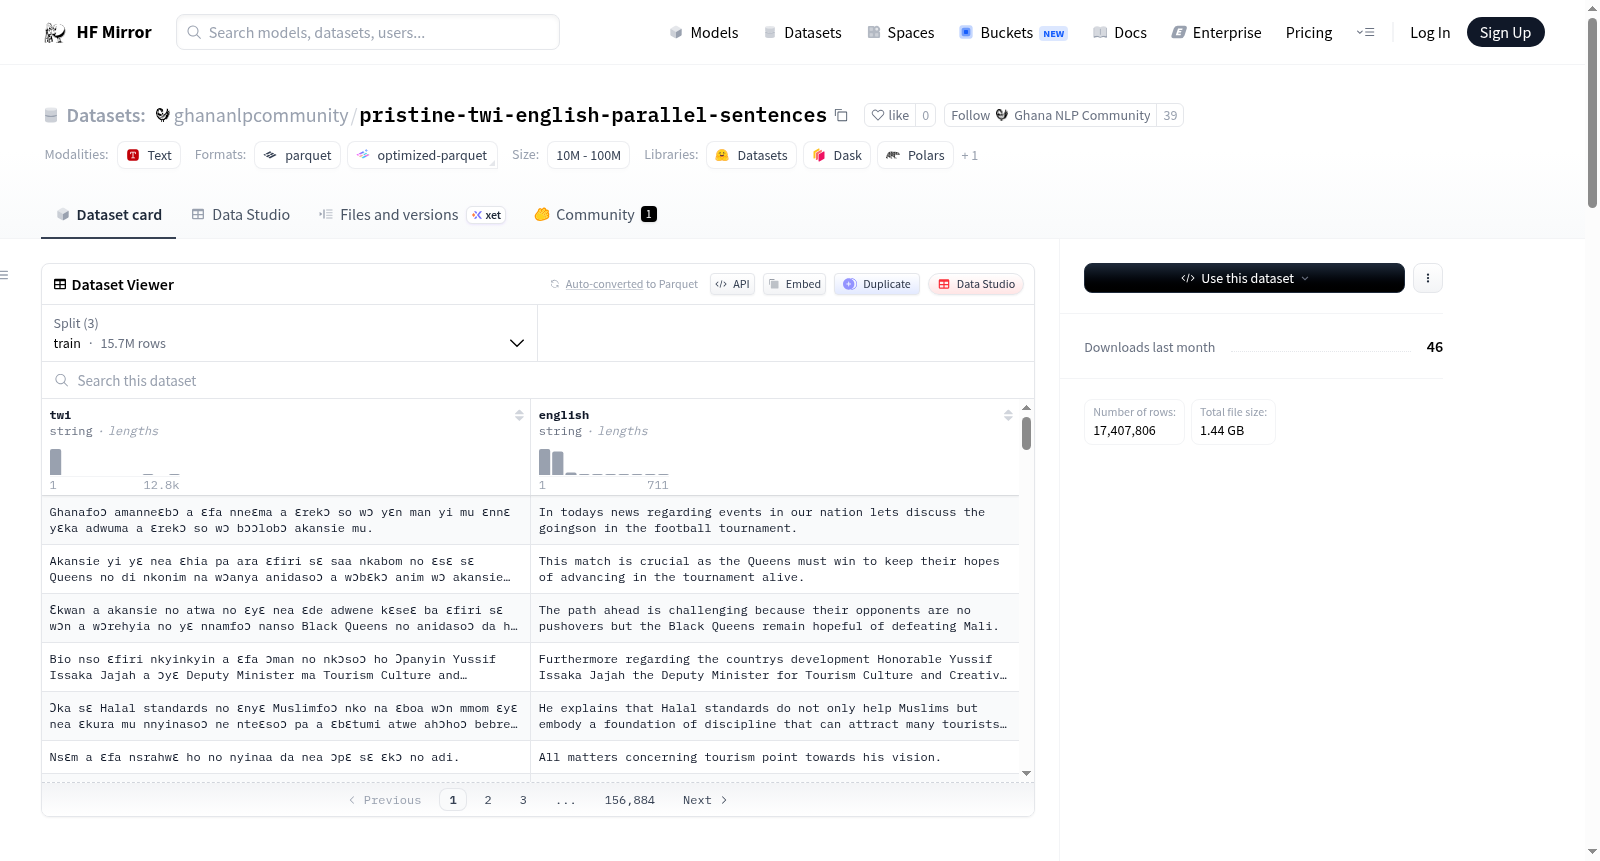
Pristine Twi–English Parallel Sentences Dataset是一个大规模的、句子级别的、去重的Twi ↔ 英语平行数据集,专门用于训练最先进的机器翻译模型。该数据集来源于Ghana NLP Community的原始数据集,并经过严格的句子分割、对齐过滤、标准化、全局去重和数据分割等处理步骤。数据集的结构包括Twi和英语的句子对,用于机器翻译、跨语言对齐和大型语言模型预训练等任务。数据集的局限性包括翻译的合成来源、领域限制和方言代表性不足等问题。
The Pristine Twi–English Parallel Sentences Dataset is a massive, sentence-level, deduplicated Twi ↔ English parallel dataset optimized specifically for training State-of-the-Art (SOTA) Machine Translation models. This dataset is derived from the original dataset by the Ghana NLP Community and has been meticulously processed through sentence splitting, strict alignment filtering, standardization, global deduplication, and data splitting. The dataset structure includes Twi and English sentence pairs intended for machine translation, cross-lingual alignment, and large language model pre-training. Limitations include the synthetic origin of translations, domain constraints, and under-representation of dialectal variations.