FreekCoolAI/kvk-pii-checker
收藏资源简介:
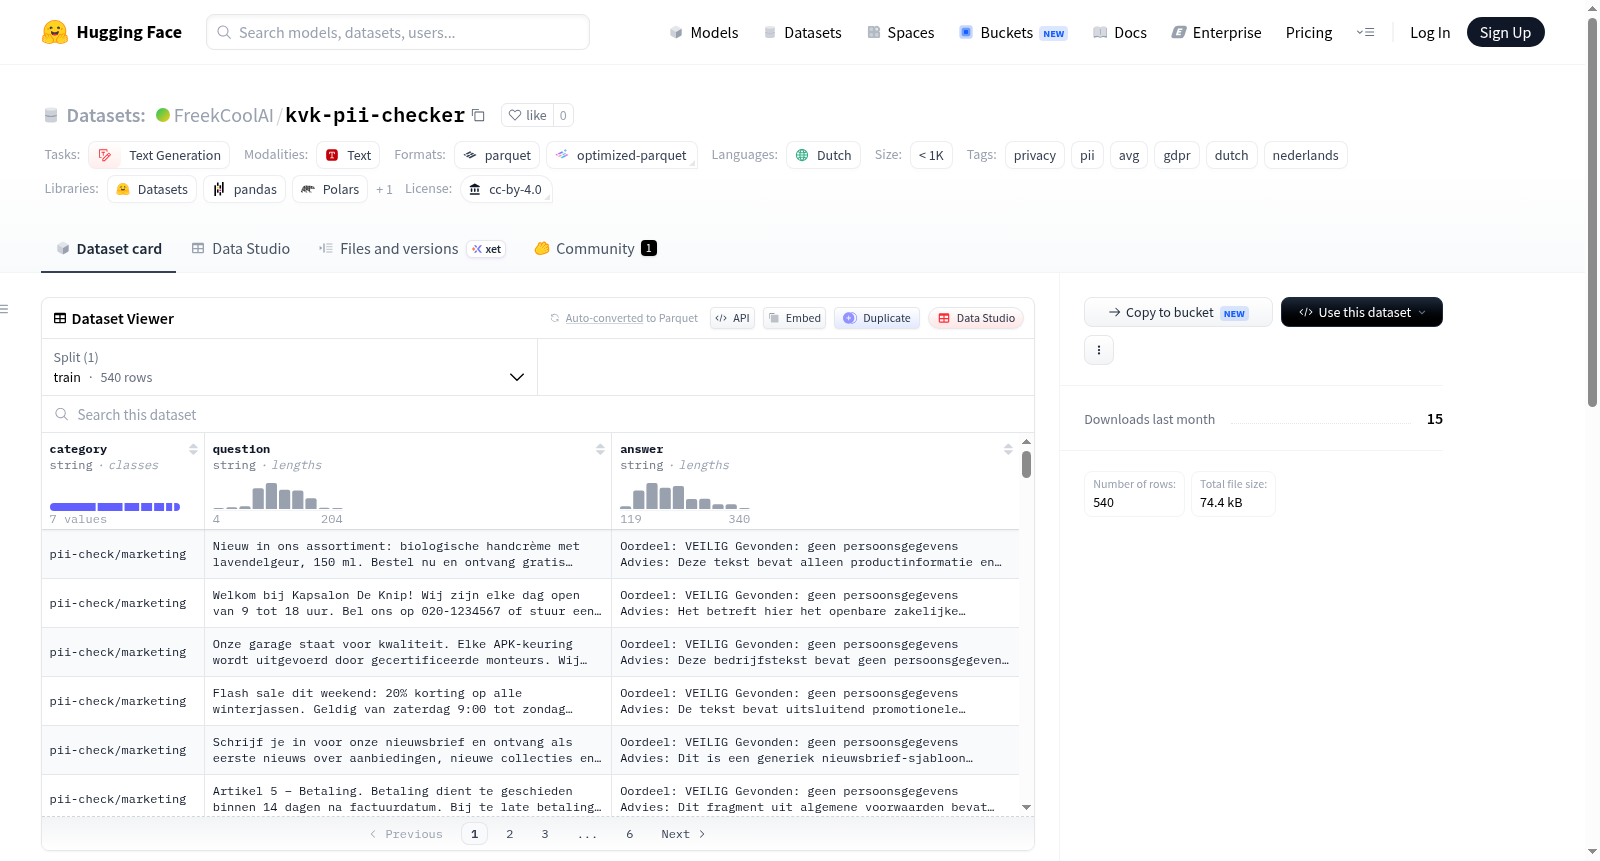
KVK PII检查器数据集是一个荷兰语问答数据集,用于训练微调的大型语言模型(如Gemma-3-1B)作为隐私/AVG(荷兰语中对应GDPR)检查器。给定一段用户可能粘贴到AI工具中的文本,该模型会输出一个三行判断,评估文本中是否包含个人身份信息(PII)。数据格式为JSON,每个示例包括类别、问题(待检查文本)和答案(判断结果)。判断分为三类:VEILIG(安全,无个人数据)、ANONIMISEER EERST(先匿名化,存在普通个人数据如姓名、电子邮件、IBAN等)和NIET VERSTUREN(不要发送,存在特殊个人数据如BSN、健康信息等或高风险情况)。数据集旨在帮助开发隐私保护工具,适用于荷兰语环境下的隐私合规检查。
The KVK PII-checker dataset is a Dutch-language Q&A dataset for training a fine-tuned LLM (such as Gemma-3-1B) as a privacy/AVG (Dutch term for GDPR) checker. Given a text that a user might paste into an AI tool, the model outputs a three-line judgment to assess whether the text contains personally identifiable information (PII). The data format is JSON, with each example including a category, a question (the text to be checked), and an answer (the judgment). The judgments are categorized into three classes: VEILIG (SAFE, no personal data), ANONIMISEER EERST (ANONYMIZE FIRST, presence of ordinary personal data such as name, email, IBAN, etc.), and NIET VERSTUREN (DO NOT SEND, presence of special personal data like BSN, health information, or high risks). The dataset is designed to aid in developing privacy protection tools, suitable for privacy compliance checks in Dutch contexts.