peterkirby/pan2020_dict_author_fandom_doc
收藏资源简介:
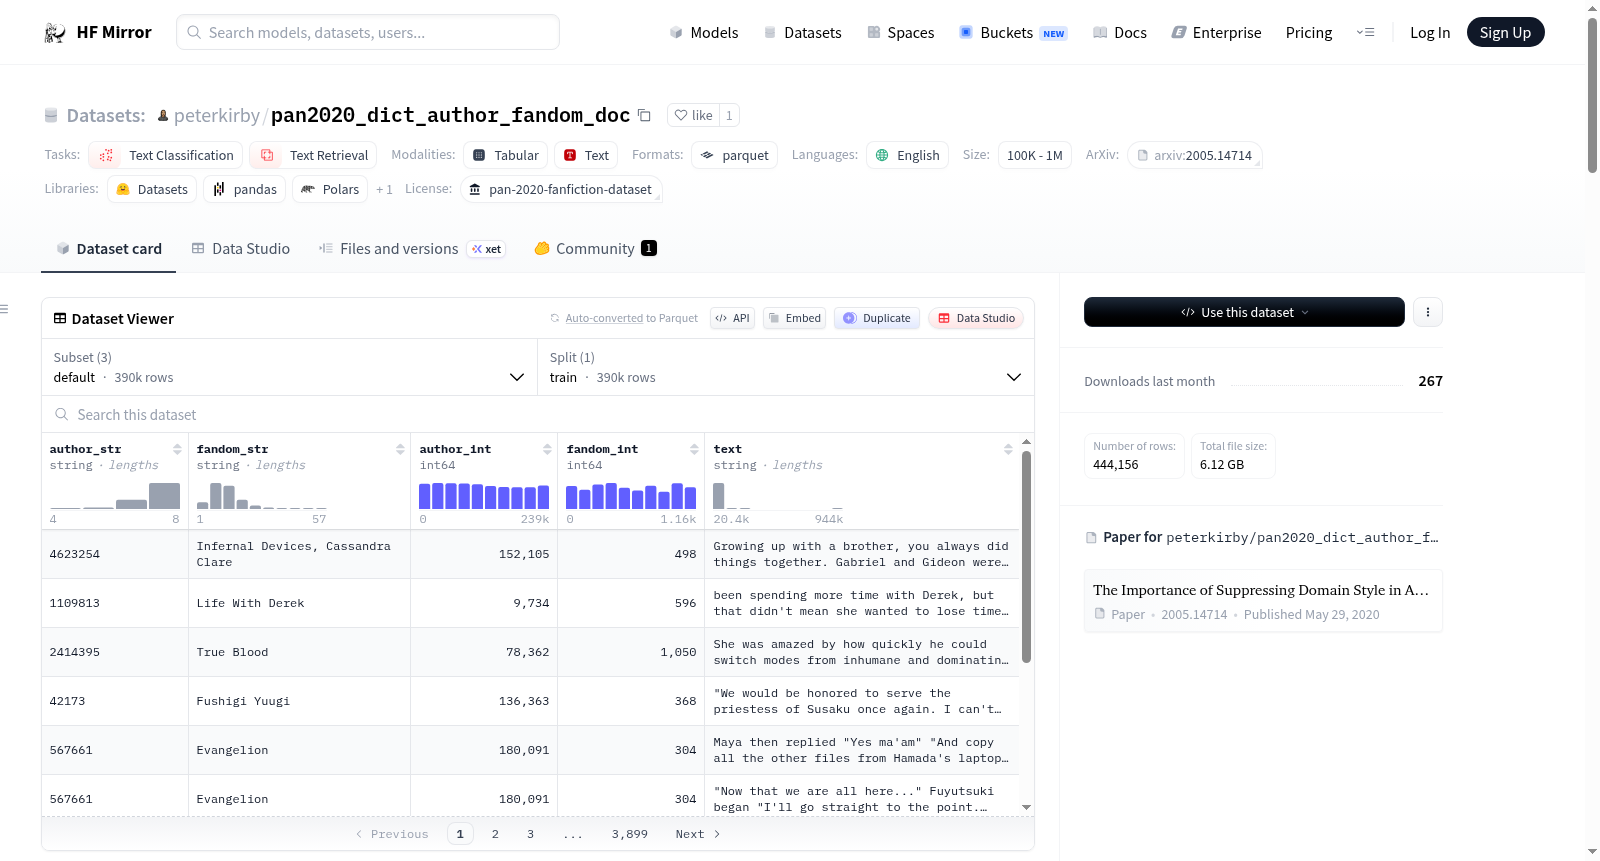
--- license: other license_name: pan-2020-fanfiction-dataset license_link: https://zenodo.org/records/5106099 task_categories: - text-classification - text-retrieval language: - en pretty_name: PAN2020 Fanfiction Author-Fandom-Disjoint Train/Validation Split configs: - config_name: default default: true data_files: - split: train path: train.parquet - config_name: pan21 data_files: - split: validation path: validation.parquet - split: test path: test.parquet - config_name: pan20 data_files: - split: test path: pan20_av.parquet --- # PAN2020 Fanfiction Author-Fandom-Disjoint Train/Validation Split PAN 2020 / PAN 2021 fanfiction authorship verification data with Train/Validation split. The training data has been pre-split into Train and Validation under Author-Fandom-Disjoint constraints as is appropriate for PAN21 test data. The training data is one row per document to allow easy recombination. The PAN21 validation and test splits consist of fixed document pairs for consistent scoring. The string fields are the original data. The integer fields are based on sorting the unique strings. ## Usage ```python from datasets import load_dataset train_data = load_dataset("peterkirby/pan2020_dict_author_fandom_doc", "default", split="train") pan21_val = load_dataset("peterkirby/pan2020_dict_author_fandom_doc", "pan21", split="validation") pan21_test = load_dataset("peterkirby/pan2020_dict_author_fandom_doc", "pan21", split="test") pan20_test = load_dataset("peterkirby/pan2020_dict_author_fandom_doc", "pan20", split="test") ``` ## Configs - `default`: only `train` - `pan21`: `validation` and the PAN21 `test` set - `pan20`: only `test` with the PAN20 authorship verification test set ## Splits ### `train` Columns: - `author_str` - `fandom_str` - `author_int` - `fandom_int` - `text` ### `validation` Columns: - `same` - `author1_str` - `fandom1_str` - `author1_int` - `fandom1_int` - `text1` - `author2_str` - `fandom2_str` - `author2_int` - `fandom2_int` - `text2` Balanced validation set: - 10,000 Same Author / Different Fandom pairs - 10,000 Different Author pairs Same Author / Different Fandom: - `same = true` - same author, different fandoms - document usage histogram: {1: 16900, 2: 1034, 3: 206, 4: 86, 5: 14} (mostly single use) - unordered `(fandom1, fandom2)` is not repeated within an author Different Author: - `same = false` - different authors - no document is repeated - unordered `(author1, author2)` is not repeated - author usage histogram: {2: 882, 3: 819, 4: 716, 5: 2583} (mostly 5 uses per author) The validation dataset in the `pan21` config is intended to be similar in construction to the official PAN21 test dataset. A greedy approach balanced the benefits of data efficiency and random selection with a random but weighted author/fandom selection, reducing the number of documents outside both Train and Validation. Note that a document is in Train or Validation if and only if both the author and fandom are assigned to that set, where there are no overlapping authors and no overlapping fandoms. The 20k pairs were constructed from 30,670 eligible documents in the validation set, which contains 5000 authors and 438 of 1600 fandoms. ### `test` In the `pan21` config, this is the original PAN21 test set (converted to Parquet), an open-set authorship verification problem on unseen authors and fandoms. In the `pan20` config, this is the original PAN20 test set (converted to Parquet), a closed-set authorship verification problem on authors and fandoms already seen in the training data. ## Preprocessing Document text has been very lightly normalized (on top of PAN20's existing normalization) to fix contractions that looked like this: n"t. Helps tokenizers and pre-trained models. ```python APOS_TO_QUOTE = str.maketrans({ "'": '"', "’": '"', "‘": '"', "`": '"', "´": '"' }) BETWEEN_ALPHA_QUOTE = re.compile(r'(?<=[^\W\d_])"(?=[^\W\d_])') def fix_text(s: str) -> str: s = str(s).translate(APOS_TO_QUOTE) return BETWEEN_ALPHA_QUOTE.sub("'", s) ``` ## Citation If you use this dataset for your research, please cite: Sebastian Bischoff, Niklas Deckers, Marcel Schliebs, Ben Thies, Matthias Hagen, Efstathios Stamatatos, Benno Stein, and Martin Potthast. *The Importance of Suppressing Domain Style in Authorship Analysis.* CoRR, abs/2005.14714, May 2020. ### BibTeX ```bibtex @Article{stein:2020k, author = {Sebastian Bischoff and Niklas Deckers and Marcel Schliebs and Ben Thies and Matthias Hagen and Efstathios Stamatatos and Benno Stein and Martin Potthast}, journal = {CoRR}, month = may, title = {{The Importance of Suppressing Domain Style in Authorship Analysis}}, url = {https://arxiv.org/abs/2005.14714}, volume = {abs/2005.14714}, year = 2020 } ```