LocalDoc/en-az-opus-filtered-parallel-corpus
收藏资源简介:
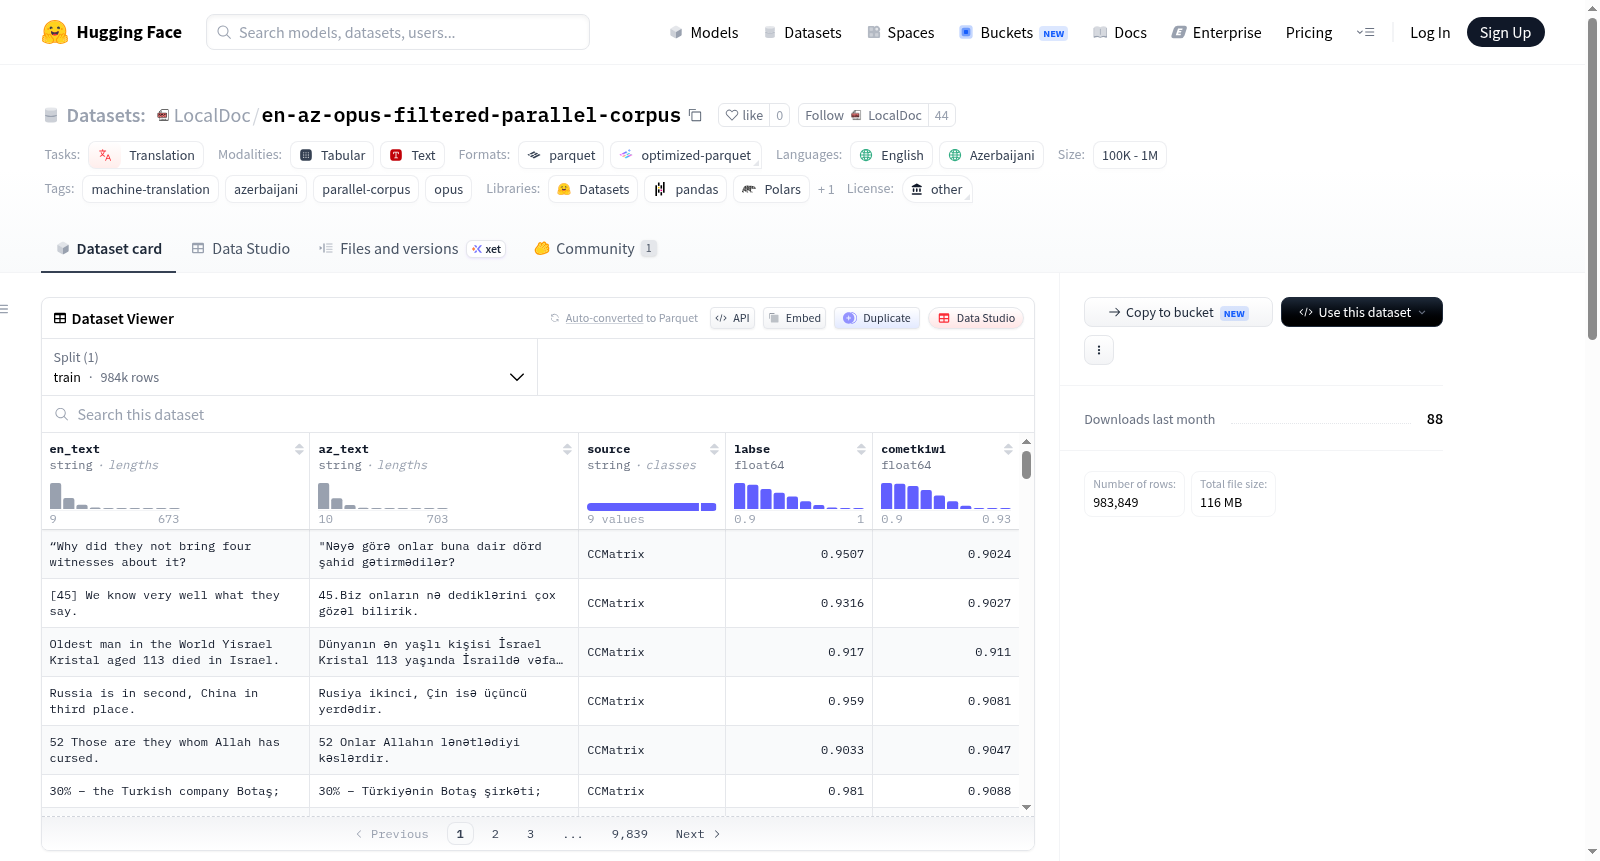
这是一个经过过滤的英语-阿塞拜疆语平行语料库,名为Filtered EN-AZ OPUS Parallel Corpus。数据集从OPUS语料库中收集英语-阿塞拜疆语平行句子,并通过两阶段质量估计流程进行过滤。过滤流程包括:首先使用LaBSE跨语言余弦相似度保留对齐良好的句子对,然后对剩余句子对使用COMET-Kiwi(基于Unbabel/wmt22-cometkiwi-da模型)进行无参考质量估计,最后进行精确去重。本发布版本的有效最小阈值为:LaBSE ≥ 0.900,COMET-Kiwi ≥ 0.900。数据集包含983,849对句子,特征列包括:en_text(英语源句子)、az_text(阿塞拜疆语目标句子)、source(来源OPUS子语料库)、labse(LaBSE余弦相似度得分)、cometkiwi(COMET-Kiwi质量估计得分)。数据主要来源于NLLB(849,380对)、ParaCrawl-Bonus(128,575对)等多个OPUS子语料库。数据集适用于机器翻译任务,支持英语和阿塞拜疆语。
English–Azerbaijani parallel sentences pooled from OPUS corpora and filtered with a two-stage quality-estimation pipeline. The pipeline involves LaBSE cross-lingual cosine similarity to keep well-aligned pairs, followed by COMET-Kiwi (Unbabel/wmt22-cometkiwi-da) reference-free quality estimation on the survivors, and exact-pair deduplication. Effective minimums in this release: LaBSE ≥ 0.900, COMET-Kiwi ≥ 0.900. The dataset contains 983,849 sentence pairs with columns: en_text (English source sentence), az_text (Azerbaijani target sentence), source (originating OPUS sub-corpus), labse (LaBSE cosine similarity score), cometkiwi (COMET-Kiwi QE score). Major sources include NLLB (849,380 pairs), ParaCrawl-Bonus (128,575 pairs), and others from OPUS. It is designed for machine translation tasks in English and Azerbaijani.