media-metadata-gutenberg-books
收藏资源简介:
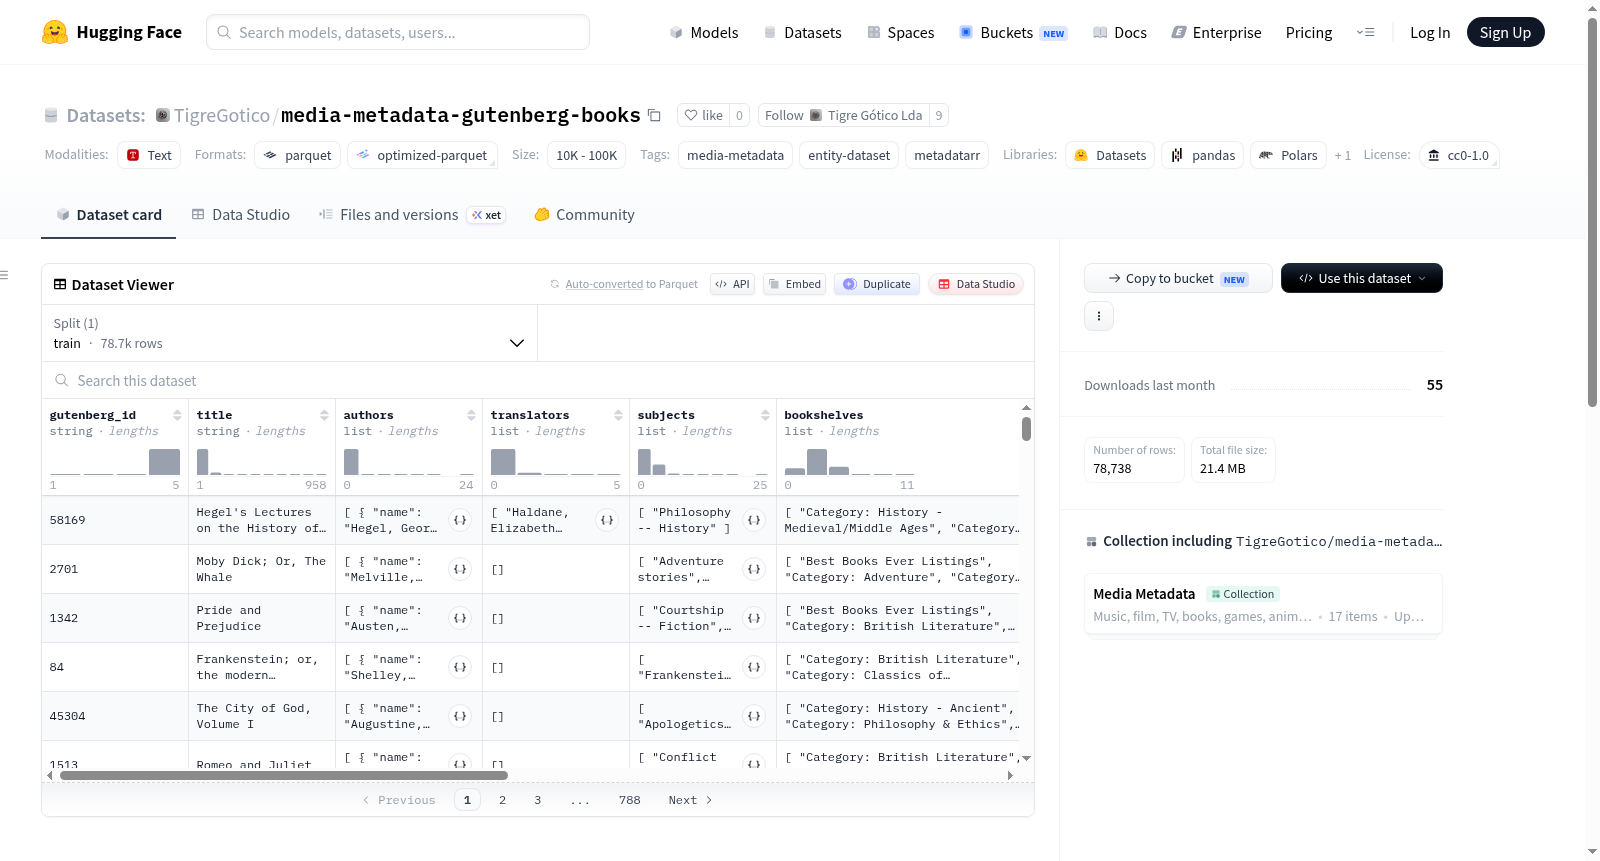
Project Gutenberg Catalog数据集是一个包含约79,000个文本元数据的目录,源自古登堡计划(Project Gutenberg)——成立于1971年的最古老数字图书馆,专门收录美国版权已过期的公共领域书籍。该数据集不包含实际文本内容,而是提供了每个古登堡文本的元数据信息,包括下载链接,可作为构建语料库的便捷索引。数据字段包括:gutenberg_id(文本编号)、title(标题)、authors(作者姓名及生卒年份)、subjects(美国国会图书馆主题标题)、bookshelves(古登堡书架分类)、languages(语言代码)、formats(字典格式,映射MIME类型到下载URL,支持epub、txt、html等格式)、download_count(30天下载次数,作为流行度指标)。数据集适用于文本分析、语料库构建、书籍元数据研究等任务,用户可通过HuggingFace datasets库加载,并利用下载计数筛选热门文本。
The Project Gutenberg Catalog dataset is a directory containing metadata for approximately 79,000 texts, sourced from Project Gutenberg—the oldest digital library founded in 1971, dedicated to public domain books with expired U.S. copyrights. This dataset does not include actual text content but provides metadata for each Gutenberg text, including download links, serving as a convenient index for corpus construction. Data fields include: gutenberg_id (text identifier), title (title), authors (author names and birth/death years), subjects (Library of Congress subject headings), bookshelves (Gutenberg bookshelf classifications), languages (language codes), formats (dictionary mapping MIME types to download URLs, supporting formats like epub, txt, html), and download_count (30-day download count as a popularity metric). The dataset is suitable for tasks such as text analysis, corpus building, and book metadata research, and can be loaded via the HuggingFace datasets library, allowing users to filter popular texts based on download counts.