smart-form-fill-relevant-tabs
收藏资源简介:
该数据集名为“智能表单填写 - 相关标签页(选择标签页评估)”,用于评估模型在智能表单填写场景中识别相关浏览器标签页的能力。给定用户当前正在填写的表单(作为锚点)以及一组已打开的浏览器标签页(候选者,仅包含标题和URL),任务是判断哪些标签页是填写该表单的相关信息来源。每个数据样本代表一个独立的浏览器会话。数据集包含528个会话,其中404个会话包含至少一个相关标签页(has_relevant),124个会话为不包含任何相关标签页的空案例(null_case)。数据规模通过会话大小(session_size)进行切片,取值包括6、12、20、30、40、50,以模拟不同数量的打开标签页场景,其中40和50用于压力测试。模型输入包括锚点标题(anchor_title)、锚点URL(anchor_url)、锚点字段列表(anchor_fields,JSON格式)以及会话中的所有标签页列表(session_tabs,JSON格式,每个标签页包含id、title、url)。标签基于锚点字段类型与候选标签页“提供”的能力之间的交集计算相关性分数,其中独特字段类型(如护照、信用卡、SSN等)权重为1.5,常见类型权重为1,其他或上下文相关类型权重为0;当总分≥3.0时,该标签页被视为相关。标签列包括相关标签页ID列表(relevant_tab_ids)以及每个标签页的详细分数(tab_relevance,用于NDCG等排名指标)。数据集还提供了用于分析和切片的列,如会话类型、会话大小、锚点来源数据集、锚点独特类型、锚点字段类型、标签页种类(表单、内容源、干扰项)等。该数据集是一个合成代理数据集,内容源标签页的元数据是人工构建的,适用于文本分类、信息检索和排名任务,特别是浏览器辅助表单填充系统的评估。
This dataset is named "Smart Form Filling - Relevant Tab Pages (Tab Page Selection Evaluation)", designed to evaluate the models ability to identify relevant browser tabs in a smart form-filling scenario. Given a form currently being filled by the user (as the anchor) and a set of open browser tabs (candidates, including only title and URL), the task is to determine which tabs are relevant sources of information for filling the form. Each data sample represents an independent browser session. The dataset contains 528 sessions, of which 404 contain at least one relevant tab (has_relevant), and 124 are null cases with no relevant tabs. The data scale is sliced by session size (session_size), with values including 6, 12, 20, 30, 40, and 50 to simulate different numbers of open tabs, with 40 and 50 used for stress testing. Model inputs include anchor title (anchor_title), anchor URL (anchor_url), anchor field list (anchor_fields, in JSON format), and the list of all tabs in the session (session_tabs, in JSON format, each tab containing id, title, url). Labels are computed based on the intersection between anchor field types and the provided capabilities of candidate tabs, with weights of 1.5 for unique field types (e.g., passport, credit card, SSN), 1 for common types, and 0 for other or context-related types; a tab is considered relevant when the total score ≥ 3.0. Label columns include a list of relevant tab IDs (relevant_tab_ids) and detailed scores for each tab (tab_relevance, for ranking metrics like NDCG). The dataset also provides columns for analysis and slicing, such as session type, session size, anchor source dataset, anchor unique types, anchor field types, and tab categories (form, content source, distractor). This dataset is a synthetic proxy dataset, with metadata of content source tabs manually constructed, suitable for text classification, information retrieval, and ranking tasks, especially for evaluating browser-assisted form-filling systems.
数据集概述
- 数据集名称:Smart Form Fill - Relevant Tabs (Call 2 /
select_tabs) eval (v2) - 任务类别:文本分类(text-classification)
- 标签:smart-form-fill, firefox, tab-relevance
- 数据集配置:默认配置(
default),包含训练集(train),数据文件为data/train-*.parquet
数据集描述
该数据集用于评估在用户填写表单时,从一组打开的浏览器标签页中,选取与表单填充相关的标签页。每一行代表一个会话(session)。
模型输入(每行)
page{anchor_title, anchor_url}:锚点页面标题和URLanchor_fields:锚点字段(JSON格式)session_tabs:会话中的标签页列表(JSON格式,包含id、title、url),仅包含元数据- 模型需要为每个标签页ID返回相关性判断
标签定义
-
相关性分数:
relevance = score(anchor.field_types INTERSECT candidate.provides)- 特殊类型(passport-/cc-/ssn/linkedin/github/work-authorization/id-number/nationality/referral-source)权重为1.5倍
- 常见类型权重为1倍
- 其他/上下文类型权重为0
- 当分数 >= 3.0 时,该标签页被视为相关
-
候选标签页类型:
- 内容来源标签页(如LinkedIn、GitHub、简历、账户、订单、航班、SSA、钱包等):提供一系列字段
- 干扰项(非表单页面):不提供任何字段
-
标签生成方式:根据
provides计算得出,不会展示给模型
数据列说明
| 列名 | 说明 |
|---|---|
anchor_title |
锚点页面标题 |
anchor_url |
锚点页面URL |
anchor_fields |
锚点字段(JSON) |
session_tabs |
会话中的标签页列表(JSON,包含 id、title、url) |
relevant_tab_ids |
相关标签页ID列表(JSON,分数>=3) |
tab_relevance |
每个标签页的相关性分数(JSON,用于NDCG/前N评估) |
session_type |
会话类型(has_relevant / null_case) |
session_size |
会话大小(标签页数量,取值6、12、20、30、40、50) |
anchor_dataset |
锚点数据集来源 |
anchor_distinctive_types |
锚点特殊字段类型 |
anchor_field_types |
锚点字段类型 |
tab_kinds |
每个标签页的类型(JSON,值为 form、content_source、distractor) |
num_relevant |
相关标签页数量 |
tabs_debug |
调试信息 |
数据集说明
- 会话大小(n):是数据集的一个维度(
get_open_tabs产品上限为30,40和50用于压力测试),评估时可按session_size切片 - m(maxSelectedTabs):是评分时的可调参数,行数据中保留完整排名
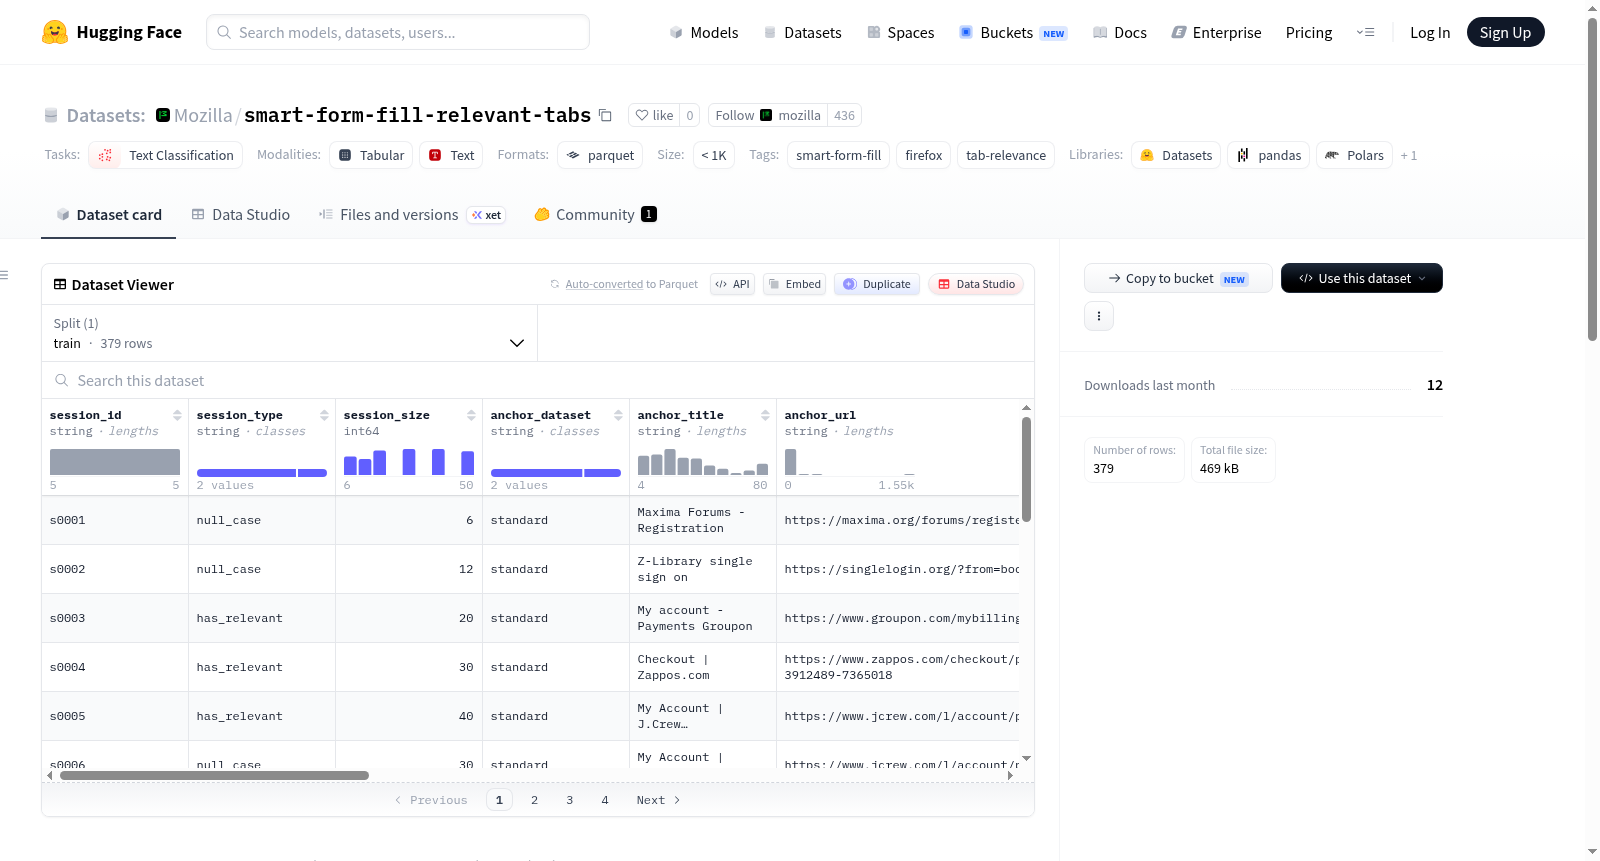
- 数据集规模:共379个会话(290个有相关标签页 / 89个无相关标签页;其中75个密集会话,有5个以上的相关标签页)
- 实际构成:每个会话通常有1-2个真实相关标签页(密集切片中为5-8个),其余为内容标签页或干扰项
- 相关性依据:类别匹配(商业、求职、旅行、身份验证来源),与人工标签验证一致(11/11)
- 语言:仅英文文本
- 性质:合成代理数据集
加载方式
python from datasets import load_dataset ds = load_dataset("Mozilla/smart-form-fill-relevant-tabs", split="train")