sulabhkatiyar/ne-asr-ccp-aug
收藏资源简介:
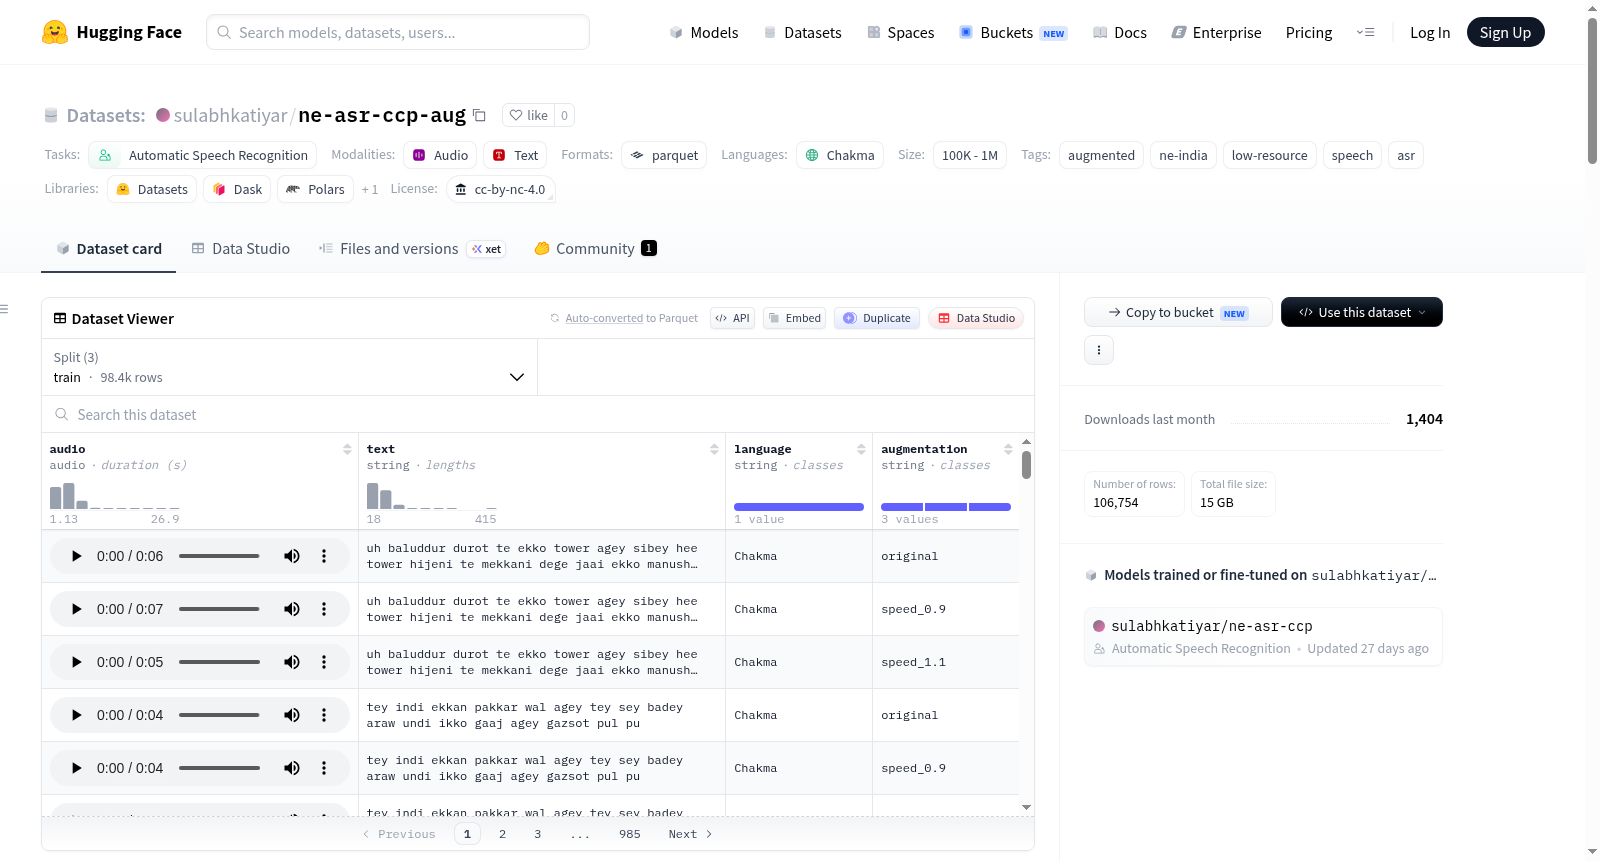
NE ASR增强数据集——Chakma(ccp)是一个用于自动语音识别(ASR)的增强数据集,专门针对Chakma语言(ISO 639-3代码:ccp)。Chakma是一种在印度米佐拉姆邦使用的印度-雅利安语,属于有声调语言。该数据集基于原始数据sulabhkatiyar/ne-asr-ccp进行增强,原始数据来自ARTPARK-IISc Vaani项目。增强过程仅应用速度扰动(0.9倍和1.1倍),未应用音高偏移(以保留声调语言的词汇意义),训练样本从32,807个原始样本增加到98,421个(3倍增强)。数据集包含训练、验证和测试分割,音频为16kHz单声道WAV格式(以Parquet文件存储字节),并包括文本转录、语言和增强标签等信息。数据集许可证为CC-BY-NC 4.0,适用于低资源语音处理研究。
NE ASR Augmented Dataset -- Chakma (ccp) is an augmented automatic speech recognition dataset for the Chakma language (ISO 639-3: ccp), an Indo-Aryan tonal language spoken in Mizoram, India. It is augmented from the original dataset sulabhkatiyar/ne-asr-ccp, which contains transcribed speech data from the ARTPARK-IISc Vaani project. The augmentation applies only speed perturbation (factors 0.9 and 1.1) without pitch shift to preserve lexical tone contrasts, expanding the training samples from 32,807 original samples to 98,421 (3x augmentation). The dataset includes train, validation, and test splits, with audio stored as 16kHz mono WAV in Parquet format, along with text transcriptions, language, and augmentation labels. It is licensed under CC-BY-NC 4.0 and is designed for low-resource speech processing.