llm-econ-memorization
收藏资源简介:
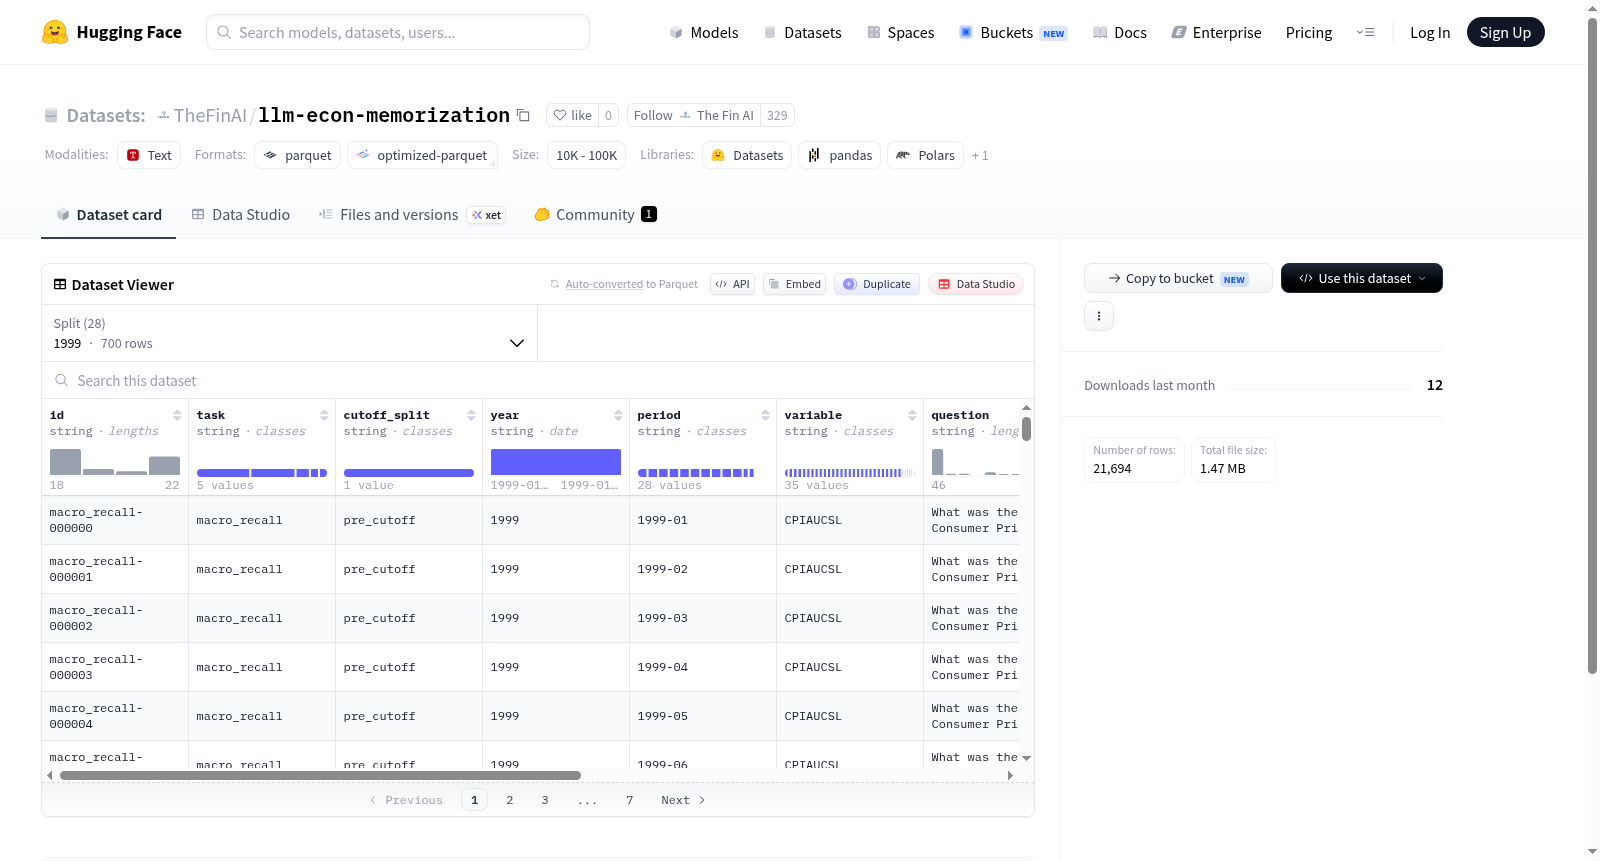
该数据集是一个多年度、结构化的问题-回答数据集,涵盖1999年至2026年(含部分年份)的样本。数据集中每个样本包含12个字段:唯一标识符(id)、任务类型(task)、截止划分信息(cutoff_split)、年份(year)、时期(period)、变量(variable)、自然语言问题(question)、上下文信息(context)、提示文本(prompt)、答案(answer)、答案类型(answer_type)以及元数据JSON字符串(meta_json)。数据集按年份划分,每年样本量在338至820之间,总样本量约17,000余条。适用于语言模型评估、问答系统训练、时序数据分析等任务,尤其适合研究模型在不同年份、任务类型和变量条件下的表现。
This dataset is a multi-year, structured question-answer dataset covering samples from 1999 to 2026 (including some years). Each sample in the dataset contains 12 fields: unique identifier (id), task type (task), cutoff split information (cutoff_split), year (year), period (period), variable (variable), natural language question (question), context information (context), prompt text (prompt), answer (answer), answer type (answer_type), and metadata JSON string (meta_json). The dataset is divided by year, with annual sample sizes ranging from 338 to 820, and a total sample size of approximately 17,000 entries. It is suitable for tasks such as language model evaluation, question-answering system training, and time-series data analysis, particularly well-suited for studying model performance under different years, task types, and variable conditions.
数据集概述:llm-econ-memorization
该数据集由 TheFinAI 团队提供,旨在用于评估或分析大语言模型 (LLM) 对经济学相关知识的记忆能力。
基本信息
- 数据集名称: llm-econ-memorization
- 提供者: TheFinAI
- 来源地址: https://huggingface.co/datasets/TheFinAI/llm-econ-memorization
数据规模
- 总数据集大小: 12,934,932 字节
- 下载大小: 1,464,580 字节
- 总样本数量: 约 21,086 条(基于所有 splits 的示例数总和)
数据特征 (Features)
该数据集包含 12 个字段,用于描述每条经济学相关的问答数据:
| 字段名称 | 数据类型 | 描述 |
|---|---|---|
id |
string | 样本唯一标识符 |
task |
string | 任务类型 |
cutoff_split |
string | 数据截止分割标识 |
year |
string | 数据对应的年份 |
period |
string | 数据对应的时间段 |
variable |
string | 涉及的变量名称 |
question |
string | 问题文本 |
context |
string | 相关的上下文或背景信息 |
prompt |
string | 提供给模型使用的提示词 |
answer |
string | 标准答案 |
answer_type |
string | 答案的类型(如单选、多选等) |
meta_json |
string | 元数据,格式为 JSON 字符串 |
数据分割 (Splits)
数据按年份进行分割,涵盖了从 1999 年到 2026 年的经济学数据。每个年份对应一个独立的数据集分割(split),具体分布如下:
- 1999年: 700 条样本
- 2000年至2003年: 每年 748 条样本
- 2004年: 756 条样本
- 2005年至2009年: 每年 772 条样本
- 2010年: 784 条样本
- 2011年: 796 条样本
- 2012年: 810 条样本
- 2013年至2024年: 每年 820 条样本
- 2025年: 818 条样本
- 2026年: 338 条样本
数据文件配置
数据采用默认配置 (default),每个年份的数据文件存储在 data/ 目录下,文件命名格式为 {年份}-*。例如,1999 年的数据文件位于 data/1999-*。