baber/hendrycks_math
收藏资源简介:
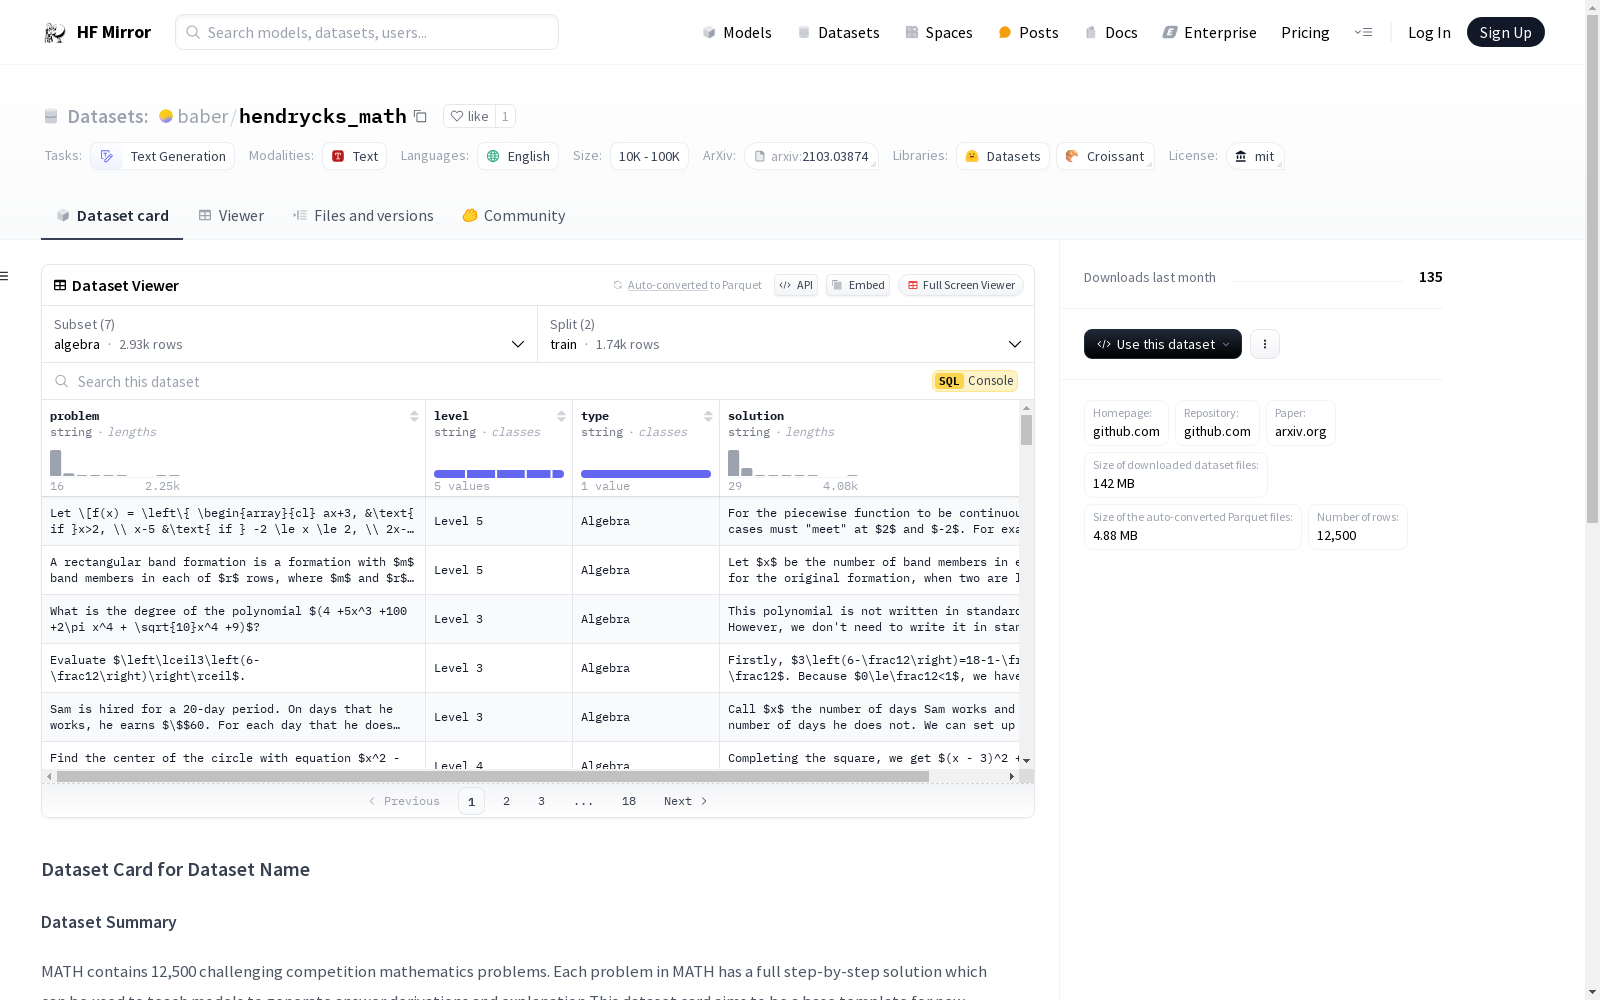
MATH数据集包含12,500个具有挑战性的竞赛数学问题。每个问题都有详细的逐步解答,可用于训练模型生成答案推导和解释。数据集主要用于文本生成任务,语言为英语,规模在10K到100K之间。数据集分为7个子数据集,训练集包含7500个问题,测试集包含5000个问题。数据集的许可证为MIT,但建议查看论文附录B中的法律合规部分以及仓库中的许可证文件。
The MATH dataset contains 12,500 challenging competitive mathematics problems. Each problem is paired with detailed step-by-step solutions, which can be utilized to train models to generate answer derivations and explanatory content. This dataset is primarily intended for text generation tasks, is written in English, and has a scale ranging between 10K and 100K. It is divided into 7 subsets, where the training set includes 7,500 problems and the test set includes 5,000 problems. The dataset is licensed under MIT License; however, it is recommended to review the legal compliance section in Appendix B of the associated paper and the license file in the corresponding repository.
数据集卡片
数据集描述
- 数据集名称: MATH
- 数据集概述: MATH包含12,500个具有挑战性的竞赛数学问题。每个问题都附有完整的逐步解决方案,可用于指导模型生成答案推导和解释。
数据集结构
数据实例
- 子数据集数量: 7个
数据分割
- 训练集: 7500个问题
- 测试集: 5000个问题
附加信息
许可信息
- 许可: MIT
- 法律合规性: 请参阅论文附录B中的Legal Compliance部分以及仓库。
引用信息
plaintext @article{hendrycksmath2021, title={Measuring Mathematical Problem Solving With the MATH Dataset}, author={Dan Hendrycks and Collin Burns and Saurav Kadavath and Akul Arora and Steven Basart and Eric Tang and Dawn Song and Jacob Steinhardt}, journal={NeurIPS}, year={2021} }