marin-community/synth-bootstrap-trial
收藏资源简介:
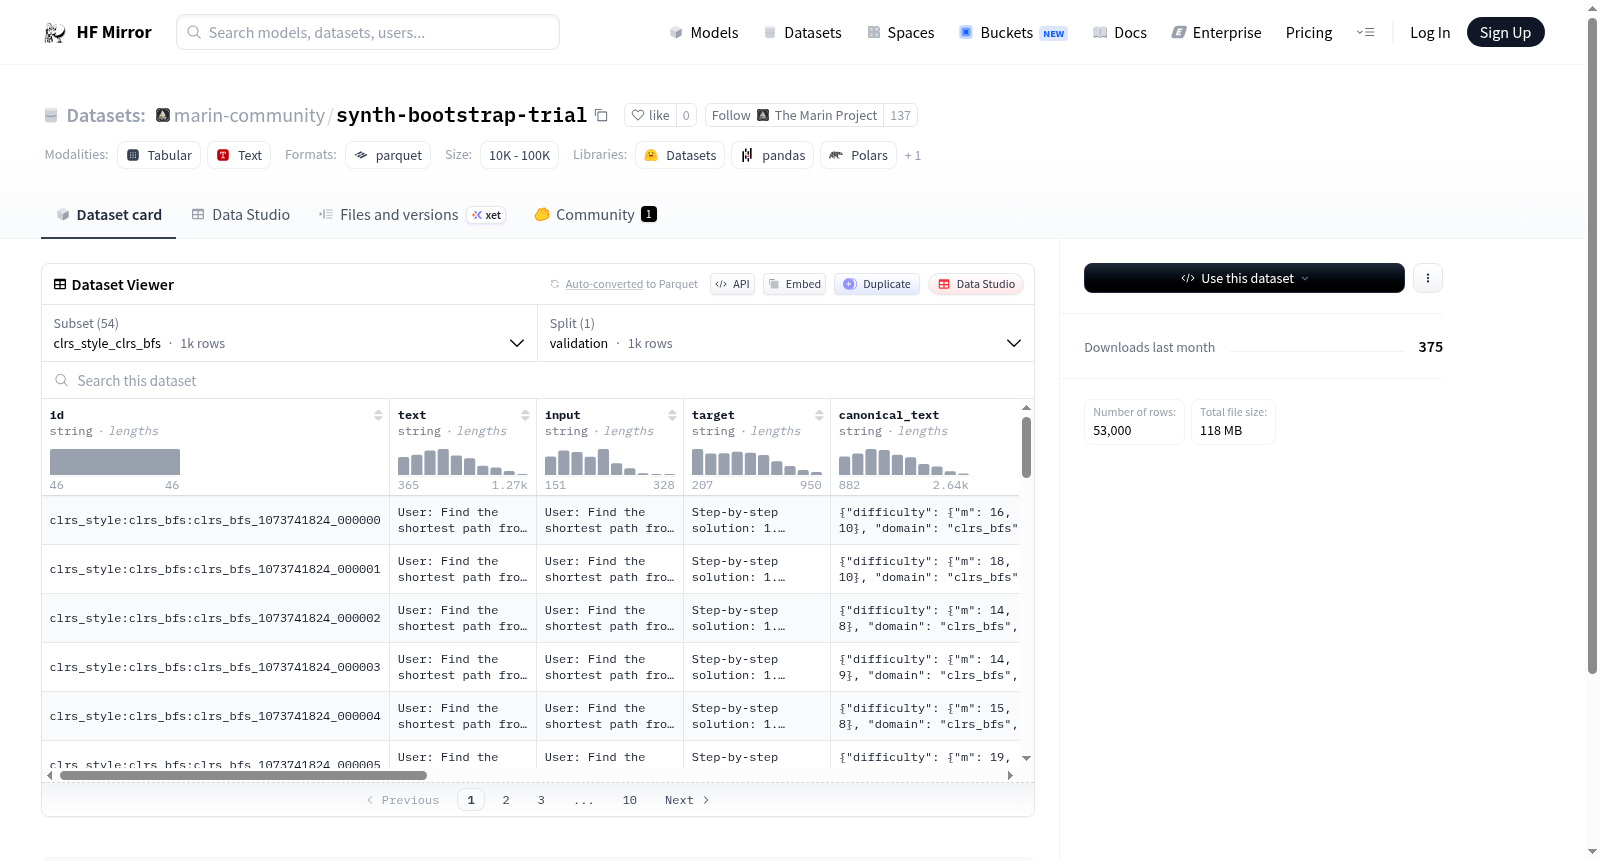
该数据集是一个包含多种算法任务的数据集,用于评估或训练模型在算法理解和执行方面的能力。数据集包括多个配置,覆盖经典算法如广度优先搜索、二分查找、连通分量、迪杰斯特拉最短路径、弗洛伊德-沃舍尔全源最短路径、插入排序、最长公共子序列长度、最长递增子序列、普里姆最小生成树、拓扑排序等。每个配置提供文本描述、输入、目标输出、规范文本、聊天文本、任务家族、任务名称、求解器任务名称、配置文件、种子、域种子、索引、源代码提交和元数据JSON等特征。数据集仅包含验证集,每个配置有1000个示例,适用于算法推理、代码生成或自然语言处理任务的研究。
This dataset is a collection of various algorithmic tasks designed for evaluating or training models in algorithm understanding and execution. It includes multiple configurations covering classic algorithms such as breadth-first search, binary search, connected components, Dijkstras shortest path, Floyd-Warshall all-pairs shortest path, insertion sort, longest common subsequence length, longest increasing subsequence, Prims minimum spanning tree, topological sort, and more. Each configuration provides features like id, text, input, target, canonical text, chat text, family, task name, solver task name, profile, seed, domain seed, index, source commit, and metadata JSON. The dataset only contains a validation split with 1000 examples per configuration, suitable for research in algorithmic reasoning, code generation, or natural language processing tasks.