balua-food-es
收藏资源简介:
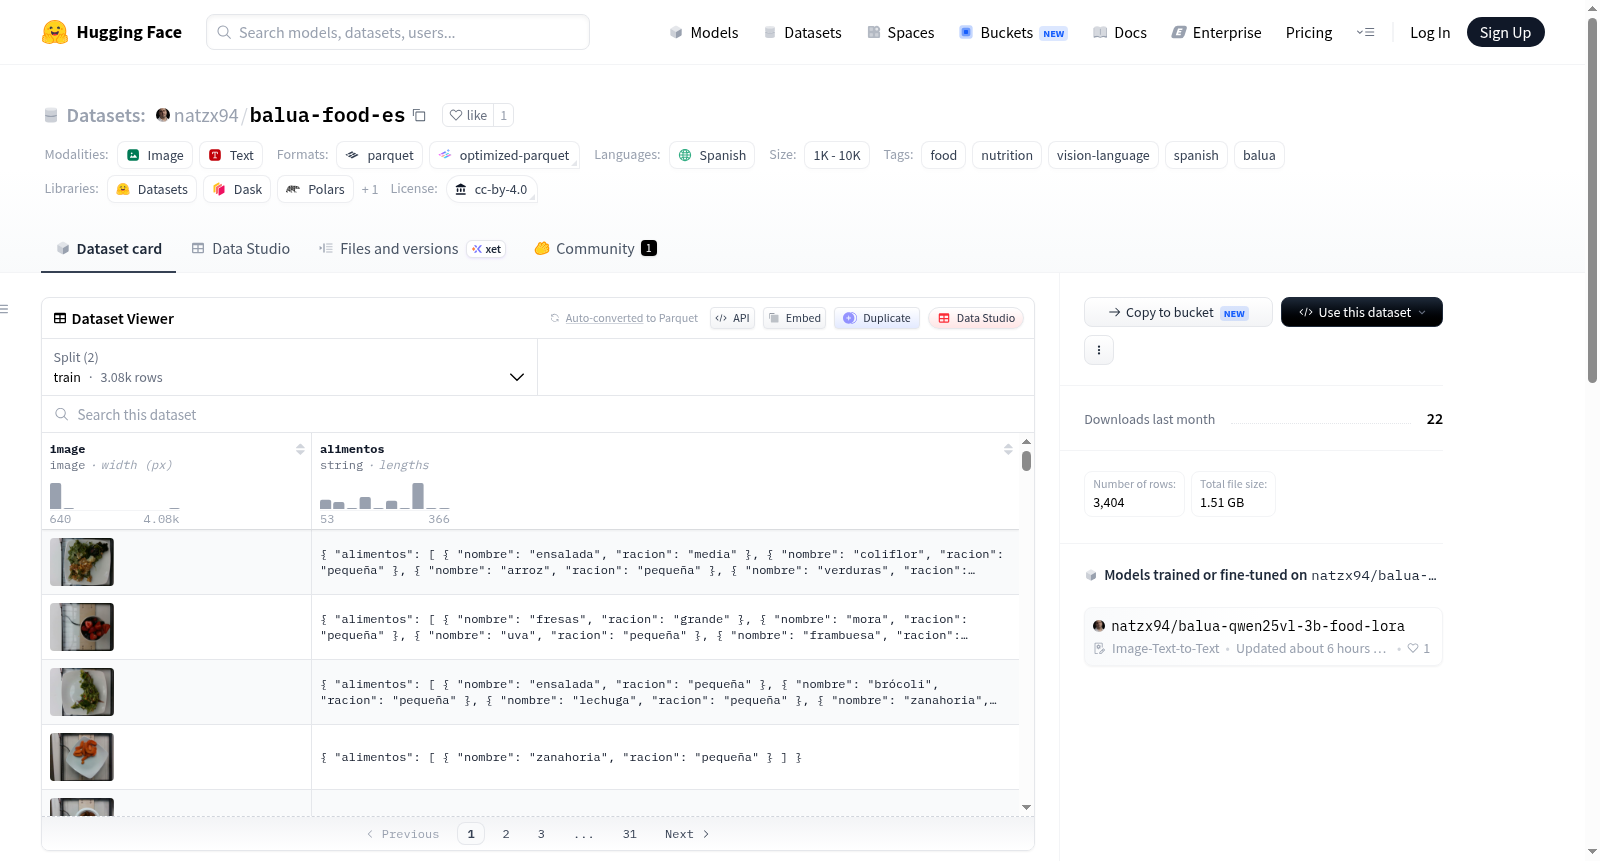
Balùa Food (español) 是一个专为视觉语言模型微调设计的西班牙语食物识别数据集,源自Balùa应用(一款通过照片估算热量的设备端应用)。它包含俯拍视角的餐盘照片,标注了可见的主要食物及其估计分量(小/中/大)。数据集基于Nutrition5k(Thames等人,CVPR 2021,CC BY 4.0)的俯拍图像构建,但标签通过视觉蒸馏过程独立生成:使用Qwen2.5-VL-7B模型(Q4_K_M量化,温度0)处理每张照片,以西班牙语通用名称列出最多4种可见食物及其分量,输出为可解析的JSON。标签旨在描述“照片中实际可见的内容”,而非原始元数据中的克重信息。数据集包含3078个训练样本和326个验证样本,每个样本包括两个字段:`image`(餐盘的RGB俯拍照片)和`alimentos`(JSON格式字符串,结构为`{"alimentos":[{"nombre":"食物名称","racion":"分量"}]}`)。适用于图像到文本任务,特别是食物、营养、视觉语言和多模态模型的微调与研究。采用CC BY 4.0许可证,使用图像需注明Nutrition5k出处,标签归属Balùa项目,仅用于研究和教育目的,非临床营养建议。
Balùa Food (español) is a Spanish food recognition dataset designed for fine-tuning vision-language models, originating from the Balùa app (an on-device application that estimates calories from photos). It contains overhead-view plate photos annotated with visible main foods and their estimated portions (small/medium/large). The dataset is built on overhead images from Nutrition5k (Thames et al., CVPR 2021, CC BY 4.0), but the labels are independently generated through a visual distillation process: each photo is processed by the Qwen2.5-VL-7B model (Q4_K_M quantization, temperature 0), which is prompted to list up to four visible foods in Spanish common names and their apparent portions, with outputs validated as parsable JSON. The labels aim to describe what is actually visible in the photo, rather than the gram weight information in the original metadata. The dataset includes 3078 training samples and 326 validation samples, each with two fields: `image` (RGB overhead photo of the plate) and `alimentos` (a JSON-formatted string with the structure `{"alimentos":[{"nombre":"food name","racion":"portion"}]}`). It is suitable for image-to-text tasks, particularly for fine-tuning and research in food, nutrition, vision-language, and multimodal models. It uses the CC BY 4.0 license; use of the images requires attribution to Nutrition5k, while the labels belong to the Balùa project, and it is intended for research and educational purposes only, not as clinical nutrition advice.
数据集概述:Balùa Food (español)
该数据集来自 Balùa 应用,专为微调视觉-语言模型(VLM)设计,用于从食物照片中估计卡路里。数据集包含西班牙语标注的食物图像。
- 许可证:CC BY 4.0
- 语言:西班牙语(es)
- 任务:图像到文本(image-to-text)
- 标签:食物、营养、视觉-语言、西班牙语、balua
- 数据规模:1,000 < 样本数 < 10,000
数据特征:
image:RGB 俯拍食物照片(图像类型)alimentos:JSON 格式字符串,包含食物名称和份量({"alimentos":[{"nombre","racion"}]}),份量分为pequeña(小)、media(中)、grande(大)
数据集划分:
- 训练集:3,078 个样本,约 1.39 GB
- 验证集:326 个样本,约 136 MB
- 总下载大小:约 1.51 GB
- 总数据集大小:约 1.52 GB
数据构建方法:
- 标签为 100% 自有,通过视觉蒸馏生成:每张照片由 Qwen2.5-VL-7B(Q4_K_M,温度 0)处理,最多识别 4 种可见食物(西班牙语通用名称)及其 apparent 份量,输出验证为可解析的 JSON。
- 图像来源于 Nutrition5k(Thames et al., CVPR 2021, CC BY 4.0),仅选取俯拍图像(
realsense_overhead)。
使用示例: python from datasets import load_dataset ds = load_dataset("natzx94/balua-food-es") print(ds["train"][0]["alimentos"])
许可证与归属:
- CC BY 4.0 许可。
- 图像需标注 Attribution 至 Nutrition5k(Thames et al., CVPR 2021);标签为 Balùa 项目所有。
- 仅供研究或教育用途。份量与食物识别为参考性质,不构成临床营养评估。