
MorishT/2024-07-08.JFLD.step-1
收藏官方服务:
资源简介:
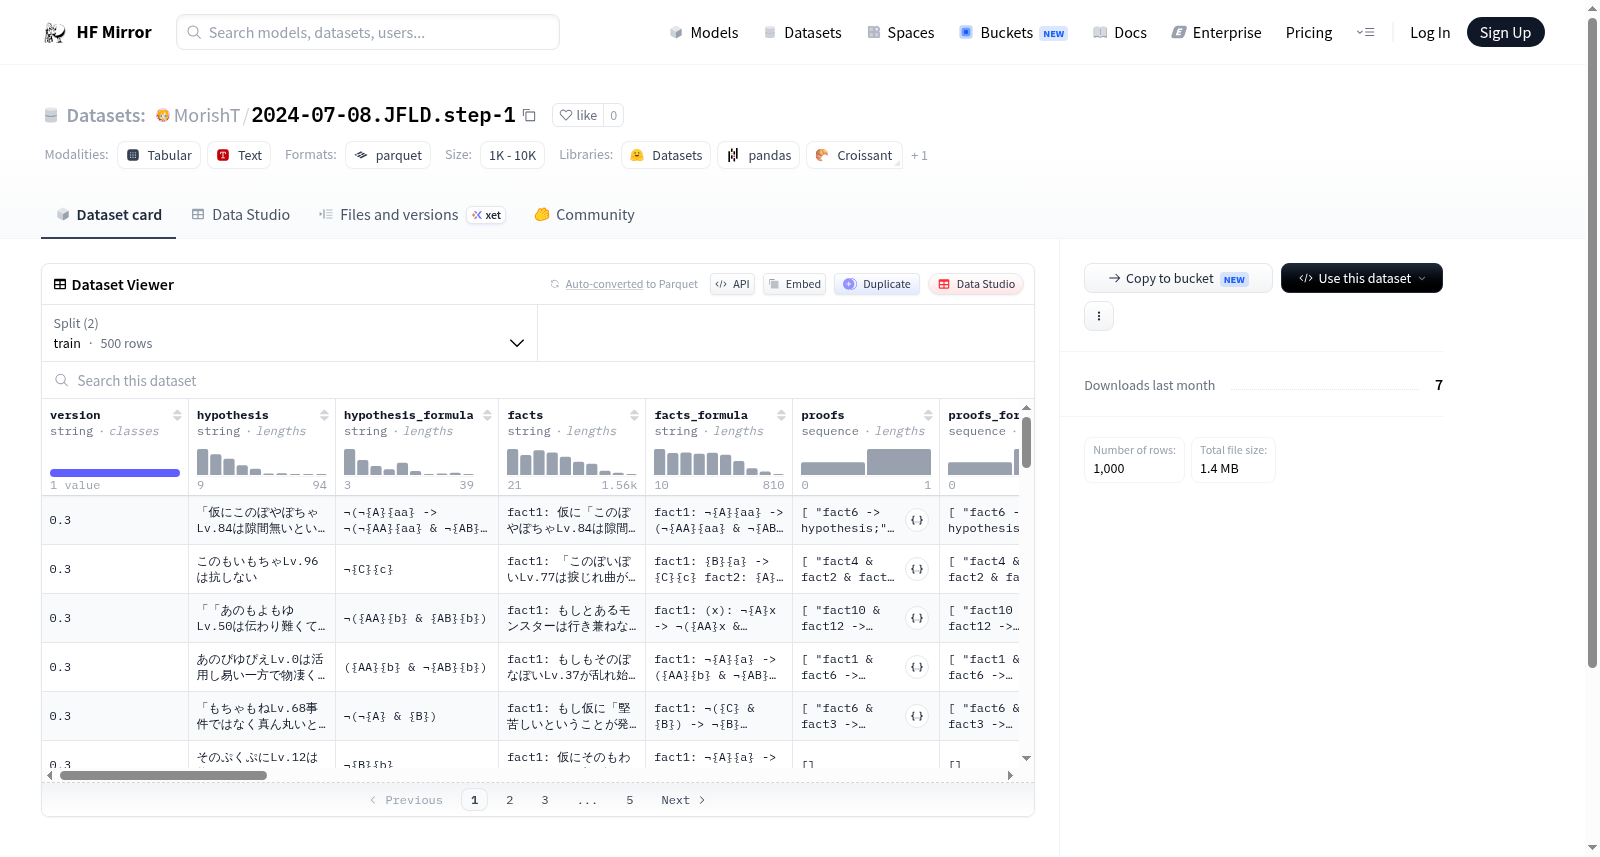
该数据集包含多个特征,如版本、假设、假设公式、事实、事实公式、证明、证明公式等。数据集分为训练集和测试集,分别包含500个样本。数据集的下载大小为1392554字节,总大小为4053619字节。
This dataset contains multiple features such as version, hypothesis, hypothesis formula, facts, facts formula, proofs, proofs formula, etc. The dataset is divided into a training set and a test set, each containing 500 samples. The download size of the dataset is 1392554 bytes, and the total size is 4053619 bytes.
提供机构:
MorishT原始信息汇总
数据集概述
数据集特征
- version: 字符串类型
- hypothesis: 字符串类型
- hypothesis_formula: 字符串类型
- facts: 字符串类型
- facts_formula: 字符串类型
- proofs: 字符串序列类型
- proofs_formula: 字符串序列类型
- negative_hypothesis: 字符串类型
- negative_hypothesis_formula: 字符串类型
- negative_proofs: 字符串序列类型
- negative_original_tree_depth: 64位整数类型
- original_tree_steps: 64位整数类型
- original_tree_depth: 64位整数类型
- steps: 64位整数类型
- depth: 64位整数类型
- num_formula_distractors: 64位整数类型
- num_translation_distractors: 64位整数类型
- num_all_distractors: 64位整数类型
- proof_label: 字符串类型
- negative_proof_label: 字符串类型
- world_assump_label: 字符串类型
- negative_world_assump_label: 字符串类型
- prompt_serial: 字符串类型
- proof_serial: 字符串类型
- prompt_serial_formula: 字符串类型
- proof_serial_formula: 字符串类型
数据集分割
- train:
- 字节数: 2009257
- 样本数: 500
- test:
- 字节数: 2044362
- 样本数: 500
数据集大小
- 下载大小: 1392554 字节
- 数据集总大小: 4053619 字节
配置
- config_name: default
- data_files:
- train: data/train-*
- test: data/test-*
- data_files:
搜集汇总
数据集介绍
背景与挑战
背景概述
该数据集是一个用于逻辑推理任务的数据集,包含假设、事实和证明等字段,支持自然语言和逻辑公式的表示。数据集规模适中,分为训练集和测试集,适用于自然语言处理和自动推理研究。
以上内容由遇见数据集搜集并总结生成


