
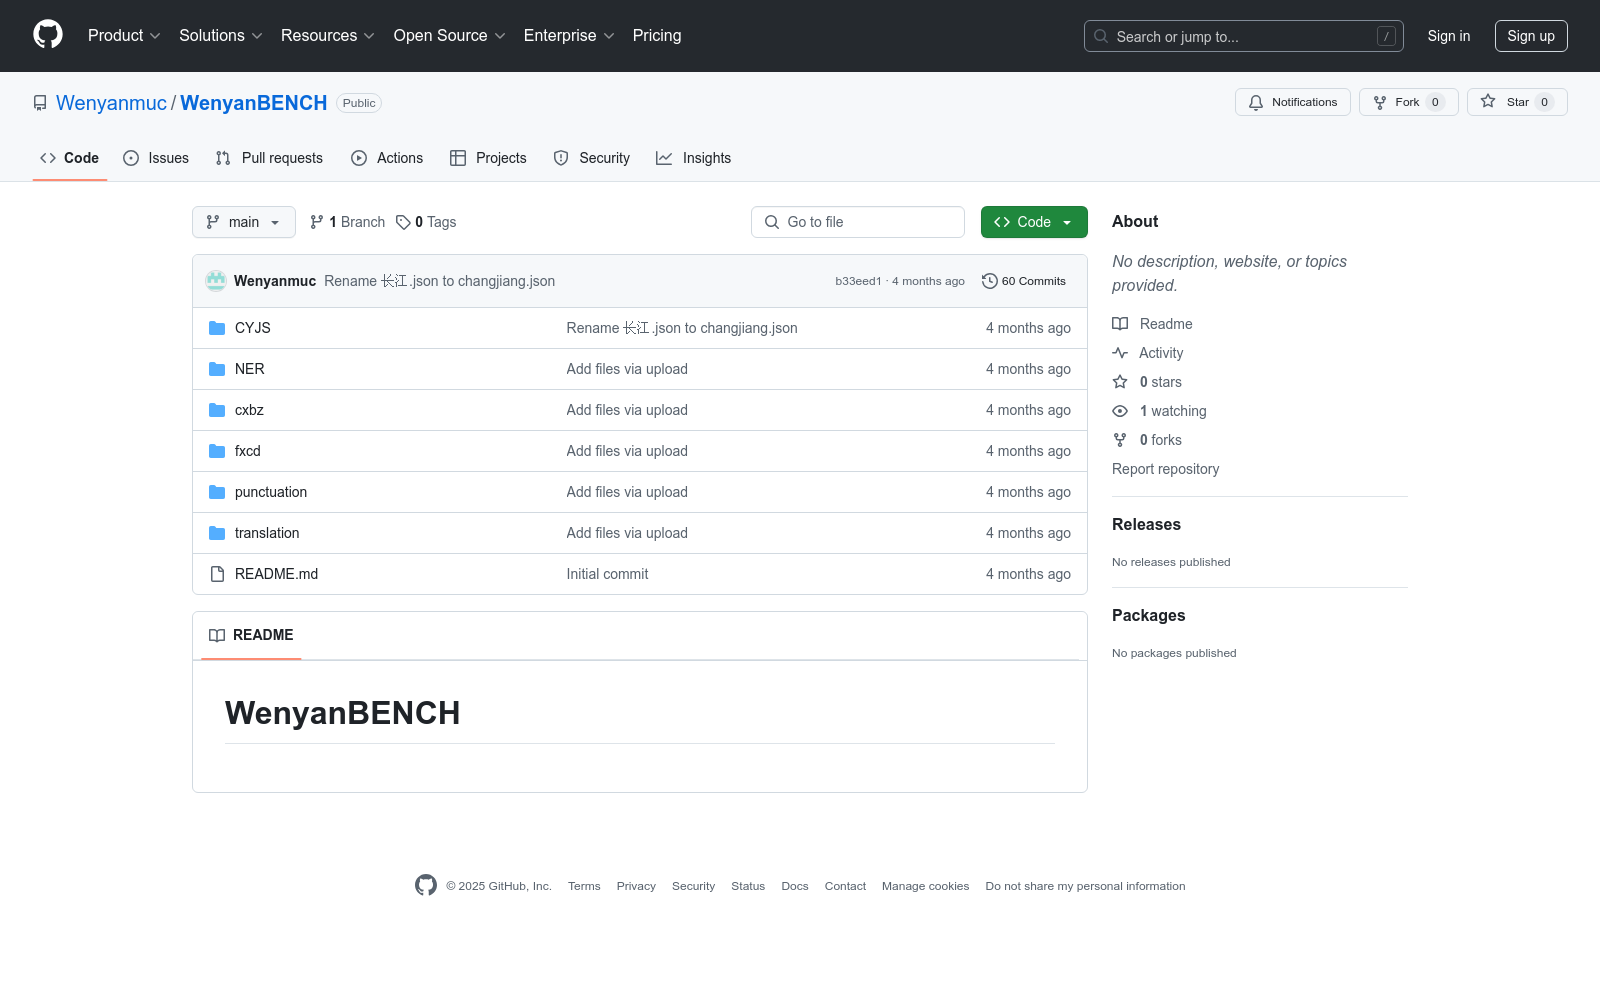
WenyanBENCH
收藏资源简介:
WenyanBENCH是一个专门为评估古汉语语言处理模型而设计的基准数据集。该数据集包含了古汉语的多种任务,如标点、词性标注、命名实体识别、翻译等,总计有25,953条数据。WenyanBENCH数据集由多个任务组成,包括14种标点符号的分类、17类古汉语词性的标注、4类命名实体的识别。数据集的来源与WenyanGPT模型的指令微调数据相同,并经过去重和人工及语言模型验证。该数据集旨在解决古汉语处理任务中缺乏标准化评估基准的问题,为研究者提供一个可靠的性能评估工具。
WenyanBENCH is a benchmark dataset specifically designed for evaluating classical Chinese language processing models. This dataset covers multiple classical Chinese language tasks including punctuation classification, part-of-speech tagging, named entity recognition, and translation, with a total of 25,953 data entries. The WenyanBENCH dataset consists of several specific tasks: classification of 14 types of punctuation symbols, annotation of 17 categories of classical Chinese part-of-speech, and recognition of 4 types of named entities. The dataset is sourced from the same instruction fine-tuning corpus as the WenyanGPT model, and has been deduplicated and verified by human annotators and language models. This dataset aims to address the lack of standardized evaluation benchmarks in classical Chinese language processing tasks, providing researchers with a reliable performance evaluation tool.
WenyanBENCH数据集概述
基本信息
- 数据集名称:WenyanBENCH
- 托管平台:GitHub
- 托管地址:https://github.com/Wenyanmuc/WenyanBENCH
数据集描述
(注:根据提供的README内容,该数据集未包含具体描述信息)
- 1WenyanGPT: A Large Language Model for Classical Chinese Tasks中国民族大学, 国家语言资源监测与研究 · 2025年


