YunzeLiu/OmniRetriever-Bench
收藏资源简介:
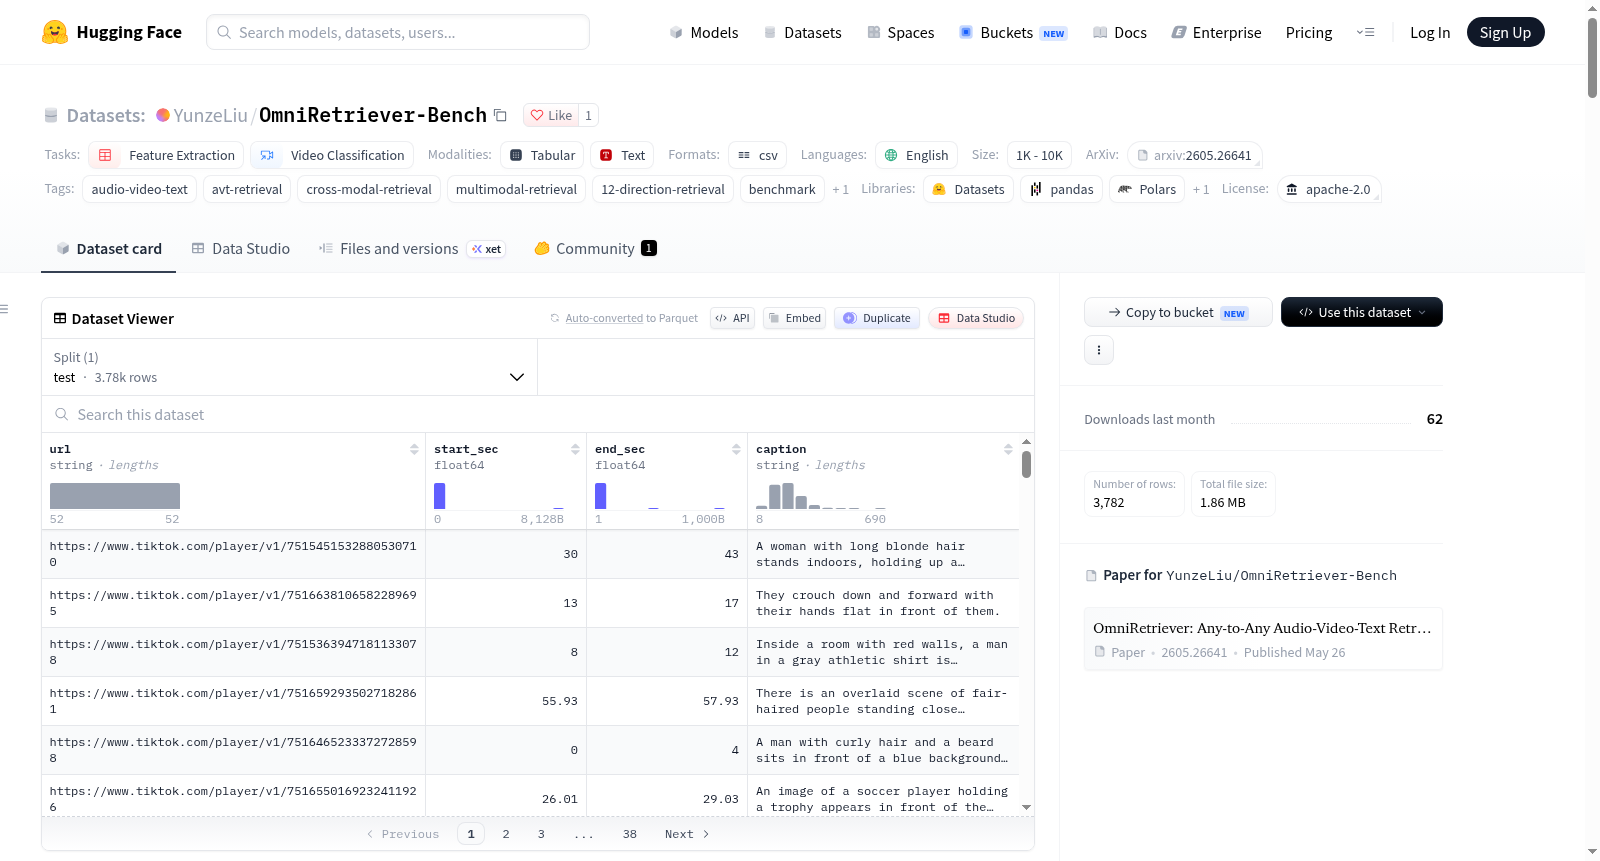
OmniRetriever-Bench 是第一个12方向音频-视频-文本检索基准数据集,包含3,782个经过人工审核的三元组(音频、视频、文本),用于评估跨模态检索模型。它覆盖6个单模态和6个双模态检索方向(如文本到视频、音频到文本等),所有文本描述基于Gemini 3.0 Pro生成并经过人工校正。数据集以CSV格式提供,包括视频URL、起止时间和文本描述,但不直接包含媒体文件,需通过URL下载并裁剪。该数据集旨在测试统一多模态编码器的性能,支持多模态检索和RAG系统研究。
OmniRetriever-Bench is the first 12-direction audio-video-text retrieval benchmark, consisting of 3,782 human-corrected triples (audio, video, text) for evaluating cross-modal retrieval models. It covers 6 single-modal and 6 dual-modal retrieval directions (e.g., text-to-video, audio-to-text), with captions drafted by Gemini 3.0 Pro and reviewed by human annotators. The dataset is provided in CSV format, including video URLs, start/end times, and captions, but does not redistribute media files; clips must be downloaded and trimmed via URLs. It is designed to test the performance of unified multimodal encoders and supports research on multimodal retrieval and RAG systems.