filedfact-passages
收藏资源简介:
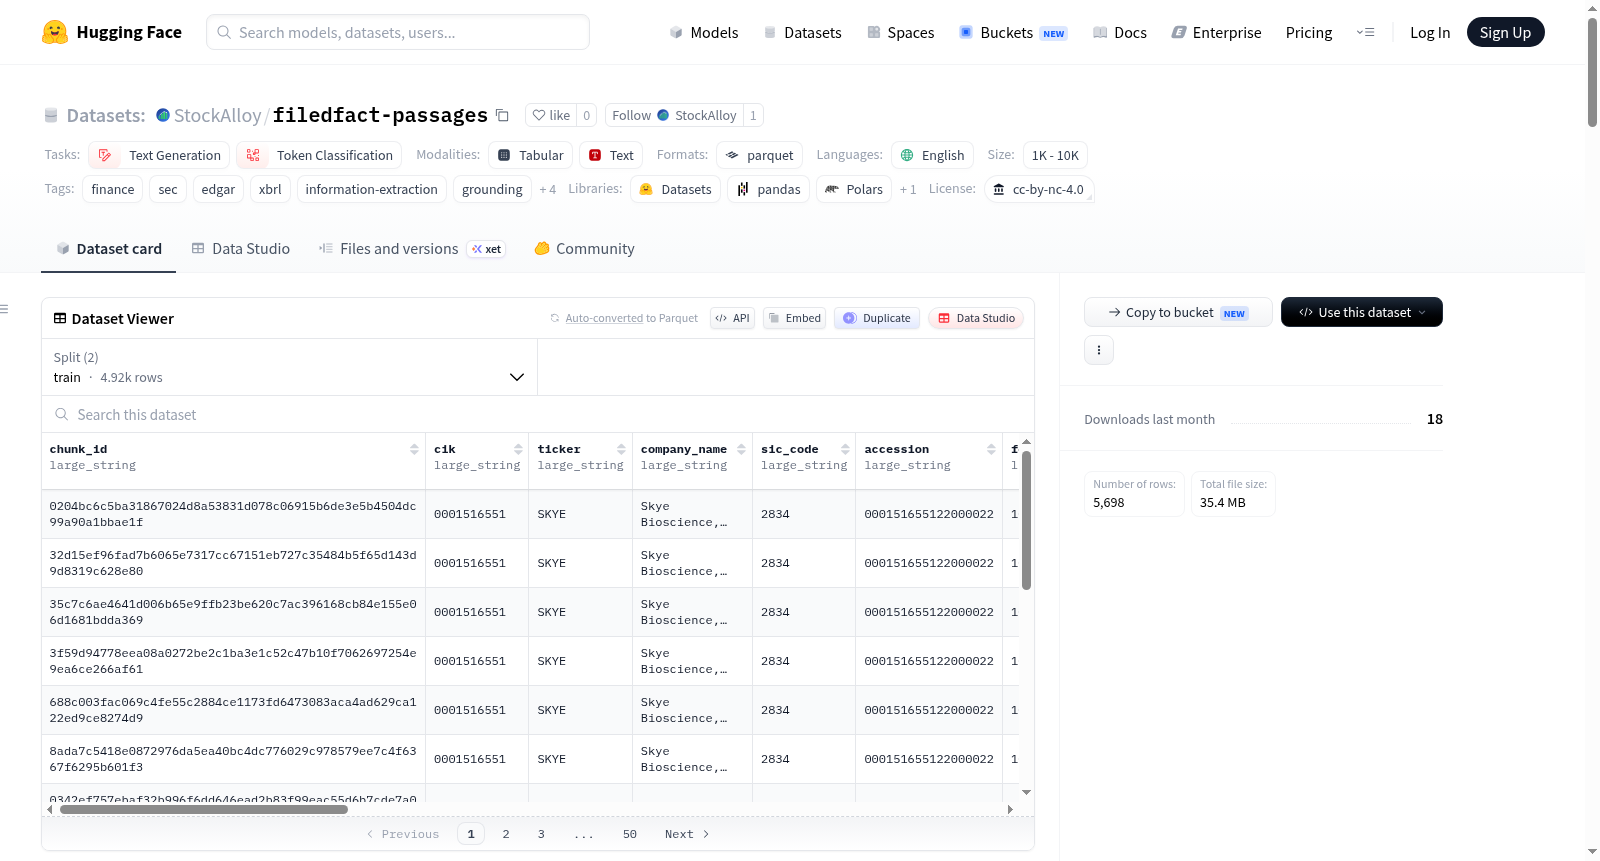
FiledFact-Passages 是一个用于从美国证券交易委员会(SEC)财务报告中提取结构化事实的数据集。它专注于“段落完整、片段定位”的提取任务,旨在为金融自然语言处理和信息抽取提供高质量的标注数据。数据集包含 5,698 个经过清理的 SEC 文件段落,涵盖财务报表、附注和管理层讨论与分析(MD&A)等内容。在这些段落中,共标注了 101,899 个“目标事实”,这些事实是文件中以数字形式可视化呈现的 XBRL(可扩展商业报告语言)事实。每个目标事实都通过精确的字符偏移量(text_start, text_end)定位在段落文本中,并附有完整的元数据,包括:XBRL 概念(concept)、经过标准化和单位换算后的完整数值(value)、报告期间(period)、单位(unit)、以及维度信息(dimensions,如业务部门、地区等)。此外,每个事实还包含一个证据链接(evidence_url),可直接在原始 SEC 文件中定位到该数字。除了目标事实,数据集还对段落中所有其他数字片段进行了标注,包括年份、日期、引用、文本中的百分比以及未标记的金额等,这些被归类为“非目标数字片段”(non_target_spans)。数据集的构建确保了每个可见的数字标记都被明确分配到上述两类之一。数据集按公司进行了划分,包含 4,922 个训练段落(来自 4,113 家公司)和 776 个验证段落(来自 765 家公司),总计涉及 4,878 家不同的公司。数据以嵌套结构存储,每个数据行代表一个完整的段落及其所有标注。该数据集适用于训练和评估从财务文本中进行细粒度信息抽取、实体链接、表格理解和事实核实的模型。
FiledFact-Passages is a dataset designed for extracting structured facts from U.S. Securities and Exchange Commission (SEC) financial reports. It focuses on the extraction task of paragraph-complete, span-localization, aiming to provide high-quality annotated data for financial natural language processing and information extraction. The dataset includes 5,698 cleaned SEC document paragraphs, covering financial statements, footnotes, and Managements Discussion and Analysis (MD&A) sections. Within these paragraphs, a total of 101,899 target facts are annotated, which are XBRL (eXtensible Business Reporting Language) facts visually presented as numbers in the documents. Each target fact is localized in the paragraph text with precise character offsets (text_start, text_end) and accompanied by comprehensive metadata, including: XBRL concept, fully standardized and unit-converted numerical value (value), reporting period (period), unit (unit), and dimension information (dimensions, such as business segments, regions, etc.). Additionally, each fact includes an evidence link (evidence_url) that directly locates the number in the original SEC file. Beyond target facts, the dataset also annotates all other numerical spans in the paragraphs, such as years, dates, references, percentages in text, and unlabeled amounts, categorized as non-target numerical spans (non_target_spans). The dataset construction ensures that every visible numerical token is explicitly assigned to one of these two categories. The dataset is partitioned by company, comprising 4,922 training paragraphs (from 4,113 companies) and 776 validation paragraphs (from 765 companies), involving a total of 4,878 distinct companies. Data is stored in a nested structure, with each data row representing a complete paragraph and all its annotations. This dataset is suitable for training and evaluating models for fine-grained information extraction, entity linking, table understanding, and fact verification from financial texts.
数据集概述:FiledFact-Passages
FiledFact-Passages 是一个面向金融领域的英文数据集,专为从美国证券交易委员会(SEC)EDGAR系统提交的XBRL格式文件中提取结构化财务事实而设计。该数据集提供了完整的文档段落级数据,每个财务事实都精确关联到原文中的具体字符位置(span grounding)。
核心数据规模
- 总段落数: 5,698 条(涵盖财务报表表格、附注及管理层讨论与分析)
- 覆盖公司: 4,878 家
- 标注事实总数: 101,899 个(所有在文档中可见渲染的XBRL财务事实)
- 非目标数字跨度: 50,658 个(包括年份、日期、引用、百分比及其他未标记数字)
数据划分
- 训练集: 4,922 段落(87,539 个事实,来自 4,113 家公司)
- 验证集: 776 段落(14,360 个事实,来自 765 家公司)
- 特点: 训练集与验证集的公司不重叠
任务定义
输入: 一条财务文件段落(附带可选的上下文信息)。
输出: 段落中所有可见的XBRL金融事实(包括每个事实的概念、数值、单位、周期、维度以及精确的字符偏移量)。部分段落不包含任何目标事实,用于训练模型识别并返回空列表。
数据字段与结构
段落字段(Passage Fields)
| 字段 | 描述 |
|---|---|
chunk_id |
稳定段落ID,作为扁平表连接键 |
cik, ticker, company_name, sic_code |
发行实体身份信息 |
accession, form_type, filed_at |
文件身份与提交时间 |
fiscal_year, fiscal_period |
文件层面的会计期间 |
chunk_type, heading, pre_context |
段落位置与邻近上下文 |
text |
清洗后的段落文本(表格单位用竖线分隔) |
source_url |
SEC文件链接 |
facts_count |
目标事实数量 |
scale_cue_in_text, sample_stratum |
展示与采样元数据 |
facts |
嵌套的目标事实记录 |
non_target_spans |
嵌套的非目标数字跨度记录 |
事实字段(Fact Fields)
| 字段 | 描述 |
|---|---|
fact_id |
稳定事实ID |
concept |
带命名空间限定的XBRL概念 |
period |
时间(instant:日期 或 duration:开始..结束) |
value |
保留精度并归一化后的完整单位数值 |
unit |
单位类型(如 monetary:USD, per_share:USD, shares, pure) |
displayed_text |
段落中展示的确切字符 |
text_start, text_end |
在text中的半开字符偏移量 |
scale |
展示时的10的幂次缩放 |
decimals, format |
文件中的四舍五入与数字格式元数据 |
dimensions |
维度范围(如业务分部、产品、地域) |
evidence_url |
定位到文件中对应数字的链接 |
非目标跨度字段: 每个记录包含 span_text, start, end 和 class。
关键特性与标注策略
- 段落完整性: 每个段落包含目标事实 (
facts) 和非目标数字跨度 (non_target_spans),确保所有可见数字被分类。 - 精确字符定位:
text_start和text_end确保每个事实可精确追溯到原文。 - 值归一化:
value字段存储应用符号、缩放和数字格式后的归一化完整单位值。 - 维度记录:
dimensions字段记录业务分部、产品、地域等维度范围。 - 证据链接:
evidence_url可直接在SEC文件中打开对应数字位置。
数据来源与许可
- 数据来源: 美国SEC EDGAR系统的XBRL财务文件(财务报表、附注、管理层讨论与分析)
- 许可证: CC BY-NC 4.0(非商业用途)
- 数据集版本: v1.2
- 商业访问/定制数据: 联系 data@stockalloy.com
关联资源
- 兄弟数据集: FiledFact-100K(每行一个接地事实)
- 配套模型: FiledFact-Qwen3-8B(模型卡包含提取提示、输出格式、基准协议和结果)