Speech Emotion Recognition Dataset
收藏资源简介:
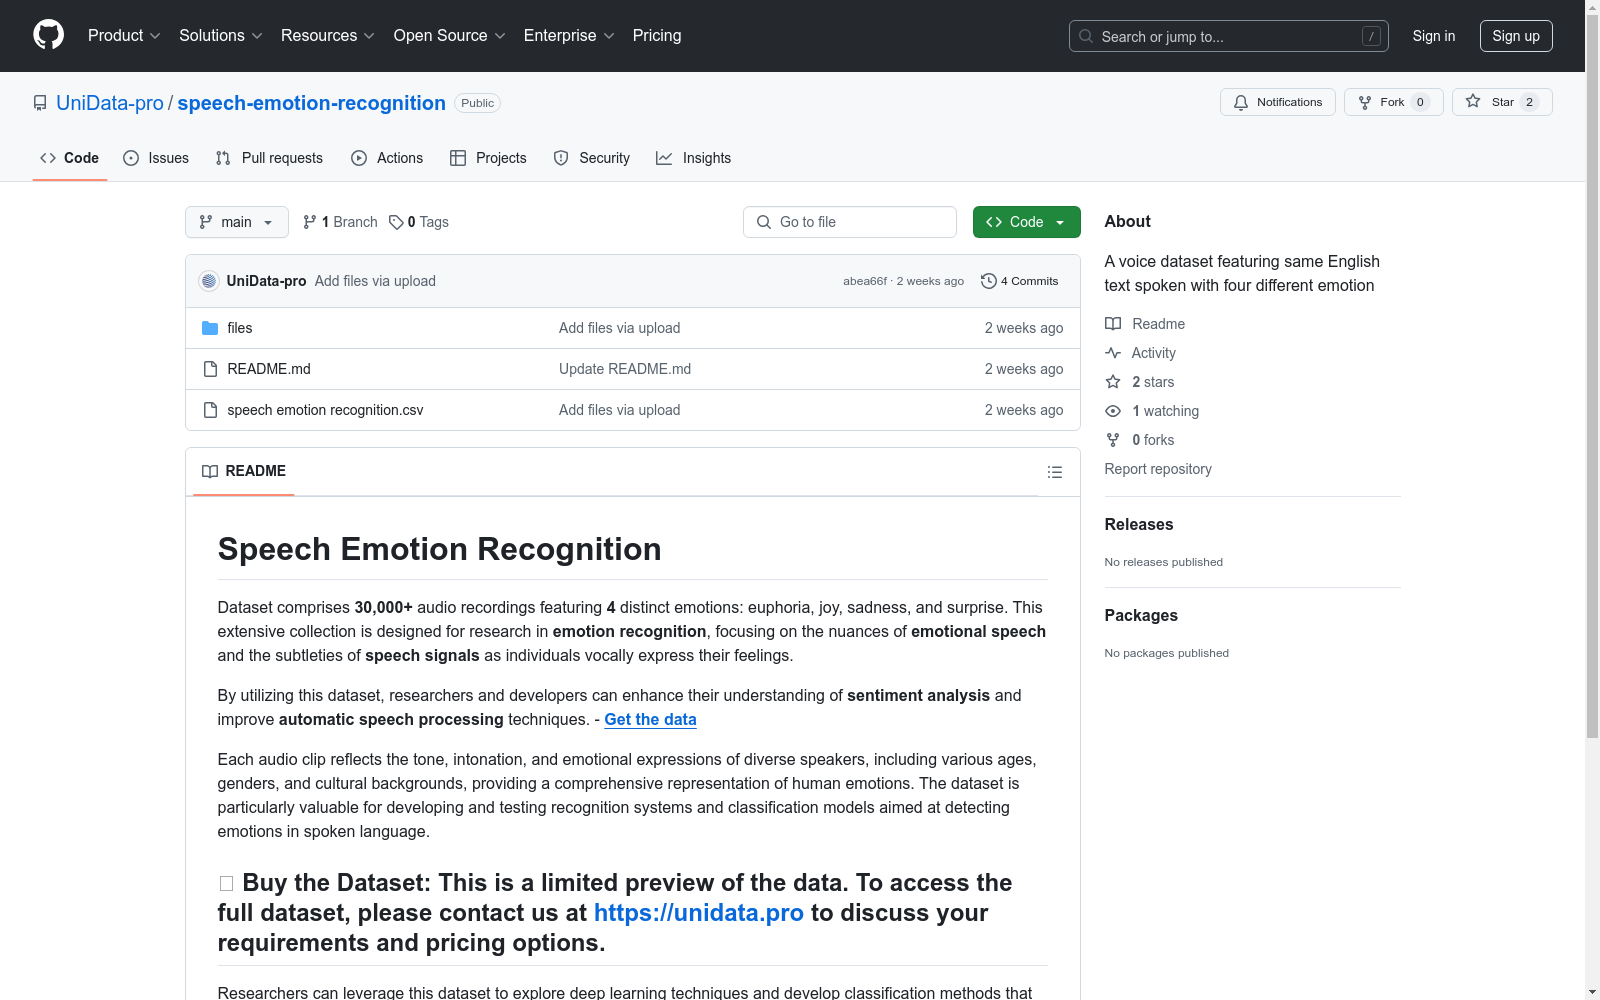
该数据集包含超过30,000个音频记录,涵盖4种不同的情感:欣快、喜悦、悲伤和惊讶。这个广泛的集合旨在研究情感识别,重点关注情感语音的细微差别和语音信号的微妙之处,因为人们通过声音表达他们的感受。每个音频片段反映了不同说话者的语调、语调和情感表达,包括各种年龄、性别和文化背景,提供了人类情感的全面代表。该数据集对于开发和测试旨在检测口语中情感的识别系统和分类模型特别有价值。
This dataset contains over 30,000 audio recordings covering four distinct emotions: euphoria, joy, sadness, and surprise. This extensive corpus is designed for emotion recognition research, focusing on the nuances of emotional speech and the subtleties of speech signals, as people express their emotions via vocal cues. Each audio clip reflects the intonation, rhythm, and emotional expressions of different speakers, encompassing diverse age groups, genders, and cultural backgrounds to provide a comprehensive representation of human emotions. This dataset is particularly valuable for developing and testing recognition systems and classification models aimed at detecting emotions in spoken language.
语音情感识别数据集
数据集概述
- 数据量:30,000+ 音频记录
- 情感类别:4 种(欣快、喜悦、悲伤、惊讶)
- 应用领域:情感识别、情感语音研究、语音信号分析、情感分析、自动语音处理技术
数据集特点
- 多样性:包含不同年龄、性别和文化背景的说话者
- 情感表达:音频片段反映了说话者的语调、语调和情感表达
- 研究价值:适用于开发和测试情感识别系统和分类模型
数据集获取
- 预览版本:提供有限预览
- 完整数据集:需联系 UniData 获取完整数据集,讨论需求和定价
研究应用
- 深度学习:探索深度学习技术,开发分类方法,提高情感检测的准确性
- 情感计算:推动情感计算的发展,增强语音合成技术