
WideSearch
收藏资源简介:
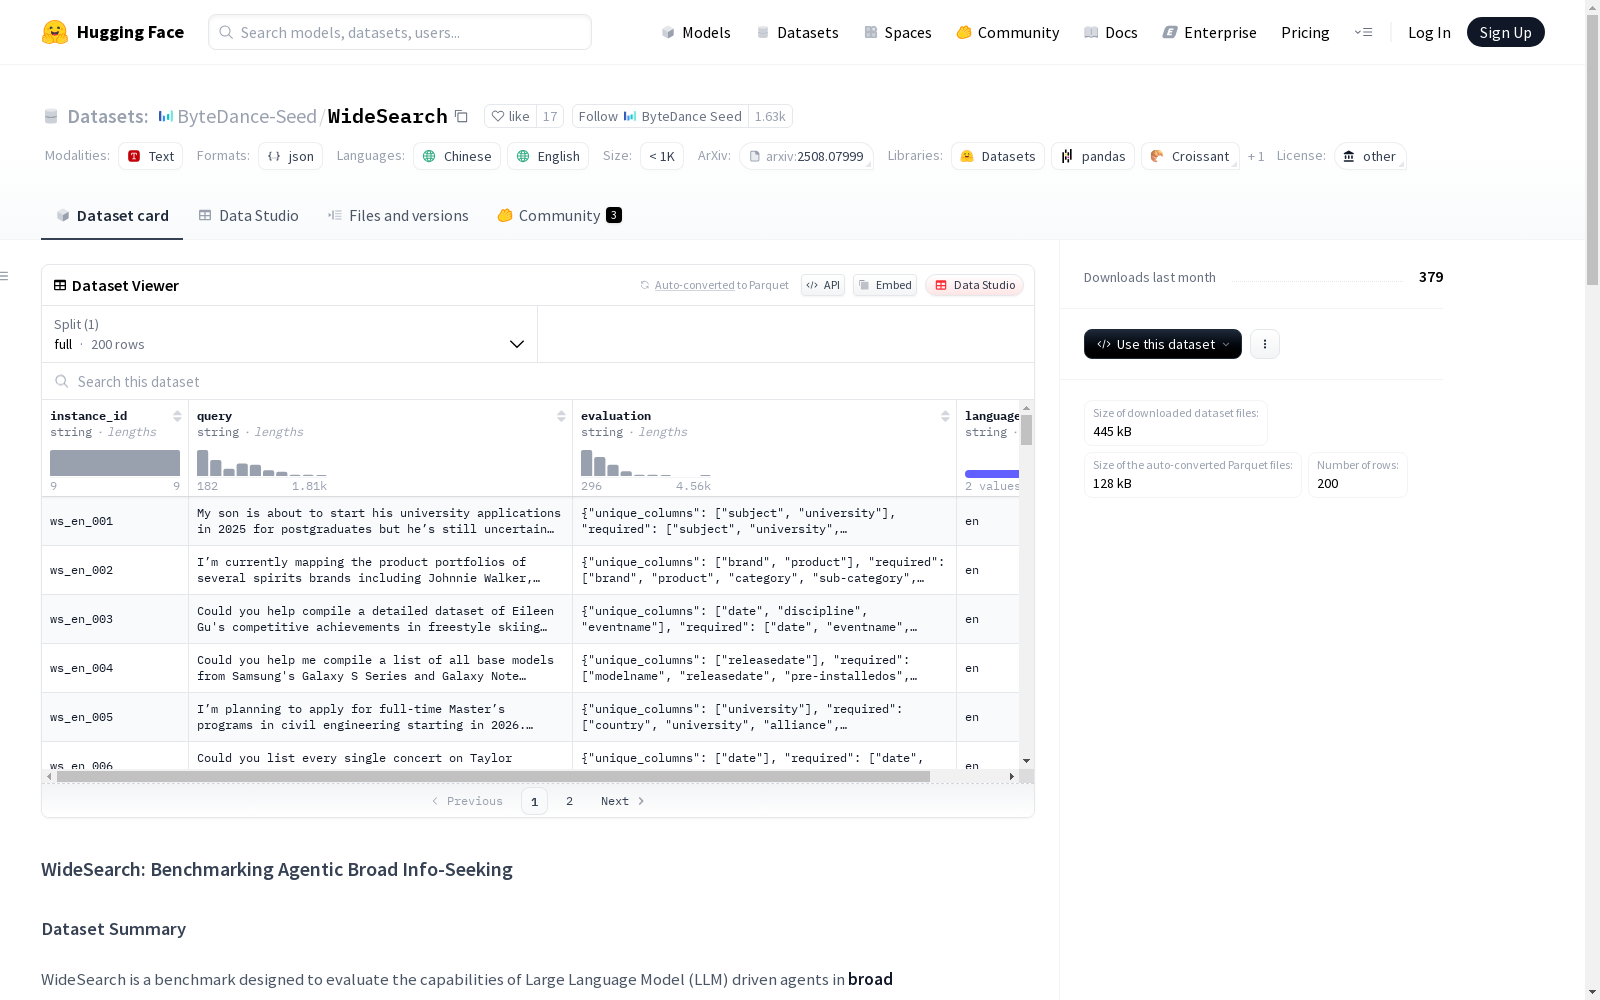
WideSearch数据集是一个为评估代理在大规模信息收集任务上的可靠性而设计的新基准。该数据集包含200个手动策划的问题(100个英文,100个中文),涵盖了超过15个不同的领域,并基于真实用户查询。每个任务都需要代理收集大规模的原子信息,并客观地逐一验证,然后将其组织成一个井井有条的输出。一个严格的五阶段质量控制流程确保了数据集的难度、完整性和可验证性。
The WideSearch dataset is a novel benchmark designed to evaluate the reliability of AI Agents in large-scale information collection tasks. It contains 200 manually curated questions (100 in English and 100 in Chinese), covering more than 15 distinct domains and derived from real user queries. Each task requires the agent to collect large-scale atomic information, verify each piece of information objectively one by one, and then organize it into a well-structured final output. A rigorous five-stage quality control pipeline is implemented to ensure the dataset's difficulty, completeness, and verifiability.
WideSearch 数据集概述
数据集简介
- 目的:评估大型语言模型(LLM)驱动代理在广泛信息搜索任务中的能力。
- 特点:专注于收集大量分散但易于查找的信息,而非单一难以找到的事实。
- 任务示例:金融分析师收集行业关键指标、求职者收集符合条件的职位空缺。
- 任务数量:200个(100个英文,100个中文)。
- 研究论文:WideSearch: Benchmarking Agentic Broad Info-Seeking
- GitHub仓库:ByteDance-Seed/WideSearch
数据集结构
- 文件组成:
widesearch.jsonl:包含所有任务的JSON Lines文件。widesearch_gold/:包含每个任务的真实答案(CSV格式)。
数据实例
- 字段说明:
instance_id:任务唯一标识符,对应widesearch_gold目录中的CSV文件名。query:自然语言指令,详细说明任务要求、数据列和最终Markdown表格格式。evaluation:包含自动评估所需的所有信息。unique_columns:表格中的主键列。required:必须出现在代理生成响应中的所有列名。eval_pipeline:定义每列的评估方法。
language:任务语言(en或zh)。
真实数据
- 来源:由人类专家通过详尽的网络搜索和交叉验证创建。
- 格式:CSV文件,文件名与
instance_id对应。
引用
bibtex @misc{wong2025widesearchbenchmarkingagenticbroad, title={WideSearch: Benchmarking Agentic Broad Info-Seeking}, author={Ryan Wong and Jiawei Wang and Junjie Zhao and Li Chen and Yan Gao and Long Zhang and Xuan Zhou and Zuo Wang and Kai Xiang and Ge Zhang and Wenhao Huang and Yang Wang and Ke Wang}, year={2025}, eprint={2508.07999}, archivePrefix={arXiv}, primaryClass={cs.CL}, url={https://arxiv.org/abs/2508.07999}, }
- 1WideSearch: Benchmarking Agentic Broad Info-Seeking字节跳动 · 2025年


