AlignBench
收藏资源简介:
AlignBench是由欧姆龙SINIC X公司与大阪大学联合构建的细粒度图文对齐基准数据集,旨在评估视觉语言模型的精细语义对齐能力。该数据集包含89,473条标注语句,平均句长17.7词,词汇量达42,000,数据源涵盖六种图像描述模型和两种文生图模型的生成结果。数据集通过两阶段标注流程构建,首先由众包工作者进行句子级正确性标注,再经专家审核确保质量,并额外提供幻觉类型细分标签。该数据集主要应用于评估视觉语言模型在复杂场景下的图文对齐能力,为解决多模态模型幻觉检测和合成数据清洗等关键问题提供基准支撑。
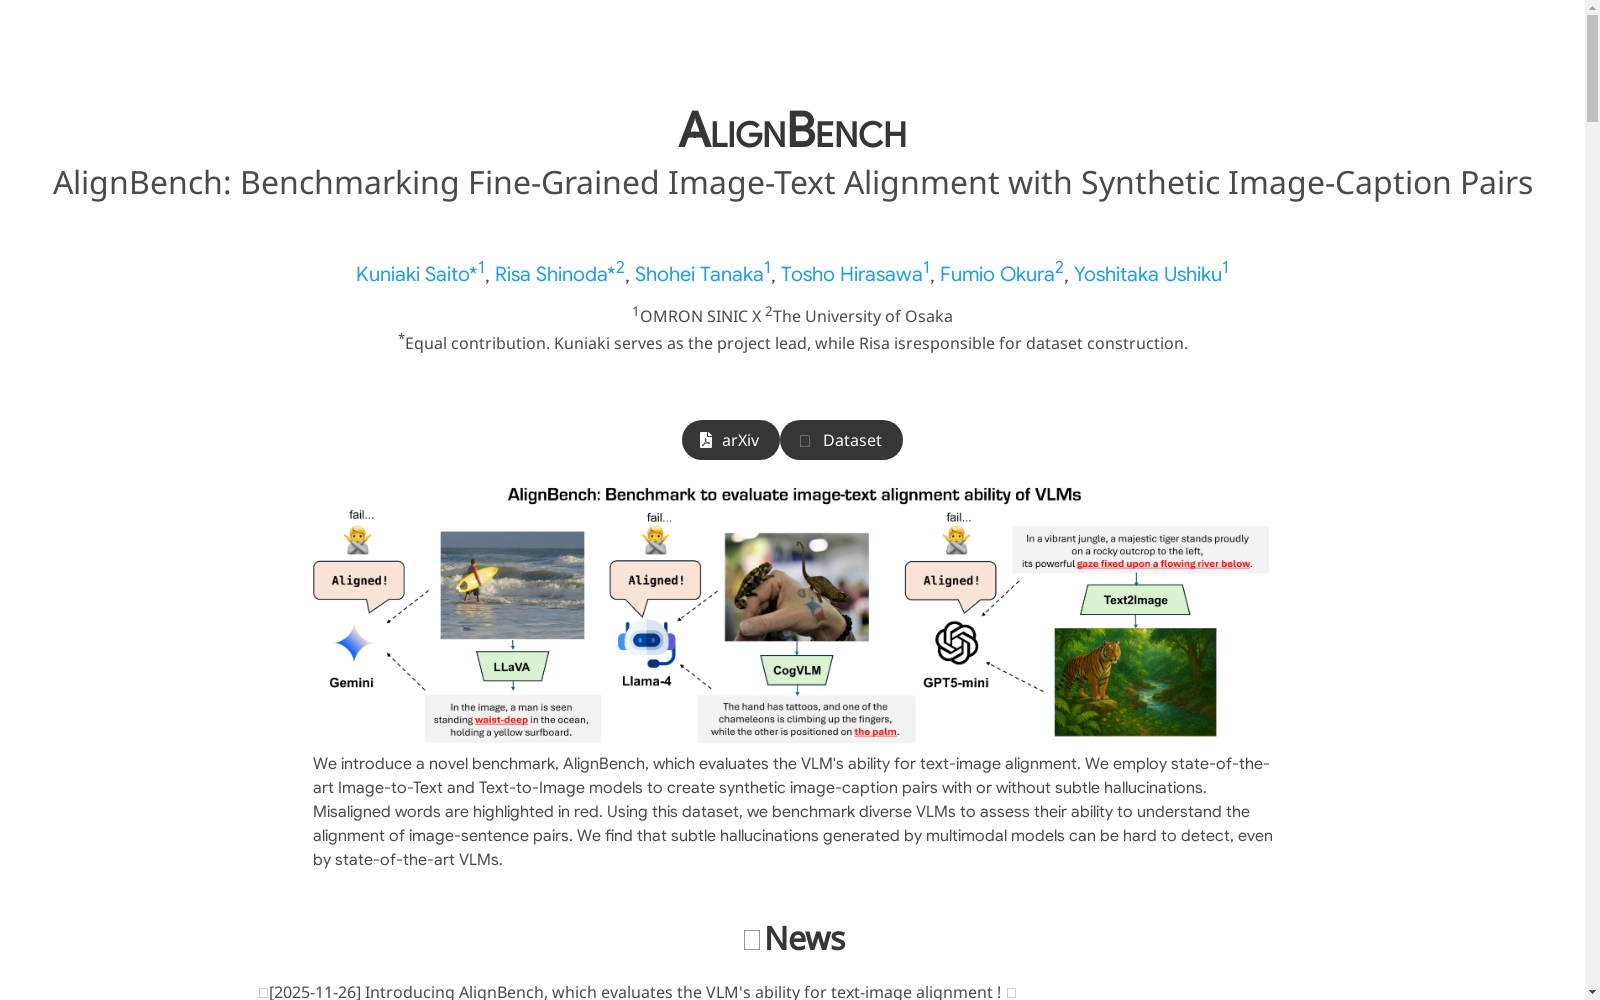
AlignBench is a fine-grained image-text alignment benchmark dataset jointly constructed by Omron SINIC X Corporation and Osaka University, which is designed to evaluate the fine-grained semantic alignment capabilities of vision-language models. This dataset contains 89,473 annotated sentences, with an average sentence length of 17.7 words and a vocabulary size of 42,000. Its data sources cover the generation outputs of six image captioning models and two text-to-image models. The dataset is built through a two-stage annotation workflow: first, crowd workers perform sentence-level correctness annotation, followed by expert reviews to ensure data quality, and additionally provides fine-grained sub-type labels for hallucinations. This dataset is mainly used to evaluate the image-text alignment capabilities of vision-language models in complex scenarios, providing benchmark support for solving key problems such as multimodal model hallucination detection and synthetic data cleaning.
AlignBench 数据集概述
基本信息
- 数据集名称:AlignBench
- 主要功能:评估视觉语言模型在图文对齐方面的能力
- 创建方式:使用先进的图像到文本和文本到图像模型生成带有或不带有细微幻觉的合成图像-标题对
- 标注特征:未对齐的单词用红色高亮显示
核心特点
- 评估重点:细粒度图文对齐能力
- 数据构成:包含详细图像-标题对,每个句子都标注了正确性
- 挑战性:多模态模型产生的细微幻觉难以被最先进的视觉语言模型检测
关键发现
- CLIP系列模型在组合对齐方面表现近乎盲目
- 检测器系统性地对早期句子评分过高
- 模型表现出强烈的自我偏好,偏向自身输出并损害检测性能
数据集统计
- 包含大量带标注的句子,足以进行模型基准测试
- 排除了标签未知的句子
- 错误分布特征:
- 所有标题生成器在第一个位置出错较少
- 大多数错误发生在属性和文本类别中
性能表现
- GPT-5在所有模型中表现最佳
- Llama-4是最佳开源模型
- 模型规模增大可提升性能
- 不同视觉语言模型对文本到图像模型的鲁棒性存在差异
相关资源
- 论文地址:https://arxiv.org/abs/2511.20515
- 数据集地址:https://dahlian00.github.io/AlignBench/