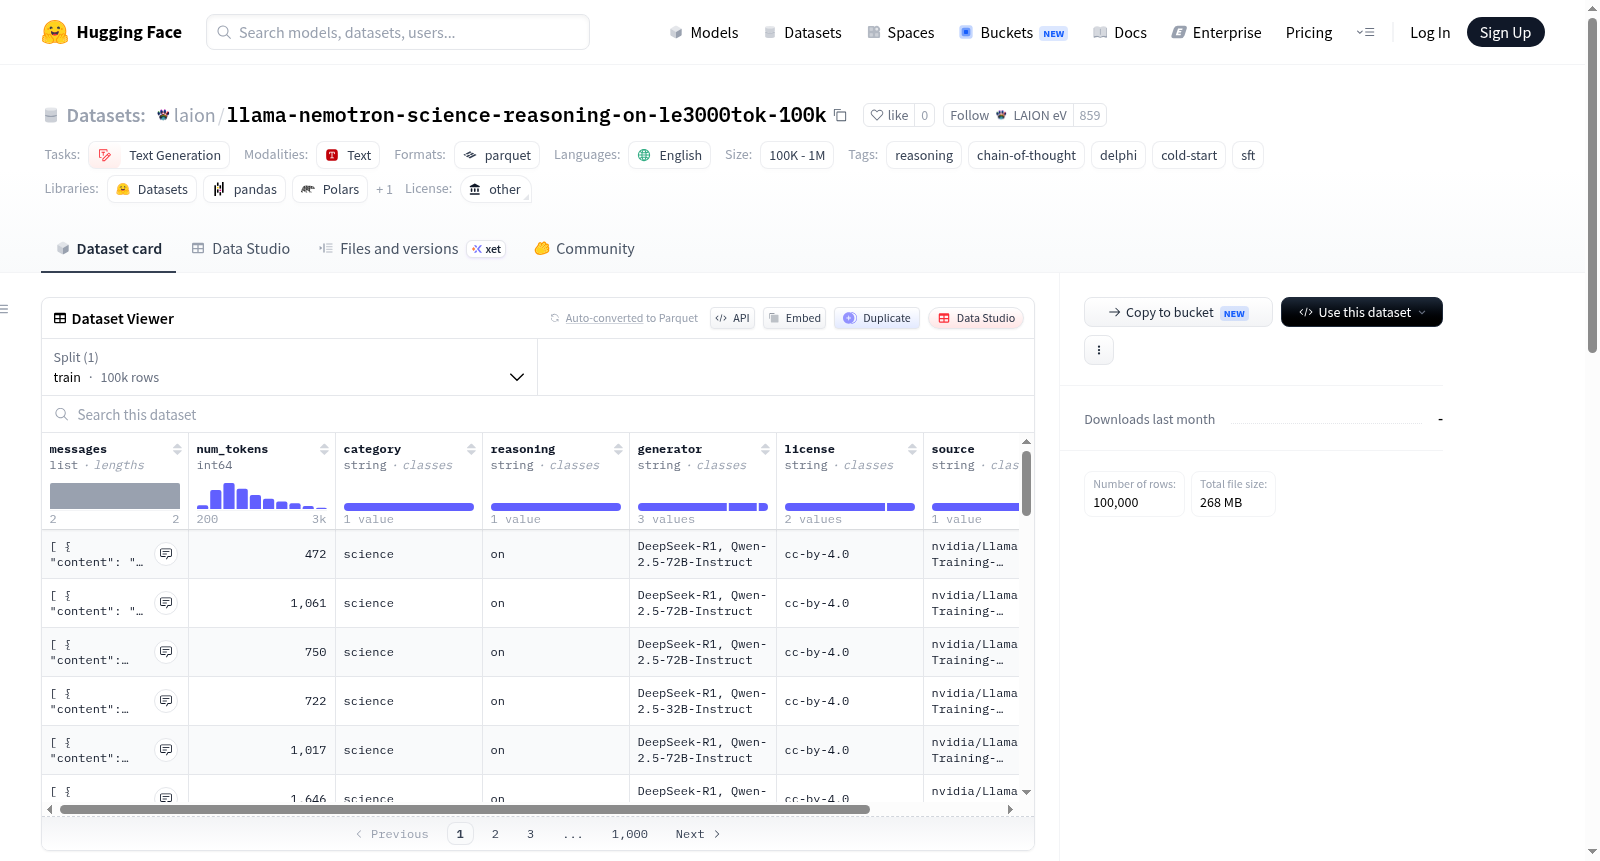
llama-nemotron-science-reasoning-on-le3000tok-100k
收藏资源简介:
Llama-Nemotron科学推理数据集是nvidia/Llama-Nemotron-Post-Training-Dataset的一个过滤子样本,专门设计用于在冷启动监督微调(SFT)过程中预热Delphi聊天模板的推理标记(如<|start_think|>和<|end_think|>)。该数据集仅包含原始数据集中SFT/science子集且推理模式为开启的长思维链示例,排除了SFT/code和数学子集,以专注于推理模板的预热而非知识学习。所有样本的输入和输出总长度被限制在3000个标记以内(使用Delphi/Llama-3.1分词器测量),并通过均匀随机抽样选取了100,000行数据。数据格式采用ShareGPT风格的消息列表,其中助手回复包含内联的思维链块(在编码时会被规范化为标准推理标记)。数据集包含多个字段:messages(对话消息)、num_tokens(标记数量)、category(科学类别)、reasoning(推理模式)、generator(生成模型)、license(许可协议)和source(数据来源)。主要用途是训练模型使用推理模板和思维到答案的结构,适用于需要预热思维链推理能力的自然语言生成任务,特别是科学领域的推理任务。
The Llama-Nemotron Scientific Reasoning Dataset is a filtered subsample of the nvidia/Llama-Nemotron-Post-Training-Dataset, specifically designed for warming up the reasoning tokens (<|start_think|> and <|end_think|>) of the Delphi chat template during the cold-start supervised fine-tuning (SFT) process. It includes only long chain-of-thought examples from the SFT/science subset of the original dataset with reasoning mode on, excluding the SFT/code and math subsets to ensure focus on reasoning template warm-up rather than knowledge learning. All samples have a total input and output length limited to 3000 tokens (measured using the Delphi/Llama-3.1 tokenizer), and 100,000 rows were selected through uniform random sampling. The data format follows the ShareGPT-style message list, where assistant responses contain inline thought chain blocks (which are normalized to standard reasoning tokens during encoding). The dataset includes multiple fields: messages (dialogue messages), num_tokens (token count), category (scientific category), reasoning (reasoning mode), generator (generation model), license (license agreement), and source (data source). Its primary purpose is to train models to use reasoning templates and thought-to-answer structures, suitable for natural language generation tasks requiring warm-up of chain-of-thought reasoning capabilities, particularly in scientific reasoning tasks.
数据集概述
数据集名称:Llama-Nemotron science reasoning — Delphi cold-start CoT warmup (≤3000 tok, reasoning:on, 100k)
语言:英语(en)
许可:其他(other),衍生自 NVIDIA 的数据集,具体行级许可包括 cc-by-4.0 和 cc-by-sa。
数据量:10K < n < 100K(实际为 100,000 行)
任务类别:文本生成(text-generation)
标签:推理(reasoning)、思维链(chain-of-thought)、Delphi、冷启动(cold-start)、监督微调(sft)
数据集来源与构建目的
- 来源:从 nvidia/Llama-Nemotron-Post-Training-Dataset 中过滤并子采样得到。
- 目的:用于在冷启动监督微调(cold-start SFT)过程中,预热 Delphi 聊天模板的推理令牌(
<|start_think|>/<|end_think|>)。这是一个模板/思维链的预热切片,而非知识数据集。
过滤条件
- 子集选择:仅使用
SFT/science子集,排除了SFT/code子集(因约 98.6% 的推理轨迹超过 3000 令牌预算)。数学子集也故意排除,避免在预热中添加数学练习。 - 推理标记:仅保留
reasoning == "on"的样本,即包含详细思维链(“detailed thinking on”)的示例。 - 长度限制:使用 Delphi / Llama-3.1 分词器(
marin-community/delphi-3e18-447Mparams-1.2Btokens词汇表),基于input + output的长度 ≤ 3000 令牌。保守上限旨在仅训练模板令牌和思考→回答的格式,而非长推理。 - 随机子采样:通过蓄水池算法(种子=0)均匀随机子采样至 100,000 行。
数据格式
每条记录包含以下字段:
messages:ShareGPT 格式的[{role, content}]。助手回答中包含一个内联的<think>...</think>块,后接答案。在编码时,Delphi 的 LLaMA-Factory 模板会将内联的<think>规范化为标准的<|start_think|>/<|end_think|>令牌。num_tokens:基于 Delphi 分词器计算的输入+输出令牌数(≤ 3000)。category:固定为science。reasoning:固定为on。generator:生成器来源,包括DeepSeek-R1、DeepSeek-R1, Qwen-2.5-32B-Instruct、DeepSeek-R1, Qwen-2.5-72B-Instruct。license:行级许可信息。source:来源数据集。
用途与限制
- 适用场景:仅用于预热聊天模板的推理令牌,以准备后续的强化学习(RL)阶段。
- 不适用场景:不适合教授新知识或数学技能,该数据集是一个小型的、长度受限的切片,仅用于安装推理令牌。